API-Based Backlink Indexing: The Modern Approach
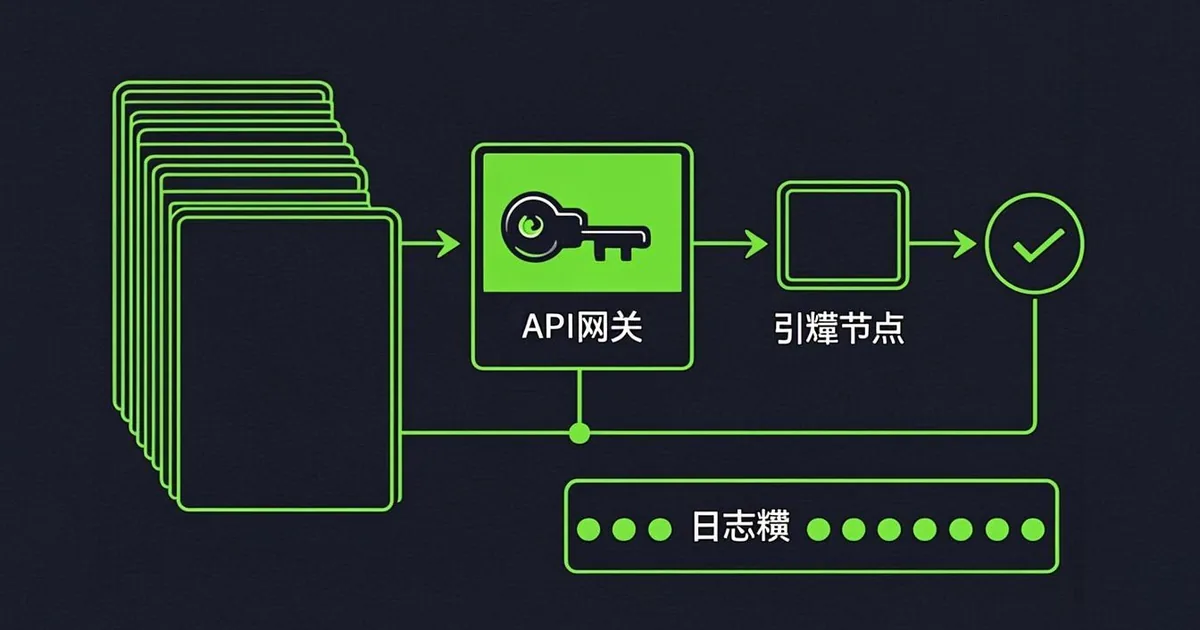
Old link pools promised fast indexing through tricks. This guide shows a cleaner path for teams asking about api based link indexing and how to run it without spam. You will learn which official APIs accept which URLs, how to build a simple queue with logging and backoff, how to prioritize owned URLs that support your backlinks, and how to measure crawl and coverage gains. The focus keyword api based link indexing appears early to set intent. The approach fits small teams, uses keys you control, and respects quotas and ownership rules.
Key takeaways
- API indexing submits owned URLs with auth, pacing, and logs.
- IndexNow covers participating engines, Google API covers narrow types.
- Queue, deduplicate, back off on 429, and measure against a control.
- Run a quiet weekly routine that respects quotas and ownership.
- What API Based Link Indexing Means in Plain Terms
- Which APIs can submit backlink URLs today
- How a clean submission workflow looks end to end
- Setting up queues, logs, and safe retry rules
- How to prioritize which backlink URLs to submit first
- Measuring crawl visits and index coverage after submit
- Running API indexing week after week without spam
- FAQ
- Sources
- Further reading

What API Based Link Indexing Means in Plain Terms
API based backlink indexing means submitting changed URLs through official endpoints you control instead of hoping pools get crawled. For api based link indexing, you keep a queue of important backlink related URLs you own or manage, send them with proper auth and logging, and watch crawl and coverage responses. You do not submit third party pages you do not control to endpoints that require ownership. This section defines the scope clearly, lists what belongs in the queue and what does not, and explains why transparency and ownership make this approach durable.
To make progress on what api based backlink indexing means in plain terms, start with live evidence rather than assumptions. Open the URL in a clean browser session, view source, and compare it with the rendered DOM. Note the title, meta robots, canonical link, headings, and main body length in both views. Then fetch response headers to confirm status code, content type, X Robots Tag, cache directives, and redirect chain length. For api based link indexing, these first facts decide whether deeper work is needed or whether a single header or tag explains the symptom. Record the date, template name, and test URLs so later changes can be tied to outcomes without guesswork.
Practical checks for what api based backlink indexing means in plain terms work best as a short checklist with owners and dates. Confirm crawl access in robots.txt for the exact path and user agent, confirm index permission in meta and headers, confirm the canonical target returns 200 and allows indexing, confirm sitemap inclusion only for preferred URLs, and confirm at least a few relevant internal inlinks from indexed hubs. For api based link indexing, each check takes minutes but together they catch most blocks. Log which check failed for each sample so the repair targets the true source instead of applying broad changes that risk new issues.
Checklist for what api based backlink indexing means in plain terms:
- Confirm live status, headers, and rendered output on two samples from this template.
- Compare Search Console samples with crawl exports grouped by template and path.
- Align sitemap entries, internal anchors, and canonical targets to one preferred URL form.
- Fix the template or setting once, then retest across post types and archives.
- Purge page cache and edge cache, then recheck logged out HTML and headers.
- Log the change with dates and watch valid indexed counts for two weeks.
| Check for api based link indexing | What to look for | Next step |
|---|---|---|
| --- | --- | --- |
| Crawl access | robots result and log fetch rate | Narrow the exact disallow or allow pattern |
|---|---|---|
| Index permission | meta robots and X Robots Tag | Remove noindex from the true source layer |
| Canonical clarity | declared versus selected URL | Point all cues to one 200 indexable target |
|---|---|---|
| Internal support | inlink count and click depth | Add hub and contextual links with clear anchors |
Example: a site working on api based link indexing found that what api based backlink indexing means in plain terms affected one template more than others. The team listed fifty sample URLs, added template and inlink columns, and saw that archive pages carried the same canonical as single posts while receiving almost no internal links. They updated the template so archives self reference only when they add unique value, added three contextual links from related hubs to priority singles, cleaned the sitemap to preferred URLs only, and purged cache. Live tests then showed consistent canonicals, logs showed steadier fetching of the priority section, and the valid indexed trend rose without bulk resubmits. For more context on adjacent coverage states, see IndexNow vs Google Indexing API Which Should You Use which explains how discovery and crawl states connect to this fix.
Next, widen the lens from one URL to its template group. For api based link indexing, single page fixes rarely move coverage because the same include, plugin, or layout rule affects hundreds of pages. Export Search Console samples for the relevant status, add columns for template, word count, inlink count, canonical target, and sitemap presence, then sort by template. When what api based backlink indexing means in plain terms clusters on one layout, the fix belongs in code or settings, not in the editor. When it spreads across layouts, look at sitewide signals such as navigation depth, crawl budget pressure, or recent deploy dates that shifted many pages at once.
Do not overlook rendering and performance. For api based link indexing, JavaScript that injects main content late, lazy loads critical links, or blocks CSS and scripts can make a healthy page look thin to crawlers. Test raw versus rendered word counts, list blocked resources reported in live tests, and confirm that canonicals, hreflang, and structured data appear in rendered HTML as well as source. Compress images, stabilize response times, and ensure the edge cache serves bots the same HTML as browsers. Faster stable rendering helps every other fix for what api based backlink indexing means in plain terms get noticed sooner.
curl -I https://example.com/sample-pageWhich APIs can submit backlink URLs today
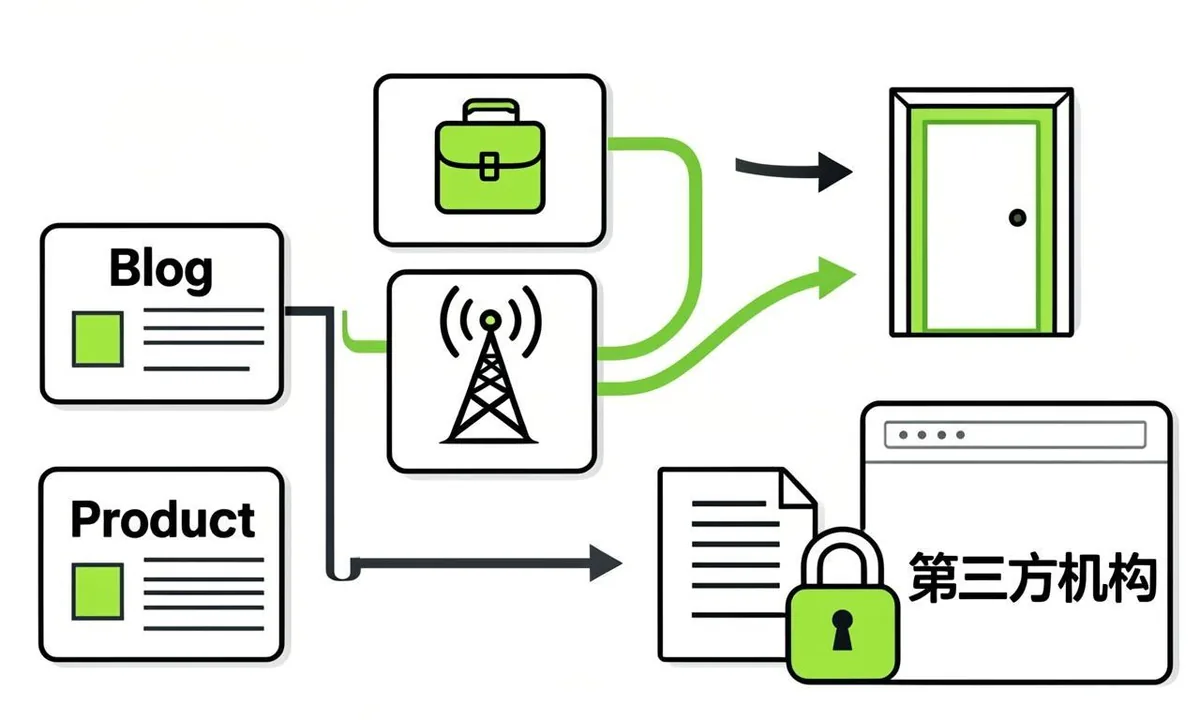
Several official paths exist with different coverage. For api based link indexing, IndexNow covers Bing, Yandex, and partners for hosts you control, while the Google Indexing API is limited to JobPosting and BroadcastEvent pages, not normal blog posts or product pages. Sitemaps plus Search Console inspection remain the core Google path for most URLs. This section maps each API to eligible URL types, auth needs, and realistic expectations, with an honest note that no API forces indexation or ranking.
Next, widen the lens from one URL to its template group. For api based link indexing, single page fixes rarely move coverage because the same include, plugin, or layout rule affects hundreds of pages. Export Search Console samples for the relevant status, add columns for template, word count, inlink count, canonical target, and sitemap presence, then sort by template. When which apis can submit backlink urls today clusters on one layout, the fix belongs in code or settings, not in the editor. When it spreads across layouts, look at sitewide signals such as navigation depth, crawl budget pressure, or recent deploy dates that shifted many pages at once.
Content quality still decides many close calls. For api based link indexing, compare the thin or duplicated page against indexed competitors on specificity, steps, examples, data, and intent fit. Add concrete details that a crawler can distinguish, such as exact procedures, error strings, thresholds, timelines, and follow up actions. Keep titles and H1s distinct across the section, tighten intros that repeat the same boilerplate, and remove auto generated archives that compete with priority pages. When which apis can submit backlink urls today improves uniqueness and intent match, Google has a clearer reason to keep the preferred URL in the index.
Checklist for which apis can submit backlink urls today:
- Confirm live status, headers, and rendered output on two samples from this template.
- Compare Search Console samples with crawl exports grouped by template and path.
- Align sitemap entries, internal anchors, and canonical targets to one preferred URL form.
- Fix the template or setting once, then retest across post types and archives.
- Purge page cache and edge cache, then recheck logged out HTML and headers.
- Log the change with dates and watch valid indexed counts for two weeks.
| Check for api based link indexing | What to look for | Next step |
|---|---|---|
| --- | --- | --- |
| Crawl access | robots result and log fetch rate | Narrow the exact disallow or allow pattern |
|---|---|---|
| Index permission | meta robots and X Robots Tag | Remove noindex from the true source layer |
| Canonical clarity | declared versus selected URL | Point all cues to one 200 indexable target |
|---|---|---|
| Internal support | inlink count and click depth | Add hub and contextual links with clear anchors |
Example: a site working on api based link indexing found that which apis can submit backlink urls today affected one template more than others. The team listed fifty sample URLs, added template and inlink columns, and saw that archive pages carried the same canonical as single posts while receiving almost no internal links. They updated the template so archives self reference only when they add unique value, added three contextual links from related hubs to priority singles, cleaned the sitemap to preferred URLs only, and purged cache. Live tests then showed consistent canonicals, logs showed steadier fetching of the priority section, and the valid indexed trend rose without bulk resubmits. For more context on adjacent coverage states, see IndexNow vs Google Indexing API Which Should You Use which explains how discovery and crawl states connect to this fix.
Then align the supporting signals that Google weighs alongside the main tag or directive. For api based link indexing, sitemaps should list only canonical 200 URLs with accurate lastmod, internal links should point to the same canonical variant with descriptive anchors, and alternate cues such as hreflang, pagination, or feed links should agree rather than compete. Mixed cues force Google to choose, which delays indexing. Pick one preferred URL form with consistent protocol, host, trailing slash, and parameter handling, update templates and feeds to emit it, and remove stale variants from sitemaps so crawlers spend time on pages that can actually be indexed.
Rollout discipline protects gains. For api based link indexing, back up templates and settings, change one layer at a time, and keep a simple log with template, change, date, and sample URLs. After deploy, clear caches, retest live output, and compare before and after exports rather than relying on memory. Share the log with editors and developers so no one reintroduces the old pattern during the next theme update. When which apis can submit backlink urls today is fixed at the template level with monitoring in place, coverage usually stays stable through future releases.
curl -I https://example.com/sample-pageHow a clean submission workflow looks end to end
A clean workflow is a short pipeline with logs. This api indexing workflow keeps modern link indexing practical for small teams, with automated link indexing that dedupes URLs and paces sends while byok link indexing keeps keys under your control. For api based link indexing, new or updated URLs enter a deduplicated queue, a worker sends them paced over time, responses are stored with timestamps, 429s trigger backoff, and coverage is checked weekly. Ownership proofs such as IndexNow key files stay reachable. This section walks through each stage with sample payload shapes described in words, queue fields to store, and handoffs between content, dev, and SEO owners so nothing is submitted twice or lost.
Then align the supporting signals that Google weighs alongside the main tag or directive. For api based link indexing, sitemaps should list only canonical 200 URLs with accurate lastmod, internal links should point to the same canonical variant with descriptive anchors, and alternate cues such as hreflang, pagination, or feed links should agree rather than compete. Mixed cues force Google to choose, which delays indexing. Pick one preferred URL form with consistent protocol, host, trailing slash, and parameter handling, update templates and feeds to emit it, and remove stale variants from sitemaps so crawlers spend time on pages that can actually be indexed.
Do not overlook rendering and performance. For api based link indexing, JavaScript that injects main content late, lazy loads critical links, or blocks CSS and scripts can make a healthy page look thin to crawlers. Test raw versus rendered word counts, list blocked resources reported in live tests, and confirm that canonicals, hreflang, and structured data appear in rendered HTML as well as source. Compress images, stabilize response times, and ensure the edge cache serves bots the same HTML as browsers. Faster stable rendering helps every other fix for how a clean submission workflow looks end to end get noticed sooner.
Checklist for how a clean submission workflow looks end to end:
- Confirm live status, headers, and rendered output on two samples from this template.
- Compare Search Console samples with crawl exports grouped by template and path.
- Align sitemap entries, internal anchors, and canonical targets to one preferred URL form.
- Fix the template or setting once, then retest across post types and archives.
- Purge page cache and edge cache, then recheck logged out HTML and headers.
- Log the change with dates and watch valid indexed counts for two weeks.
| Check for api based link indexing | What to look for | Next step |
|---|---|---|
| --- | --- | --- |
| Crawl access | robots result and log fetch rate | Narrow the exact disallow or allow pattern |
|---|---|---|
| Index permission | meta robots and X Robots Tag | Remove noindex from the true source layer |
| Canonical clarity | declared versus selected URL | Point all cues to one 200 indexable target |
|---|---|---|
| Internal support | inlink count and click depth | Add hub and contextual links with clear anchors |
Example: a site working on api based link indexing found that how a clean submission workflow looks end to end affected one template more than others. The team listed fifty sample URLs, added template and inlink columns, and saw that archive pages carried the same canonical as single posts while receiving almost no internal links. They updated the template so archives self reference only when they add unique value, added three contextual links from related hubs to priority singles, cleaned the sitemap to preferred URLs only, and purged cache. Live tests then showed consistent canonicals, logs showed steadier fetching of the priority section, and the valid indexed trend rose without bulk resubmits. For more context on adjacent coverage states, see IndexNow vs Google Indexing API Which Should You Use which explains how discovery and crawl states connect to this fix.
Finally, validate in small loops and track trends. For api based link indexing, fix staging first, deploy to production, purge page and edge caches, and retest headers and source on live URLs while logged out. Run URL Inspection live tests on two to three samples per template, not on thousands of URLs. Note last crawl dates and canonical selection, then watch the Pages report for the section over one to two weeks. Stable templates plus steady internal links usually move the valid count before any single URL is manually resubmitted. If movement stalls, revisit rendering, duplication, and depth before adding more requests.
Practical checks for how a clean submission workflow looks end to end work best as a short checklist with owners and dates. Confirm crawl access in robots.txt for the exact path and user agent, confirm index permission in meta and headers, confirm the canonical target returns 200 and allows indexing, confirm sitemap inclusion only for preferred URLs, and confirm at least a few relevant internal inlinks from indexed hubs. For api based link indexing, each check takes minutes but together they catch most blocks. Log which check failed for each sample so the repair targets the true source instead of applying broad changes that risk new issues.
curl -I https://example.com/sample-pageSetting up queues, logs, and safe retry rules
Reliability comes from boring engineering. For api based link indexing, store each URL once with first seen, last sent, response code, and retry count. Pace sends to a few per minute for small sites and scale only after clean responses. On 429 or 5xx, use exponential backoff with jitter and a daily cap. Keep a dead letter list for repeated failures to inspect manually. This section gives practical defaults, log columns, and alert rules that prevent hammering endpoints during launches.
Finally, validate in small loops and track trends. For api based link indexing, fix staging first, deploy to production, purge page and edge caches, and retest headers and source on live URLs while logged out. Run URL Inspection live tests on two to three samples per template, not on thousands of URLs. Note last crawl dates and canonical selection, then watch the Pages report for the section over one to two weeks. Stable templates plus steady internal links usually move the valid count before any single URL is manually resubmitted. If movement stalls, revisit rendering, duplication, and depth before adding more requests.
Rollout discipline protects gains. For api based link indexing, back up templates and settings, change one layer at a time, and keep a simple log with template, change, date, and sample URLs. After deploy, clear caches, retest live output, and compare before and after exports rather than relying on memory. Share the log with editors and developers so no one reintroduces the old pattern during the next theme update. When setting up queues, logs, and safe retry rules is fixed at the template level with monitoring in place, coverage usually stays stable through future releases.
Checklist for setting up queues, logs, and safe retry rules:
- Confirm live status, headers, and rendered output on two samples from this template.
- Compare Search Console samples with crawl exports grouped by template and path.
- Align sitemap entries, internal anchors, and canonical targets to one preferred URL form.
- Fix the template or setting once, then retest across post types and archives.
- Purge page cache and edge cache, then recheck logged out HTML and headers.
- Log the change with dates and watch valid indexed counts for two weeks.
| Check for api based link indexing | What to look for | Next step |
|---|---|---|
| --- | --- | --- |
| Crawl access | robots result and log fetch rate | Narrow the exact disallow or allow pattern |
|---|---|---|
| Index permission | meta robots and X Robots Tag | Remove noindex from the true source layer |
| Canonical clarity | declared versus selected URL | Point all cues to one 200 indexable target |
|---|---|---|
| Internal support | inlink count and click depth | Add hub and contextual links with clear anchors |
Example: a site working on api based link indexing found that setting up queues, logs, and safe retry rules affected one template more than others. The team listed fifty sample URLs, added template and inlink columns, and saw that archive pages carried the same canonical as single posts while receiving almost no internal links. They updated the template so archives self reference only when they add unique value, added three contextual links from related hubs to priority singles, cleaned the sitemap to preferred URLs only, and purged cache. Live tests then showed consistent canonicals, logs showed steadier fetching of the priority section, and the valid indexed trend rose without bulk resubmits. For more context on adjacent coverage states, see IndexNow vs Google Indexing API Which Should You Use which explains how discovery and crawl states connect to this fix.
To make progress on setting up queues, logs, and safe retry rules, start with live evidence rather than assumptions. Open the URL in a clean browser session, view source, and compare it with the rendered DOM. Note the title, meta robots, canonical link, headings, and main body length in both views. Then fetch response headers to confirm status code, content type, X Robots Tag, cache directives, and redirect chain length. For api based link indexing, these first facts decide whether deeper work is needed or whether a single header or tag explains the symptom. Record the date, template name, and test URLs so later changes can be tied to outcomes without guesswork.
Content quality still decides many close calls. For api based link indexing, compare the thin or duplicated page against indexed competitors on specificity, steps, examples, data, and intent fit. Add concrete details that a crawler can distinguish, such as exact procedures, error strings, thresholds, timelines, and follow up actions. Keep titles and H1s distinct across the section, tighten intros that repeat the same boilerplate, and remove auto generated archives that compete with priority pages. When setting up queues, logs, and safe retry rules improves uniqueness and intent match, Google has a clearer reason to keep the preferred URL in the index.
curl -I https://example.com/sample-pageHow to prioritize which backlink URLs to submit first
You cannot submit everything with equal care. Teams that submit backlinks via api for owned targets first, then index backlink urls for hubs, waste less quota and learn faster than bulk senders. For api based link indexing, prioritize URLs you own that support link value, such as link targets, hubs that link to targets, and updated sitemap sections. Do not bulk submit third party referrers you do not control. Rank by revenue impact, crawl freshness, and index status, with unindexed money pages first. This section provides a simple scoring sheet, batch sizes by site size, and guidance on when to pause new submissions and let crawlers catch up.
To make progress on how to prioritize which backlink urls to submit first, start with live evidence rather than assumptions. Open the URL in a clean browser session, view source, and compare it with the rendered DOM. Note the title, meta robots, canonical link, headings, and main body length in both views. Then fetch response headers to confirm status code, content type, X Robots Tag, cache directives, and redirect chain length. For api based link indexing, these first facts decide whether deeper work is needed or whether a single header or tag explains the symptom. Record the date, template name, and test URLs so later changes can be tied to outcomes without guesswork.
Practical checks for how to prioritize which backlink urls to submit first work best as a short checklist with owners and dates. Confirm crawl access in robots.txt for the exact path and user agent, confirm index permission in meta and headers, confirm the canonical target returns 200 and allows indexing, confirm sitemap inclusion only for preferred URLs, and confirm at least a few relevant internal inlinks from indexed hubs. For api based link indexing, each check takes minutes but together they catch most blocks. Log which check failed for each sample so the repair targets the true source instead of applying broad changes that risk new issues.
Checklist for how to prioritize which backlink urls to submit first:
- Confirm live status, headers, and rendered output on two samples from this template.
- Compare Search Console samples with crawl exports grouped by template and path.
- Align sitemap entries, internal anchors, and canonical targets to one preferred URL form.
- Fix the template or setting once, then retest across post types and archives.
- Purge page cache and edge cache, then recheck logged out HTML and headers.
- Log the change with dates and watch valid indexed counts for two weeks.
| Check for api based link indexing | What to look for | Next step |
|---|---|---|
| --- | --- | --- |
| Crawl access | robots result and log fetch rate | Narrow the exact disallow or allow pattern |
|---|---|---|
| Index permission | meta robots and X Robots Tag | Remove noindex from the true source layer |
| Canonical clarity | declared versus selected URL | Point all cues to one 200 indexable target |
|---|---|---|
| Internal support | inlink count and click depth | Add hub and contextual links with clear anchors |
Example: a site working on api based link indexing found that how to prioritize which backlink urls to submit first affected one template more than others. The team listed fifty sample URLs, added template and inlink columns, and saw that archive pages carried the same canonical as single posts while receiving almost no internal links. They updated the template so archives self reference only when they add unique value, added three contextual links from related hubs to priority singles, cleaned the sitemap to preferred URLs only, and purged cache. Live tests then showed consistent canonicals, logs showed steadier fetching of the priority section, and the valid indexed trend rose without bulk resubmits. For more context on adjacent coverage states, see IndexNow vs Google Indexing API Which Should You Use which explains how discovery and crawl states connect to this fix.
Next, widen the lens from one URL to its template group. For api based link indexing, single page fixes rarely move coverage because the same include, plugin, or layout rule affects hundreds of pages. Export Search Console samples for the relevant status, add columns for template, word count, inlink count, canonical target, and sitemap presence, then sort by template. When how to prioritize which backlink urls to submit first clusters on one layout, the fix belongs in code or settings, not in the editor. When it spreads across layouts, look at sitewide signals such as navigation depth, crawl budget pressure, or recent deploy dates that shifted many pages at once.
Do not overlook rendering and performance. For api based link indexing, JavaScript that injects main content late, lazy loads critical links, or blocks CSS and scripts can make a healthy page look thin to crawlers. Test raw versus rendered word counts, list blocked resources reported in live tests, and confirm that canonicals, hreflang, and structured data appear in rendered HTML as well as source. Compress images, stabilize response times, and ensure the edge cache serves bots the same HTML as browsers. Faster stable rendering helps every other fix for how to prioritize which backlink urls to submit first get noticed sooner.
curl -I https://example.com/sample-pageMeasuring crawl visits and index coverage after submit
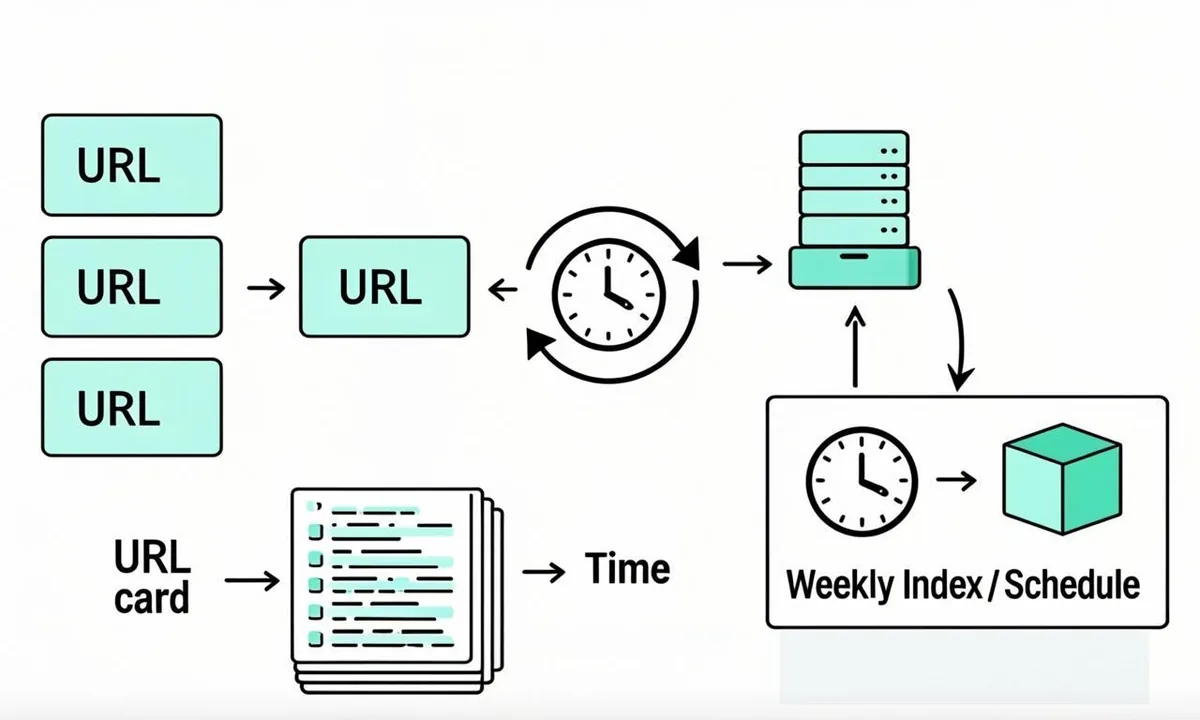
Submission without measurement is guesswork. For api based link indexing, track sent count, response codes, crawl visits from logs where available, and valid indexed trends in Webmaster Tools. Compare submitted sections against an untouched control to separate API effects from general movement. This section shows which charts to keep, how to annotate send dates, and how long to wait before judging, usually one to two weeks for crawl signals and longer for stable index trends.
Next, widen the lens from one URL to its template group. For api based link indexing, single page fixes rarely move coverage because the same include, plugin, or layout rule affects hundreds of pages. Export Search Console samples for the relevant status, add columns for template, word count, inlink count, canonical target, and sitemap presence, then sort by template. When measuring crawl visits and index coverage after submit clusters on one layout, the fix belongs in code or settings, not in the editor. When it spreads across layouts, look at sitewide signals such as navigation depth, crawl budget pressure, or recent deploy dates that shifted many pages at once.
Content quality still decides many close calls. For api based link indexing, compare the thin or duplicated page against indexed competitors on specificity, steps, examples, data, and intent fit. Add concrete details that a crawler can distinguish, such as exact procedures, error strings, thresholds, timelines, and follow up actions. Keep titles and H1s distinct across the section, tighten intros that repeat the same boilerplate, and remove auto generated archives that compete with priority pages. When measuring crawl visits and index coverage after submit improves uniqueness and intent match, Google has a clearer reason to keep the preferred URL in the index.
Checklist for measuring crawl visits and index coverage after submit:
- Confirm live status, headers, and rendered output on two samples from this template.
- Compare Search Console samples with crawl exports grouped by template and path.
- Align sitemap entries, internal anchors, and canonical targets to one preferred URL form.
- Fix the template or setting once, then retest across post types and archives.
- Purge page cache and edge cache, then recheck logged out HTML and headers.
- Log the change with dates and watch valid indexed counts for two weeks.
| Check for api based link indexing | What to look for | Next step |
|---|---|---|
| --- | --- | --- |
| Crawl access | robots result and log fetch rate | Narrow the exact disallow or allow pattern |
|---|---|---|
| Index permission | meta robots and X Robots Tag | Remove noindex from the true source layer |
| Canonical clarity | declared versus selected URL | Point all cues to one 200 indexable target |
|---|---|---|
| Internal support | inlink count and click depth | Add hub and contextual links with clear anchors |
Example: a site working on api based link indexing found that measuring crawl visits and index coverage after submit affected one template more than others. The team listed fifty sample URLs, added template and inlink columns, and saw that archive pages carried the same canonical as single posts while receiving almost no internal links. They updated the template so archives self reference only when they add unique value, added three contextual links from related hubs to priority singles, cleaned the sitemap to preferred URLs only, and purged cache. Live tests then showed consistent canonicals, logs showed steadier fetching of the priority section, and the valid indexed trend rose without bulk resubmits. For more context on adjacent coverage states, see IndexNow vs Google Indexing API Which Should You Use which explains how discovery and crawl states connect to this fix.
Then align the supporting signals that Google weighs alongside the main tag or directive. For api based link indexing, sitemaps should list only canonical 200 URLs with accurate lastmod, internal links should point to the same canonical variant with descriptive anchors, and alternate cues such as hreflang, pagination, or feed links should agree rather than compete. Mixed cues force Google to choose, which delays indexing. Pick one preferred URL form with consistent protocol, host, trailing slash, and parameter handling, update templates and feeds to emit it, and remove stale variants from sitemaps so crawlers spend time on pages that can actually be indexed.
Rollout discipline protects gains. For api based link indexing, back up templates and settings, change one layer at a time, and keep a simple log with template, change, date, and sample URLs. After deploy, clear caches, retest live output, and compare before and after exports rather than relying on memory. Share the log with editors and developers so no one reintroduces the old pattern during the next theme update. When measuring crawl visits and index coverage after submit is fixed at the template level with monitoring in place, coverage usually stays stable through future releases.
curl -I https://example.com/sample-pageRunning API indexing week after week without spam
The goal is a quiet routine, not bursts. For api based link indexing, review the queue weekly, prune stale URLs, refresh sitemaps with accurate lastmod, keep internal links stable, and rotate keys safely where used. Document owners, quotas, and change dates. Avoid resubmitting the same unchanged URLs daily. This section lays out a weekly checklist, monthly audit, and simple governance that keeps submissions useful, transparent, and well within quotas and guidelines.
Then align the supporting signals that Google weighs alongside the main tag or directive. For api based link indexing, sitemaps should list only canonical 200 URLs with accurate lastmod, internal links should point to the same canonical variant with descriptive anchors, and alternate cues such as hreflang, pagination, or feed links should agree rather than compete. Mixed cues force Google to choose, which delays indexing. Pick one preferred URL form with consistent protocol, host, trailing slash, and parameter handling, update templates and feeds to emit it, and remove stale variants from sitemaps so crawlers spend time on pages that can actually be indexed.
Do not overlook rendering and performance. For api based link indexing, JavaScript that injects main content late, lazy loads critical links, or blocks CSS and scripts can make a healthy page look thin to crawlers. Test raw versus rendered word counts, list blocked resources reported in live tests, and confirm that canonicals, hreflang, and structured data appear in rendered HTML as well as source. Compress images, stabilize response times, and ensure the edge cache serves bots the same HTML as browsers. Faster stable rendering helps every other fix for running api indexing week after week without spam get noticed sooner.
Checklist for running api indexing week after week without spam:
- Confirm live status, headers, and rendered output on two samples from this template.
- Compare Search Console samples with crawl exports grouped by template and path.
- Align sitemap entries, internal anchors, and canonical targets to one preferred URL form.
- Fix the template or setting once, then retest across post types and archives.
- Purge page cache and edge cache, then recheck logged out HTML and headers.
- Log the change with dates and watch valid indexed counts for two weeks.
| Check for api based link indexing | What to look for | Next step |
|---|---|---|
| --- | --- | --- |
| Crawl access | robots result and log fetch rate | Narrow the exact disallow or allow pattern |
|---|---|---|
| Index permission | meta robots and X Robots Tag | Remove noindex from the true source layer |
| Canonical clarity | declared versus selected URL | Point all cues to one 200 indexable target |
|---|---|---|
| Internal support | inlink count and click depth | Add hub and contextual links with clear anchors |
Example: a site working on api based link indexing found that running api indexing week after week without spam affected one template more than others. The team listed fifty sample URLs, added template and inlink columns, and saw that archive pages carried the same canonical as single posts while receiving almost no internal links. They updated the template so archives self reference only when they add unique value, added three contextual links from related hubs to priority singles, cleaned the sitemap to preferred URLs only, and purged cache. Live tests then showed consistent canonicals, logs showed steadier fetching of the priority section, and the valid indexed trend rose without bulk resubmits. For more context on adjacent coverage states, see IndexNow vs Google Indexing API Which Should You Use which explains how discovery and crawl states connect to this fix.
Finally, validate in small loops and track trends. For api based link indexing, fix staging first, deploy to production, purge page and edge caches, and retest headers and source on live URLs while logged out. Run URL Inspection live tests on two to three samples per template, not on thousands of URLs. Note last crawl dates and canonical selection, then watch the Pages report for the section over one to two weeks. Stable templates plus steady internal links usually move the valid count before any single URL is manually resubmitted. If movement stalls, revisit rendering, duplication, and depth before adding more requests.
Practical checks for running api indexing week after week without spam work best as a short checklist with owners and dates. Confirm crawl access in robots.txt for the exact path and user agent, confirm index permission in meta and headers, confirm the canonical target returns 200 and allows indexing, confirm sitemap inclusion only for preferred URLs, and confirm at least a few relevant internal inlinks from indexed hubs. For api based link indexing, each check takes minutes but together they catch most blocks. Log which check failed for each sample so the repair targets the true source instead of applying broad changes that risk new issues.
curl -I https://example.com/sample-pageFAQ
What is API based backlink indexing?
It is the practice of submitting URLs you own through official APIs and sitemaps with proper auth, pacing, and logs, so participating engines discover changes faster. It does not mean forcing third party referrers into Google. For Google, most backlink support work still runs through sitemaps, internal links, and quality content, with the Google Indexing API limited to specific page types. The value is transparency, control, and auditability compared to opaque pools.
For api based link indexing, keep notes on template, date, and sample URLs when you apply this answer. Small consistent records make it easier to see which change moved the valid indexed count and which change had no effect. If results stall after two crawl cycles, recheck rendering, duplication, and internal support before trying a different fix. Stable signals over time matter more than repeated single URL tests.
Can I submit backlink URLs I do not own?
No for endpoints that require ownership proof, such as IndexNow key files or Search Console verified properties. Submitting third party URLs without control fails verification or violates guidelines. Focus your queue on URLs you own, such as link targets and hubs. For referrers you do not own, help discovery through normal editorial means and ask publishers to use their own sitemaps and pings.
For api based link indexing, keep notes on template, date, and sample URLs when you apply this answer. Small consistent records make it easier to see which change moved the valid indexed count and which change had no effect. If results stall after two crawl cycles, recheck rendering, duplication, and internal support before trying a different fix. Stable signals over time matter more than repeated single URL tests.
Does API submission guarantee indexing?
No. APIs request crawling and processing, but indexation still depends on quality, relevance, duplication, and site signals. Treat submission as removing discovery friction, not as a ranking lever. Track response codes, crawl visits, and valid indexed trends. If indexed counts do not move after clean submissions and good responses, fix content and internal support before sending more.
For api based link indexing, keep notes on template, date, and sample URLs when you apply this answer. Small consistent records make it easier to see which change moved the valid indexed count and which change had no effect. If results stall after two crawl cycles, recheck rendering, duplication, and internal support before trying a different fix. Stable signals over time matter more than repeated single URL tests.
How is this cheaper than a link indexer service?
You pay mostly in setup and maintenance rather than per link fees. Sitemaps and IndexNow have no per URL charge beyond hosting and time. The Google Indexing API has no per call fee but strict eligibility and quotas. A small queue script with logs often costs less over a quarter than a subscription that charges per link. That is why automated link indexing with byok link indexing often beats per link fees, while modern link indexing stays auditable, and the records show exactly what was sent, when, and with what response.
For api based link indexing, keep notes on template, date, and sample URLs when you apply this answer. Small consistent records make it easier to see which change moved the valid indexed count and which change had no effect. If results stall after two crawl cycles, recheck rendering, duplication, and internal support before trying a different fix. Stable signals over time matter more than repeated single URL tests.
What do I need to start with IndexNow for owned URLs?
You need a key file at the host root, a queue for api url submission links with canonical 200 URLs you own, a sender that paces POSTs with JSON bodies, and a log for codes and timestamps. Keep the key file reachable, respect 429 backoff, and keep sitemaps accurate alongside pings. Start with a small batch of updated targets and hubs, confirm clean responses, then scale gradually while watching crawl stats. Document the api indexing workflow so any teammate can submit backlinks via api safely and index backlink urls without duplicates.
For api based link indexing, keep notes on template, date, and sample URLs when you apply this answer. Small consistent records make it easier to see which change moved the valid indexed count and which change had no effect. If results stall after two crawl cycles, recheck rendering, duplication, and internal support before trying a different fix. Stable signals over time matter more than repeated single URL tests.
How often should I submit updated URLs?
Submit when content is added, updated, or removed, not on a fixed daily blast of unchanged URLs. Many small sites do well with event driven sends plus a weekly review. Large sites batch by section with pacing and caps. If responses show 429s or coverage stalls, slow down and let crawlers catch up. Steady event driven submission beats bulk resends of the same list.
For api based link indexing, keep notes on template, date, and sample URLs when you apply this answer. Small consistent records make it easier to see which change moved the valid indexed count and which change had no effect. If results stall after two crawl cycles, recheck rendering, duplication, and internal support before trying a different fix. Stable signals over time matter more than repeated single URL tests.