Self-Hosted vs. BYOK SaaS: Which Is Right for You?

This guide is for site owners, SEOs, and developers who need a clear operating view of self hosted vs byok. It explains what drives results, what drives cost and risk, and what to do each week to keep the system steady. You will learn how self hosted vs byok fits beside sitemaps, internal linking, and crawl budget, and you will leave with a checklist you can apply without new headcount. The tone stays practical throughout, with numbers you can verify in your own console and steps you can assign to one owner. Read the takeaways first, then follow the ten sections in order, because each builds on the prior baseline. By the end you will be able to size demand, set quota buffers, wire logging, and review progress in a short weekly loop. No hype is needed here, only steady plumbing that keeps discovery aligned with publishing.
Key takeaways
- Self-Hosted vs. BYOK SaaS: Which Is Right for You? rewards demand sizing before tooling, because quota and labor follow URL mix.
- Keep quota, logs, and ownership visible in your own accounts so self hosted vs byok stays debuggable.
- Prefer small pilots of 50 to 100 URLs with measured latency over large blind bulk runs.
- Review one metric weekly with one owner, then scale batch size only when logs stay green.
- What self hosted means for indexing teams
- What BYOK SaaS keeps and what it removes
- Control comparison for self hosted vs byok across keys and deploys
- Time to value from signup to first submission
- Total cost over twelve months
- Security and access patterns compared
- Reliability and on call burden
- Scaling from hundreds to millions of URLs
- Team skills that tip the decision
- A decision matrix you can use this week
 <!-- IMAGE-PROMPT cover: 1200x630, DependsIt brand, deep charcoal #121212 or clean white background, vibrant mint #22E3B0 accent glow, thin node-network line art, Clash Display style bold heading space on left, General Sans clean labels, subject: self hosted vs byok overview diagram, flat vector, high contrast, accessible, no photorealistic faces, no text smaller than 24px, no em dash in rendered text, export PNG then cwebp -q 82 to WEBP -->
What self hosted means for indexing teams
This part focuses on what self hosted means for indexing teams in the context of self hosted vs byok. This section starts with the practical reality most teams meet in the first week, which is that the idea sounds simple until real limits, real logs, and real teammates enter the picture. The key is to separate what the vendor controls from what you control, because that split decides where time goes and where money goes. For teams working on self hosted vs byok, what self hosted means for indexing teams repays careful setup. Teams comparing self hosted seo tools with hosting your own tools should count self hosted cost in hours, because maintain own scripts work decides whether control is worth the on call load. What this covers in practice:
- Demand first: map URL types to priority tiers so high value pages submit first and low value pages wait without blocking the queue. Applied to what self hosted means for indexing teams, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Quota aware: check quota in your own project console before launch and set alerts at 60 percent and 85 percent of daily use. Applied to what self hosted means for indexing teams, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Logged fully: store request IDs, response codes, and timestamps for every submission so debugging takes minutes instead of days. Applied to what self hosted means for indexing teams, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Retried safely: use exponential backoff with jitter on 429 responses and cap retries so a burst does not turn into a ban. Applied to what self hosted means for indexing teams, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Reviewed weekly: review success rate, crawl latency, and index coverage weekly and adjust batch size based on what the logs show. Applied to what self hosted means for indexing teams, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
Use the table below to turn what self hosted means for indexing teams into numbers your team can track for self hosted vs byok.
| Field | Typical value | How to use it |
|---|---|---|
| Input | Example value | What to verify for what self hosted means for indexing teams |
| URL count per week | 400 new plus 900 updates | Count by template and priority before sizing quota for what self hosted means for indexing teams |
| Quota headroom | 40 percent unused on peak day | Keep buffer for launches and bulk fixes for what self hosted means for indexing teams |
| Log retention | 90 days searchable | Keep request ID plus response code plus timestamp for what self hosted means for indexing teams |
| Review cadence | Weekly 30 minutes | Owner plus metric plus action list in one doc for what self hosted means for indexing teams |
Once the baseline is clear, look at the failure modes, because averages hide the cases that consume most support time. Each failure has a different owner, which means auth failures go to the cloud admin, content failures go to the CMS owner, and queue failures go to the engineer who runs the worker.
Practical steps to apply this week:
- List all URL sources that should trigger submission, including CMS publish events, deploy hooks, sitemap diffs, and manual backfill lists. Relate each step to what self hosted means for indexing teams so progress on self hosted vs byok stays visible to content and engineering alike.
- Assign each source a priority tier and a daily cap so one noisy source cannot consume the full quota before important pages submit. Relate each step to what self hosted means for indexing teams so progress on self hosted vs byok stays visible to content and engineering alike.
- Wire logging before automation, because you want visibility on day one rather than after the first incident. Relate each step to what self hosted means for indexing teams so progress on self hosted vs byok stays visible to content and engineering alike.
- Run a small pilot of 50 to 100 URLs, measure submission to crawl latency, then scale batch size in controlled steps. Relate each step to what self hosted means for indexing teams so progress on self hosted vs byok stays visible to content and engineering alike.
To close the loop, tie this section back to weekly operations, because strategy without a cadence fades within a month. Pick one metric, one owner, and one review point, such as submission success rate reviewed every Monday by the SEO lead.
In short, treat what self hosted means for indexing teams as an operating habit for self hosted vs byok, not a one time setting. Small weekly reviews beat large quarterly fixes, and steady logs beat heroic debugging.
What BYOK SaaS keeps and what it removes
This part focuses on what byok saas keeps and what it removes in the context of self hosted vs byok. The key is to separate what the vendor controls from what you control, because that split decides where time goes and where money goes. Most guides skip this split and talk only about features, which leaves readers surprised by follow up work that was predictable from the start. For teams working on self hosted vs byok, what byok saas keeps and what it removes repays careful setup. That baseline matters more than any benchmark, because your mix of new pages, updates, and deletions sets the load you place on any submission path. A simple spreadsheet with URL counts by type and by priority gives you a demand curve you can match against quota and staffing. What this covers in practice:
- Demand first: map URL types to priority tiers so high value pages submit first and low value pages wait without blocking the queue. Applied to what byok saas keeps and what it removes, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Quota aware: check quota in your own project console before launch and set alerts at 60 percent and 85 percent of daily use. Applied to what byok saas keeps and what it removes, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Logged fully: store request IDs, response codes, and timestamps for every submission so debugging takes minutes instead of days. Applied to what byok saas keeps and what it removes, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Retried safely: use exponential backoff with jitter on 429 responses and cap retries so a burst does not turn into a ban. Applied to what byok saas keeps and what it removes, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Reviewed weekly: review success rate, crawl latency, and index coverage weekly and adjust batch size based on what the logs show. Applied to what byok saas keeps and what it removes, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
Use the table below to turn what byok saas keeps and what it removes into numbers your team can track for self hosted vs byok.
| Field | Typical value | How to use it |
|---|---|---|
| Input | Example value | What to verify for what byok saas keeps and what it removes |
| URL count per week | 400 new plus 900 updates | Count by template and priority before sizing quota for what byok saas keeps and what it removes |
| Quota headroom | 40 percent unused on peak day | Keep buffer for launches and bulk fixes for what byok saas keeps and what it removes |
| Log retention | 90 days searchable | Keep request ID plus response code plus timestamp for what byok saas keeps and what it removes |
| Review cadence | Weekly 30 minutes | Owner plus metric plus action list in one doc for what byok saas keeps and what it removes |
Common failure modes include expired credentials, revoked Search Console access, malformed URL lists, duplicate submissions, and silent drops where a 200 response did not lead to a crawl. Document the owner next to each alert, because pages at 2am get fixed faster when the runbook names a role instead of a team.
Practical steps to apply this week:
- List all URL sources that should trigger submission, including CMS publish events, deploy hooks, sitemap diffs, and manual backfill lists. Relate each step to what byok saas keeps and what it removes so progress on self hosted vs byok stays visible to content and engineering alike.
- Assign each source a priority tier and a daily cap so one noisy source cannot consume the full quota before important pages submit. Relate each step to what byok saas keeps and what it removes so progress on self hosted vs byok stays visible to content and engineering alike.
- Wire logging before automation, because you want visibility on day one rather than after the first incident. Relate each step to what byok saas keeps and what it removes so progress on self hosted vs byok stays visible to content and engineering alike.
- Run a small pilot of 50 to 100 URLs, measure submission to crawl latency, then scale batch size in controlled steps. Relate each step to what byok saas keeps and what it removes so progress on self hosted vs byok stays visible to content and engineering alike.
Pick one metric, one owner, and one review point, such as submission success rate reviewed every Monday by the SEO lead. Add a second metric only after the first stays green for four weeks, because too many dashboards hide the signal that matters.
In short, treat what byok saas keeps and what it removes as an operating habit for self hosted vs byok, not a one time setting. Small weekly reviews beat large quarterly fixes, and steady logs beat heroic debugging. For protocol background, see the Google search documentation on sitemaps alongside your own console quota graphs, then compare with your weekly demand sheet.
Pair that reading with the complete setup guide for the Google Indexing API to keep setup steps aligned with cost thinking.
Control comparison for self hosted vs byok across keys and deploys
This part focuses on control comparison for self hosted vs byok across keys and deploys in the context of self hosted vs byok. Most guides skip this split and talk only about features, which leaves readers surprised by follow up work that was predictable from the start. A calm way to read this topic is to track three things together, which are quota, labor, and risk, and to review them on the same page. For teams working on self hosted vs byok, control comparison across keys data and deploys repays careful setup. Teams that skip the baseline often overbuild, buying capacity they never use, or underbuild, queuing URLs that needed same day crawling. Keep that sheet for a month, because patterns in publishing cadence show up quickly and they guide every later choice in this guide. What this covers in practice:
- Demand first: map URL types to priority tiers so high value pages submit first and low value pages wait without blocking the queue. Applied to control comparison across keys data and deploys, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Quota aware: check quota in your own project console before launch and set alerts at 60 percent and 85 percent of daily use. Applied to control comparison across keys data and deploys, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Logged fully: store request IDs, response codes, and timestamps for every submission so debugging takes minutes instead of days. Applied to control comparison across keys data and deploys, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Retried safely: use exponential backoff with jitter on 429 responses and cap retries so a burst does not turn into a ban. Applied to control comparison across keys data and deploys, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Reviewed weekly: review success rate, crawl latency, and index coverage weekly and adjust batch size based on what the logs show. Applied to control comparison across keys data and deploys, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
Use the table below to turn control comparison across keys data and deploys into numbers your team can track for self hosted vs byok.
| Field | Typical value | How to use it |
|---|---|---|
| Input | Example value | What to verify for control comparison across keys data and deploys |
| URL count per week | 400 new plus 900 updates | Count by template and priority before sizing quota for control comparison across keys data and deploys |
| Quota headroom | 40 percent unused on peak day | Keep buffer for launches and bulk fixes for control comparison across keys data and deploys |
| Log retention | 90 days searchable | Keep request ID plus response code plus timestamp for control comparison across keys data and deploys |
| Review cadence | Weekly 30 minutes | Owner plus metric plus action list in one doc for control comparison across keys data and deploys |
Each failure has a different owner, which means auth failures go to the cloud admin, content failures go to the CMS owner, and queue failures go to the engineer who runs the worker. Over time this list becomes your reliability checklist, and it pays for itself by cutting repeat incidents that otherwise eat sprint capacity.
Practical steps to apply this week:
- List all URL sources that should trigger submission, including CMS publish events, deploy hooks, sitemap diffs, and manual backfill lists. Relate each step to control comparison across keys data and deploys so progress on self hosted vs byok stays visible to content and engineering alike.
- Assign each source a priority tier and a daily cap so one noisy source cannot consume the full quota before important pages submit. Relate each step to control comparison across keys data and deploys so progress on self hosted vs byok stays visible to content and engineering alike.
- Wire logging before automation, because you want visibility on day one rather than after the first incident. Relate each step to control comparison across keys data and deploys so progress on self hosted vs byok stays visible to content and engineering alike.
- Run a small pilot of 50 to 100 URLs, measure submission to crawl latency, then scale batch size in controlled steps. Relate each step to control comparison across keys data and deploys so progress on self hosted vs byok stays visible to content and engineering alike.
Add a second metric only after the first stays green for four weeks, because too many dashboards hide the signal that matters. Write the decision you made and the reason in a short log, so future teammates understand why the current setup looks the way it does.
In short, treat control comparison across keys data and deploys as an operating habit for self hosted vs byok, not a one time setting. Small weekly reviews beat large quarterly fixes, and steady logs beat heroic debugging. 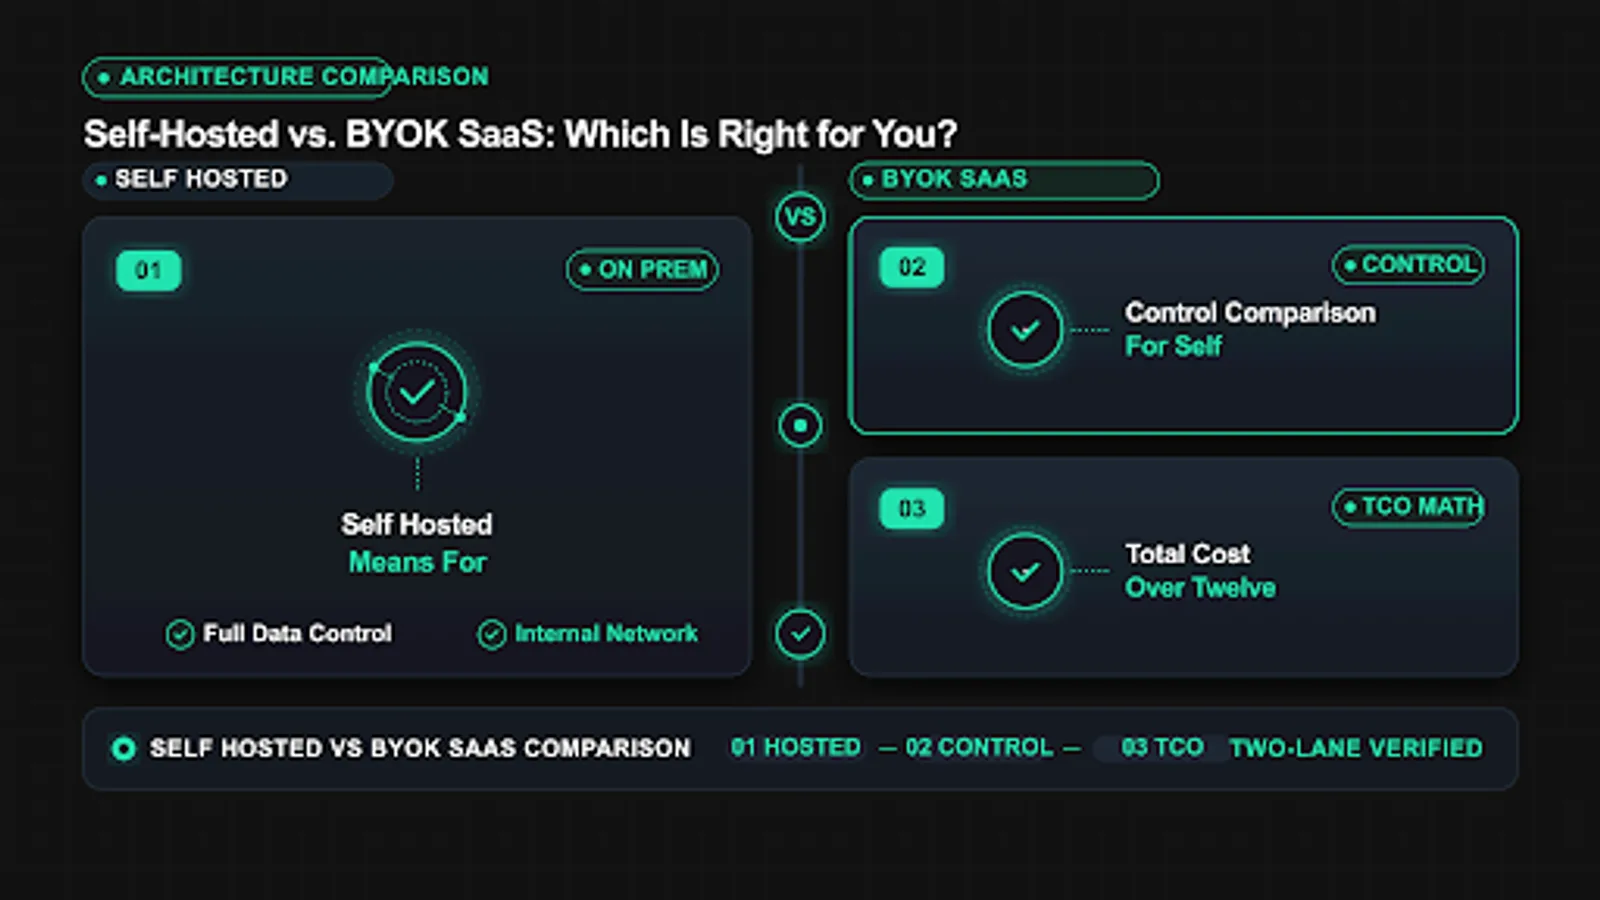 <!-- IMAGE-PROMPT diagram-01: 1600px max, DependsIt brand mint #22E3B0 on charcoal #121212 or white, node-network line art, Clash Display and General Sans feel, subject: control comparison across keys data and deploys diagram for self hosted vs byok, flat vector, accessible, no em dash -->
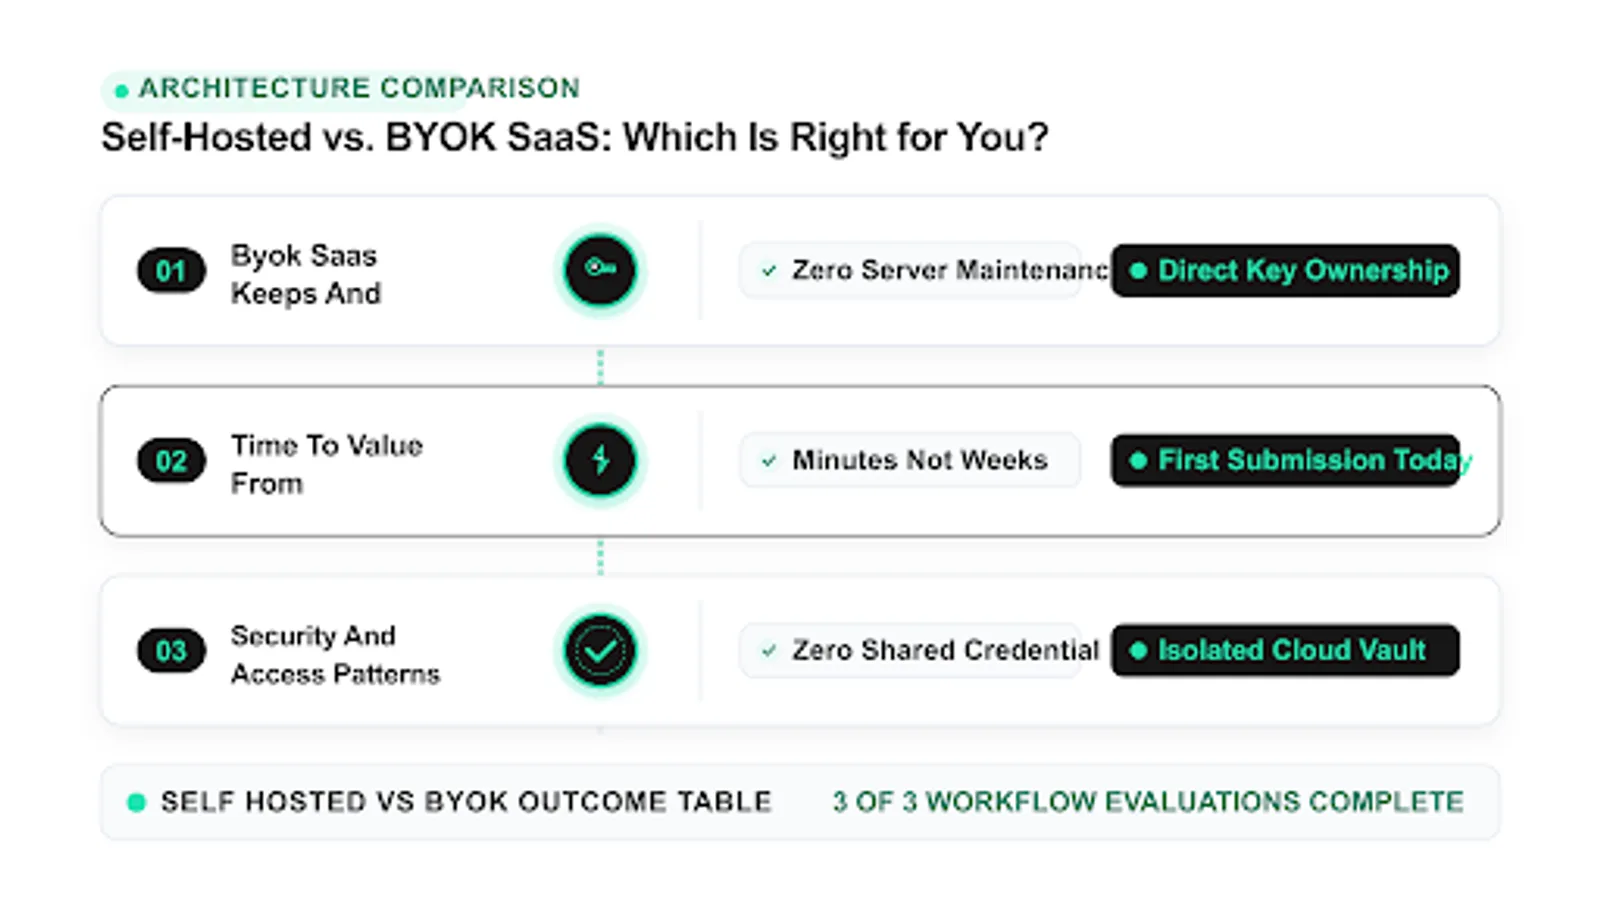 <!-- IMAGE-PROMPT diagram-02: 1600px max, DependsIt brand, subject: side-by-side outcome table visual with 3 rows about What BYOK SaaS keeps and what it removes | Time to value from signup to first submission, flat vector, accessible, no em dash -->
Time to value from signup to first submission
This part focuses on time to value from signup to first submission in the context of self hosted vs byok. A calm way to read this topic is to track three things together, which are quota, labor, and risk, and to review them on the same page. When those three are visible, decisions get easier, because trade offs stop hiding inside vague claims about automation or scale. For teams working on self hosted vs byok, time to value from signup to first submission repays careful setup. A simple spreadsheet with URL counts by type and by priority gives you a demand curve you can match against quota and staffing. Start by writing down your current baseline, including how many URLs you publish per week, how many need fast discovery, and how you confirm discovery today. What this covers in practice:
- Demand first: map URL types to priority tiers so high value pages submit first and low value pages wait without blocking the queue. Applied to time to value from signup to first submission, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Quota aware: check quota in your own project console before launch and set alerts at 60 percent and 85 percent of daily use. Applied to time to value from signup to first submission, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Logged fully: store request IDs, response codes, and timestamps for every submission so debugging takes minutes instead of days. Applied to time to value from signup to first submission, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Retried safely: use exponential backoff with jitter on 429 responses and cap retries so a burst does not turn into a ban. Applied to time to value from signup to first submission, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Reviewed weekly: review success rate, crawl latency, and index coverage weekly and adjust batch size based on what the logs show. Applied to time to value from signup to first submission, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
Use the table below to turn time to value from signup to first submission into numbers your team can track for self hosted vs byok.
| Field | Typical value | How to use it |
|---|---|---|
| Input | Example value | What to verify for time to value from signup to first submission |
| URL count per week | 400 new plus 900 updates | Count by template and priority before sizing quota for time to value from signup to first submission |
| Quota headroom | 40 percent unused on peak day | Keep buffer for launches and bulk fixes for time to value from signup to first submission |
| Log retention | 90 days searchable | Keep request ID plus response code plus timestamp for time to value from signup to first submission |
| Review cadence | Weekly 30 minutes | Owner plus metric plus action list in one doc for time to value from signup to first submission |
Document the owner next to each alert, because pages at 2am get fixed faster when the runbook names a role instead of a team. Once the baseline is clear, look at the failure modes, because averages hide the cases that consume most support time.
Practical steps to apply this week:
- List all URL sources that should trigger submission, including CMS publish events, deploy hooks, sitemap diffs, and manual backfill lists. Relate each step to time to value from signup to first submission so progress on self hosted vs byok stays visible to content and engineering alike.
- Assign each source a priority tier and a daily cap so one noisy source cannot consume the full quota before important pages submit. Relate each step to time to value from signup to first submission so progress on self hosted vs byok stays visible to content and engineering alike.
- Wire logging before automation, because you want visibility on day one rather than after the first incident. Relate each step to time to value from signup to first submission so progress on self hosted vs byok stays visible to content and engineering alike.
- Run a small pilot of 50 to 100 URLs, measure submission to crawl latency, then scale batch size in controlled steps. Relate each step to time to value from signup to first submission so progress on self hosted vs byok stays visible to content and engineering alike.
Write the decision you made and the reason in a short log, so future teammates understand why the current setup looks the way it does. That habit keeps the system explainable, which matters more than cleverness once multiple people touch the same pipeline.
In short, treat time to value from signup to first submission as an operating habit for self hosted vs byok, not a one time setting. Small weekly reviews beat large quarterly fixes, and steady logs beat heroic debugging.
Total cost over twelve months
This part focuses on total cost over twelve months in the context of self hosted vs byok. When those three are visible, decisions get easier, because trade offs stop hiding inside vague claims about automation or scale. This section starts with the practical reality most teams meet in the first week, which is that the idea sounds simple until real limits, real logs, and real teammates enter the picture. For teams working on self hosted vs byok, total cost over twelve months repays careful setup. Frame the choice as saas vs self hosted on total hours, weigh control vs convenience for your team size, and note how byok middle ground keeps tool ownership with you while renting queue workers. What this covers in practice:
- Demand first: map URL types to priority tiers so high value pages submit first and low value pages wait without blocking the queue. Applied to total cost over twelve months, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Quota aware: check quota in your own project console before launch and set alerts at 60 percent and 85 percent of daily use. Applied to total cost over twelve months, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Logged fully: store request IDs, response codes, and timestamps for every submission so debugging takes minutes instead of days. Applied to total cost over twelve months, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Retried safely: use exponential backoff with jitter on 429 responses and cap retries so a burst does not turn into a ban. Applied to total cost over twelve months, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Reviewed weekly: review success rate, crawl latency, and index coverage weekly and adjust batch size based on what the logs show. Applied to total cost over twelve months, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
Use the table below to turn total cost over twelve months into numbers your team can track for self hosted vs byok.
| Field | Typical value | How to use it |
|---|---|---|
| Input | Example value | What to verify for total cost over twelve months |
| URL count per week | 400 new plus 900 updates | Count by template and priority before sizing quota for total cost over twelve months |
| Quota headroom | 40 percent unused on peak day | Keep buffer for launches and bulk fixes for total cost over twelve months |
| Log retention | 90 days searchable | Keep request ID plus response code plus timestamp for total cost over twelve months |
| Review cadence | Weekly 30 minutes | Owner plus metric plus action list in one doc for total cost over twelve months |
Over time this list becomes your reliability checklist, and it pays for itself by cutting repeat incidents that otherwise eat sprint capacity. Common failure modes include expired credentials, revoked Search Console access, malformed URL lists, duplicate submissions, and silent drops where a 200 response did not lead to a crawl.
Practical steps to apply this week:
- List all URL sources that should trigger submission, including CMS publish events, deploy hooks, sitemap diffs, and manual backfill lists. Relate each step to total cost over twelve months so progress on self hosted vs byok stays visible to content and engineering alike.
- Assign each source a priority tier and a daily cap so one noisy source cannot consume the full quota before important pages submit. Relate each step to total cost over twelve months so progress on self hosted vs byok stays visible to content and engineering alike.
- Wire logging before automation, because you want visibility on day one rather than after the first incident. Relate each step to total cost over twelve months so progress on self hosted vs byok stays visible to content and engineering alike.
- Run a small pilot of 50 to 100 URLs, measure submission to crawl latency, then scale batch size in controlled steps. Relate each step to total cost over twelve months so progress on self hosted vs byok stays visible to content and engineering alike.
That habit keeps the system explainable, which matters more than cleverness once multiple people touch the same pipeline. To close the loop, tie this section back to weekly operations, because strategy without a cadence fades within a month.
In short, treat total cost over twelve months as an operating habit for self hosted vs byok, not a one time setting. Small weekly reviews beat large quarterly fixes, and steady logs beat heroic debugging. Teams often review the bulk submission safe limits and scripts at this stage, because quota behavior explains many cost surprises.
Security and access patterns compared
This part focuses on security and access patterns compared in the context of self hosted vs byok. This section starts with the practical reality most teams meet in the first week, which is that the idea sounds simple until real limits, real logs, and real teammates enter the picture. The key is to separate what the vendor controls from what you control, because that split decides where time goes and where money goes. For teams working on self hosted vs byok, security and access patterns compared repays careful setup. Start by writing down your current baseline, including how many URLs you publish per week, how many need fast discovery, and how you confirm discovery today. Teams that skip the baseline often overbuild, buying capacity they never use, or underbuild, queuing URLs that needed same day crawling. What this covers in practice:
- Demand first: map URL types to priority tiers so high value pages submit first and low value pages wait without blocking the queue. Applied to security and access patterns compared, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Quota aware: check quota in your own project console before launch and set alerts at 60 percent and 85 percent of daily use. Applied to security and access patterns compared, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Logged fully: store request IDs, response codes, and timestamps for every submission so debugging takes minutes instead of days. Applied to security and access patterns compared, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Retried safely: use exponential backoff with jitter on 429 responses and cap retries so a burst does not turn into a ban. Applied to security and access patterns compared, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Reviewed weekly: review success rate, crawl latency, and index coverage weekly and adjust batch size based on what the logs show. Applied to security and access patterns compared, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
Use the table below to turn security and access patterns compared into numbers your team can track for self hosted vs byok.
| Field | Typical value | How to use it |
|---|---|---|
| Input | Example value | What to verify for security and access patterns compared |
| URL count per week | 400 new plus 900 updates | Count by template and priority before sizing quota for security and access patterns compared |
| Quota headroom | 40 percent unused on peak day | Keep buffer for launches and bulk fixes for security and access patterns compared |
| Log retention | 90 days searchable | Keep request ID plus response code plus timestamp for security and access patterns compared |
| Review cadence | Weekly 30 minutes | Owner plus metric plus action list in one doc for security and access patterns compared |
Once the baseline is clear, look at the failure modes, because averages hide the cases that consume most support time. Each failure has a different owner, which means auth failures go to the cloud admin, content failures go to the CMS owner, and queue failures go to the engineer who runs the worker.
Practical steps to apply this week:
- List all URL sources that should trigger submission, including CMS publish events, deploy hooks, sitemap diffs, and manual backfill lists. Relate each step to security and access patterns compared so progress on self hosted vs byok stays visible to content and engineering alike.
- Assign each source a priority tier and a daily cap so one noisy source cannot consume the full quota before important pages submit. Relate each step to security and access patterns compared so progress on self hosted vs byok stays visible to content and engineering alike.
- Wire logging before automation, because you want visibility on day one rather than after the first incident. Relate each step to security and access patterns compared so progress on self hosted vs byok stays visible to content and engineering alike.
- Run a small pilot of 50 to 100 URLs, measure submission to crawl latency, then scale batch size in controlled steps. Relate each step to security and access patterns compared so progress on self hosted vs byok stays visible to content and engineering alike.
To close the loop, tie this section back to weekly operations, because strategy without a cadence fades within a month. Pick one metric, one owner, and one review point, such as submission success rate reviewed every Monday by the SEO lead.
In short, treat security and access patterns compared as an operating habit for self hosted vs byok, not a one time setting. Small weekly reviews beat large quarterly fixes, and steady logs beat heroic debugging. A minimal cost and quota tracker keeps math honest. The snippet below estimates daily load and flags when a pilot needs a larger buffer.
# estimate daily load vs quota, no network calls
new_urls = 120
updates = 340
deletions = 15
total = new_urls + updates + deletions
quota = 200
buffer = 0.4
needed = total / (1.0 - buffer)
print(f"total={total} needed_with_buffer={needed:.0f} quota={quota}")
print("scale pilot" if needed > quota else "pilot fits")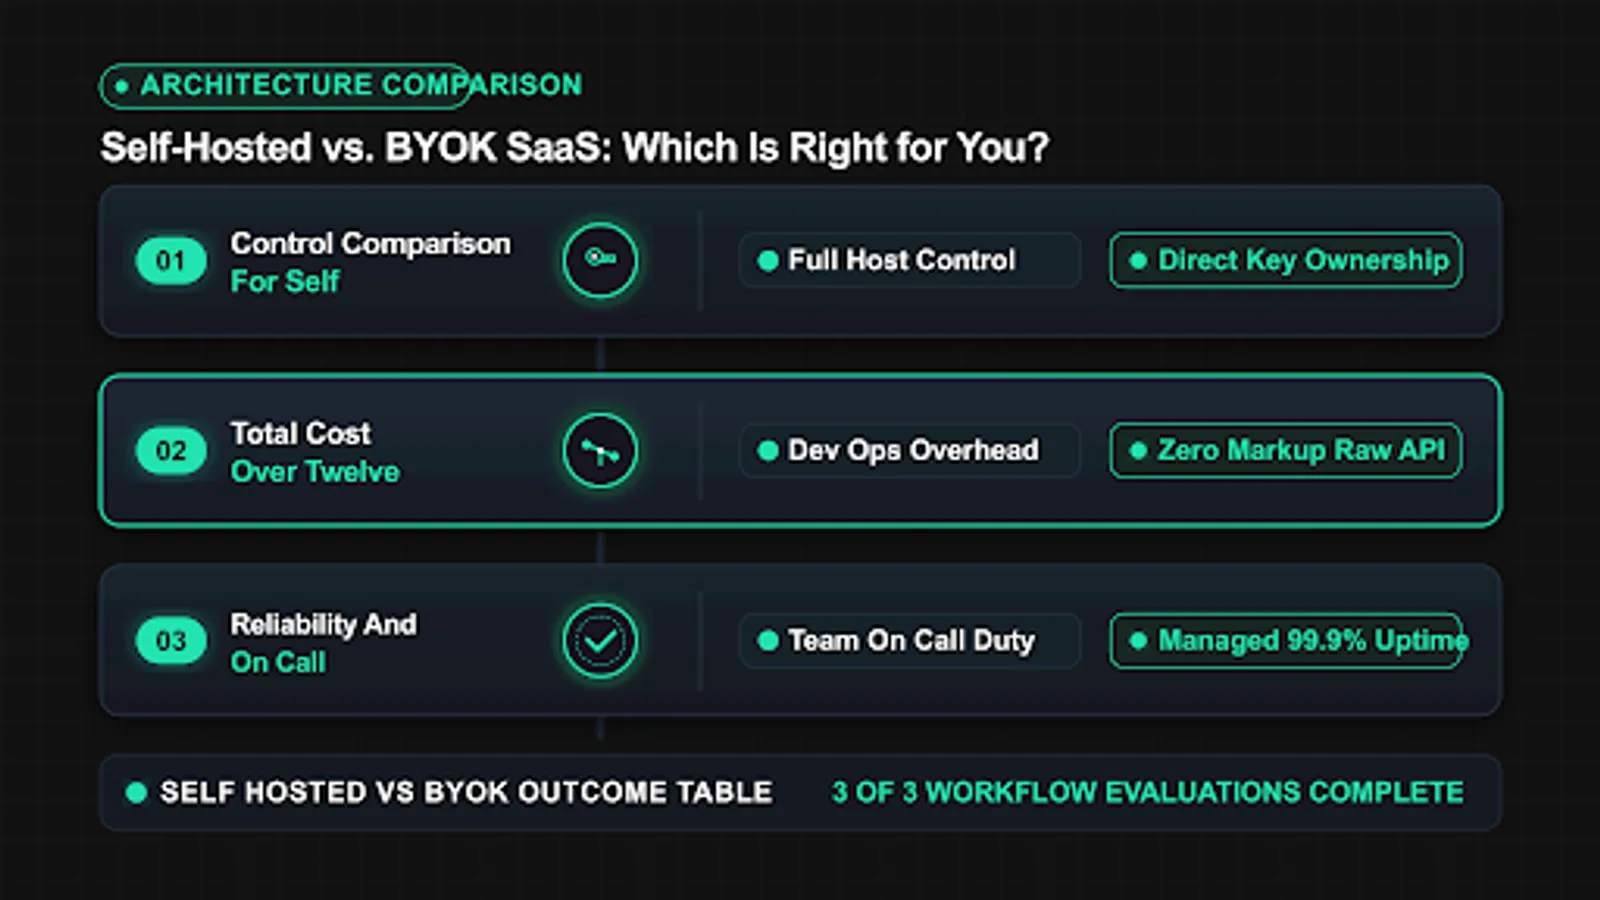 <!-- IMAGE-PROMPT workflow-02: 1600px max, DependsIt brand, mint #22E3B0 on charcoal #121212, node-network line art, Clash Display and General Sans feel, subject: self hosted vs byok workflow from publish to queue to submission, flat vector, accessible, no em dash -->
Reliability and on call burden
This part focuses on reliability and on call burden in the context of self hosted vs byok. The key is to separate what the vendor controls from what you control, because that split decides where time goes and where money goes. Most guides skip this split and talk only about features, which leaves readers surprised by follow up work that was predictable from the start. For teams working on self hosted vs byok, reliability and on call burden repays careful setup. That baseline matters more than any benchmark, because your mix of new pages, updates, and deletions sets the load you place on any submission path. A simple spreadsheet with URL counts by type and by priority gives you a demand curve you can match against quota and staffing. What this covers in practice:
- Demand first: map URL types to priority tiers so high value pages submit first and low value pages wait without blocking the queue. Applied to reliability and on call burden, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Quota aware: check quota in your own project console before launch and set alerts at 60 percent and 85 percent of daily use. Applied to reliability and on call burden, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Logged fully: store request IDs, response codes, and timestamps for every submission so debugging takes minutes instead of days. Applied to reliability and on call burden, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Retried safely: use exponential backoff with jitter on 429 responses and cap retries so a burst does not turn into a ban. Applied to reliability and on call burden, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Reviewed weekly: review success rate, crawl latency, and index coverage weekly and adjust batch size based on what the logs show. Applied to reliability and on call burden, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
Use the table below to turn reliability and on call burden into numbers your team can track for self hosted vs byok.
| Field | Typical value | How to use it |
|---|---|---|
| Input | Example value | What to verify for reliability and on call burden |
| URL count per week | 400 new plus 900 updates | Count by template and priority before sizing quota for reliability and on call burden |
| Quota headroom | 40 percent unused on peak day | Keep buffer for launches and bulk fixes for reliability and on call burden |
| Log retention | 90 days searchable | Keep request ID plus response code plus timestamp for reliability and on call burden |
| Review cadence | Weekly 30 minutes | Owner plus metric plus action list in one doc for reliability and on call burden |
Common failure modes include expired credentials, revoked Search Console access, malformed URL lists, duplicate submissions, and silent drops where a 200 response did not lead to a crawl. Document the owner next to each alert, because pages at 2am get fixed faster when the runbook names a role instead of a team.
Practical steps to apply this week:
- List all URL sources that should trigger submission, including CMS publish events, deploy hooks, sitemap diffs, and manual backfill lists. Relate each step to reliability and on call burden so progress on self hosted vs byok stays visible to content and engineering alike.
- Assign each source a priority tier and a daily cap so one noisy source cannot consume the full quota before important pages submit. Relate each step to reliability and on call burden so progress on self hosted vs byok stays visible to content and engineering alike.
- Wire logging before automation, because you want visibility on day one rather than after the first incident. Relate each step to reliability and on call burden so progress on self hosted vs byok stays visible to content and engineering alike.
- Run a small pilot of 50 to 100 URLs, measure submission to crawl latency, then scale batch size in controlled steps. Relate each step to reliability and on call burden so progress on self hosted vs byok stays visible to content and engineering alike.
Pick one metric, one owner, and one review point, such as submission success rate reviewed every Monday by the SEO lead. Add a second metric only after the first stays green for four weeks, because too many dashboards hide the signal that matters.
In short, treat reliability and on call burden as an operating habit for self hosted vs byok, not a one time setting. Small weekly reviews beat large quarterly fixes, and steady logs beat heroic debugging. For engine side behavior, the MDN HTTP status code reference gives the complementary view to your own logs.
Scaling from hundreds to millions of URLs
This part focuses on scaling from hundreds to millions of urls in the context of self hosted vs byok. Most guides skip this split and talk only about features, which leaves readers surprised by follow up work that was predictable from the start. A calm way to read this topic is to track three things together, which are quota, labor, and risk, and to review them on the same page. For teams working on self hosted vs byok, scaling from hundreds to millions of urls repays careful setup. Teams that skip the baseline often overbuild, buying capacity they never use, or underbuild, queuing URLs that needed same day crawling. Keep that sheet for a month, because patterns in publishing cadence show up quickly and they guide every later choice in this guide. What this covers in practice:
- Demand first: map URL types to priority tiers so high value pages submit first and low value pages wait without blocking the queue. Applied to scaling from hundreds to millions of urls, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Quota aware: check quota in your own project console before launch and set alerts at 60 percent and 85 percent of daily use. Applied to scaling from hundreds to millions of urls, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Logged fully: store request IDs, response codes, and timestamps for every submission so debugging takes minutes instead of days. Applied to scaling from hundreds to millions of urls, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Retried safely: use exponential backoff with jitter on 429 responses and cap retries so a burst does not turn into a ban. Applied to scaling from hundreds to millions of urls, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Reviewed weekly: review success rate, crawl latency, and index coverage weekly and adjust batch size based on what the logs show. Applied to scaling from hundreds to millions of urls, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
Use the table below to turn scaling from hundreds to millions of urls into numbers your team can track for self hosted vs byok.
| Field | Typical value | How to use it |
|---|---|---|
| Input | Example value | What to verify for scaling from hundreds to millions of urls |
| URL count per week | 400 new plus 900 updates | Count by template and priority before sizing quota for scaling from hundreds to millions of urls |
| Quota headroom | 40 percent unused on peak day | Keep buffer for launches and bulk fixes for scaling from hundreds to millions of urls |
| Log retention | 90 days searchable | Keep request ID plus response code plus timestamp for scaling from hundreds to millions of urls |
| Review cadence | Weekly 30 minutes | Owner plus metric plus action list in one doc for scaling from hundreds to millions of urls |
Each failure has a different owner, which means auth failures go to the cloud admin, content failures go to the CMS owner, and queue failures go to the engineer who runs the worker. Over time this list becomes your reliability checklist, and it pays for itself by cutting repeat incidents that otherwise eat sprint capacity.
Practical steps to apply this week:
- List all URL sources that should trigger submission, including CMS publish events, deploy hooks, sitemap diffs, and manual backfill lists. Relate each step to scaling from hundreds to millions of urls so progress on self hosted vs byok stays visible to content and engineering alike.
- Assign each source a priority tier and a daily cap so one noisy source cannot consume the full quota before important pages submit. Relate each step to scaling from hundreds to millions of urls so progress on self hosted vs byok stays visible to content and engineering alike.
- Wire logging before automation, because you want visibility on day one rather than after the first incident. Relate each step to scaling from hundreds to millions of urls so progress on self hosted vs byok stays visible to content and engineering alike.
- Run a small pilot of 50 to 100 URLs, measure submission to crawl latency, then scale batch size in controlled steps. Relate each step to scaling from hundreds to millions of urls so progress on self hosted vs byok stays visible to content and engineering alike.
Add a second metric only after the first stays green for four weeks, because too many dashboards hide the signal that matters. Write the decision you made and the reason in a short log, so future teammates understand why the current setup looks the way it does.
In short, treat scaling from hundreds to millions of urls as an operating habit for self hosted vs byok, not a one time setting. Small weekly reviews beat large quarterly fixes, and steady logs beat heroic debugging. A small retry helper with backoff prevents 429 loops from consuming the day quota. Keep attempts capped and log every skip with a reason.
import time, random
def submit_with_backoff(calls, quota=200):
    used = 0
    for url in calls:
        if used >= quota:
            print("quota reached, queue remainder")
            break
        # place real publish call here, then handle 429 with sleep
        wait = min(60, (2 ** min(4, used % 5)) + random.random())
        # time.sleep(wait) on 429 only
        used += 1
    return used
Team skills that tip the decision
This part focuses on team skills that tip the decision in the context of self hosted vs byok. A calm way to read this topic is to track three things together, which are quota, labor, and risk, and to review them on the same page. When those three are visible, decisions get easier, because trade offs stop hiding inside vague claims about automation or scale. For teams working on self hosted vs byok, team skills that tip the decision repays careful setup. In a byok vs self hosting review, backend teams value byok flexibility for key control, while content led teams prefer fewer deploys and clearer runbooks. What this covers in practice:
- Demand first: map URL types to priority tiers so high value pages submit first and low value pages wait without blocking the queue. Applied to team skills that tip the decision, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Quota aware: check quota in your own project console before launch and set alerts at 60 percent and 85 percent of daily use. Applied to team skills that tip the decision, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Logged fully: store request IDs, response codes, and timestamps for every submission so debugging takes minutes instead of days. Applied to team skills that tip the decision, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Retried safely: use exponential backoff with jitter on 429 responses and cap retries so a burst does not turn into a ban. Applied to team skills that tip the decision, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Reviewed weekly: review success rate, crawl latency, and index coverage weekly and adjust batch size based on what the logs show. Applied to team skills that tip the decision, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
Use the table below to turn team skills that tip the decision into numbers your team can track for self hosted vs byok.
| Field | Typical value | How to use it |
|---|---|---|
| Input | Example value | What to verify for team skills that tip the decision |
| URL count per week | 400 new plus 900 updates | Count by template and priority before sizing quota for team skills that tip the decision |
| Quota headroom | 40 percent unused on peak day | Keep buffer for launches and bulk fixes for team skills that tip the decision |
| Log retention | 90 days searchable | Keep request ID plus response code plus timestamp for team skills that tip the decision |
| Review cadence | Weekly 30 minutes | Owner plus metric plus action list in one doc for team skills that tip the decision |
Document the owner next to each alert, because pages at 2am get fixed faster when the runbook names a role instead of a team. Once the baseline is clear, look at the failure modes, because averages hide the cases that consume most support time.
Practical steps to apply this week:
- List all URL sources that should trigger submission, including CMS publish events, deploy hooks, sitemap diffs, and manual backfill lists. Relate each step to team skills that tip the decision so progress on self hosted vs byok stays visible to content and engineering alike.
- Assign each source a priority tier and a daily cap so one noisy source cannot consume the full quota before important pages submit. Relate each step to team skills that tip the decision so progress on self hosted vs byok stays visible to content and engineering alike.
- Wire logging before automation, because you want visibility on day one rather than after the first incident. Relate each step to team skills that tip the decision so progress on self hosted vs byok stays visible to content and engineering alike.
- Run a small pilot of 50 to 100 URLs, measure submission to crawl latency, then scale batch size in controlled steps. Relate each step to team skills that tip the decision so progress on self hosted vs byok stays visible to content and engineering alike.
Write the decision you made and the reason in a short log, so future teammates understand why the current setup looks the way it does. That habit keeps the system explainable, which matters more than cleverness once multiple people touch the same pipeline.
In short, treat team skills that tip the decision as an operating habit for self hosted vs byok, not a one time setting. Small weekly reviews beat large quarterly fixes, and steady logs beat heroic debugging.
A decision matrix you can use this week
This part focuses on a decision matrix you can use this week in the context of self hosted vs byok. When those three are visible, decisions get easier, because trade offs stop hiding inside vague claims about automation or scale. This section starts with the practical reality most teams meet in the first week, which is that the idea sounds simple until real limits, real logs, and real teammates enter the picture. For teams working on self hosted vs byok, a decision matrix you can use this week repays careful setup. Keep that sheet for a month, because patterns in publishing cadence show up quickly and they guide every later choice in this guide. That baseline matters more than any benchmark, because your mix of new pages, updates, and deletions sets the load you place on any submission path. What this covers in practice:
- Demand first: map URL types to priority tiers so high value pages submit first and low value pages wait without blocking the queue. Applied to a decision matrix you can use this week, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Quota aware: check quota in your own project console before launch and set alerts at 60 percent and 85 percent of daily use. Applied to a decision matrix you can use this week, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Logged fully: store request IDs, response codes, and timestamps for every submission so debugging takes minutes instead of days. Applied to a decision matrix you can use this week, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Retried safely: use exponential backoff with jitter on 429 responses and cap retries so a burst does not turn into a ban. Applied to a decision matrix you can use this week, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
- Reviewed weekly: review success rate, crawl latency, and index coverage weekly and adjust batch size based on what the logs show. Applied to a decision matrix you can use this week, this means fewer surprises during launches and clearer ownership when self hosted vs byok work spikes.
Use the table below to turn a decision matrix you can use this week into numbers your team can track for self hosted vs byok.
| Field | Typical value | How to use it |
|---|---|---|
| Input | Example value | What to verify for a decision matrix you can use this week |
| URL count per week | 400 new plus 900 updates | Count by template and priority before sizing quota for a decision matrix you can use this week |
| Quota headroom | 40 percent unused on peak day | Keep buffer for launches and bulk fixes for a decision matrix you can use this week |
| Log retention | 90 days searchable | Keep request ID plus response code plus timestamp for a decision matrix you can use this week |
| Review cadence | Weekly 30 minutes | Owner plus metric plus action list in one doc for a decision matrix you can use this week |
Over time this list becomes your reliability checklist, and it pays for itself by cutting repeat incidents that otherwise eat sprint capacity. Common failure modes include expired credentials, revoked Search Console access, malformed URL lists, duplicate submissions, and silent drops where a 200 response did not lead to a crawl.
Practical steps to apply this week:
- List all URL sources that should trigger submission, including CMS publish events, deploy hooks, sitemap diffs, and manual backfill lists. Relate each step to a decision matrix you can use this week so progress on self hosted vs byok stays visible to content and engineering alike.
- Assign each source a priority tier and a daily cap so one noisy source cannot consume the full quota before important pages submit. Relate each step to a decision matrix you can use this week so progress on self hosted vs byok stays visible to content and engineering alike.
- Wire logging before automation, because you want visibility on day one rather than after the first incident. Relate each step to a decision matrix you can use this week so progress on self hosted vs byok stays visible to content and engineering alike.
- Run a small pilot of 50 to 100 URLs, measure submission to crawl latency, then scale batch size in controlled steps. Relate each step to a decision matrix you can use this week so progress on self hosted vs byok stays visible to content and engineering alike.
That habit keeps the system explainable, which matters more than cleverness once multiple people touch the same pipeline. To close the loop, tie this section back to weekly operations, because strategy without a cadence fades within a month.
In short, treat a decision matrix you can use this week as an operating habit for self hosted vs byok, not a one time setting. Small weekly reviews beat large quarterly fixes, and steady logs beat heroic debugging.
FAQ
How does byok vs self hosting change ownership?
For self hosted vs byok, the short answer is to start from your own numbers before trusting defaults. Count weekly new URLs, updates, and deletions, then map them to quota and staffing. Next, put one owner on the metric that matters most for this question, which is usually submission success rate or time from publish to crawl. Review it weekly for a month before adding more dashboards. Self hosted means you own code, hosting, keys, logs, and on call, while BYOK keeps tool ownership for keys and policy with the vendor running UI and workers. Control shifts from code to configuration. Keep the implementation simple at first. One queue, one log with request ID and response code, and one retry policy with backoff will carry most teams further than a complex多 worker setup. Finally, write down what you decided and why. That note lets future teammates keep the system stable when publishing cadence changes or when a launch creates a burst that needs triage.
How long does each option take to launch?
For self hosted vs byok, the short answer is to start from your own numbers before trusting defaults. Count weekly new URLs, updates, and deletions, then map them to quota and staffing. Next, put one owner on the metric that matters most for this question, which is usually submission success rate or time from publish to crawl. Review it weekly for a month before adding more dashboards. Self hosted pilots take one to three weeks including auth, queue, and observability. BYOK pilots often submit the same day after key paste and domain verification, with the rest of the week spent on CMS hooks. Keep the implementation simple at first. One queue, one log with request ID and response code, and one retry policy with backoff will carry most teams further than a complex多 worker setup. Finally, write down what you decided and why. That note lets future teammates keep the system stable when publishing cadence changes or when a launch creates a burst that needs triage.
Is saas vs self hosted a control vs convenience trade off?
For self hosted vs byok, the short answer is to start from your own numbers before trusting defaults. Count weekly new URLs, updates, and deletions, then map them to quota and staffing. Next, put one owner on the metric that matters most for this question, which is usually submission success rate or time from publish to crawl. Review it weekly for a month before adding more dashboards. Security depends on implementation rather than label. Self hosted wins when you have strong secret management and review. BYOK wins when the vendor offers scoped keys, encryption at rest, audit logs, and easy revocation that you would take weeks to build. Keep the implementation simple at first. One queue, one log with request ID and response code, and one retry policy with backoff will carry most teams further than a complex多 worker setup. Finally, write down what you decided and why. That note lets future teammates keep the system stable when publishing cadence changes or when a launch creates a burst that needs triage.
Which option scales better?
For self hosted vs byok, the short answer is to start from your own numbers before trusting defaults. Count weekly new URLs, updates, and deletions, then map them to quota and staffing. Next, put one owner on the metric that matters most for this question, which is usually submission success rate or time from publish to crawl. Review it weekly for a month before adding more dashboards. Both scale, but the bottleneck moves. Self hosted scaling means workers, queues, and rate limit tuning. BYOK scaling means quota planning and tier selection. Millions of URLs favor whoever has better batching and logging. Keep the implementation simple at first. One queue, one log with request ID and response code, and one retry policy with backoff will carry most teams further than a complex多 worker setup. Finally, write down what you decided and why. That note lets future teammates keep the system stable when publishing cadence changes or when a launch creates a burst that needs triage.
Do self hosted seo tools need you to maintain own scripts?
For self hosted vs byok, the short answer is to start from your own numbers before trusting defaults. Count weekly new URLs, updates, and deletions, then map them to quota and staffing. Next, put one owner on the metric that matters most for this question, which is usually submission success rate or time from publish to crawl. Review it weekly for a month before adding more dashboards. Teams with backend plus DevOps comfort and spare on call capacity do well with self hosted seo tools because they can maintain own scripts, while content led teams favor BYOK and keep control of keys while renting the plumbing. Keep the implementation simple at first. One queue, one log with request ID and response code, and one retry policy with backoff will carry most teams further than a complex多 worker setup. Finally, write down what you decided and why. That note lets future teammates keep the system stable when publishing cadence changes or when a launch creates a burst that needs triage.
Does byok middle ground offer byok flexibility when switching?
For self hosted vs byok, the short answer is to start from your own numbers before trusting defaults. Count weekly new URLs, updates, and deletions, then map them to quota and staffing. Next, put one owner on the metric that matters most for this question, which is usually submission success rate or time from publish to crawl. Review it weekly for a month before adding more dashboards. Yes. The byok middle ground gives byok flexibility because URL sourcing stays portable and logs live in your warehouse, so a move is re pointing workers rather than rebuilding taxonomy. Keep the implementation simple at first. One queue, one log with request ID and response code, and one retry policy with backoff will carry most teams further than a complex多 worker setup. Finally, write down what you decided and why. That note lets future teammates keep the system stable when publishing cadence changes or when a launch creates a burst that needs triage.
Sources
- https://developers.google.com/search/docs/crawling-indexing/sitemaps/build-sitemap
- https://www.indexnow.org/documentation
- https://developer.mozilla.org/en-US/docs/Web/HTTP/Status