Generative Engine Optimization (GEO): The Beginner's Guide
This guide introduces generative engine optimization for teams that want their content cited inside AI generated answers. It is for SEOs, content leads, and founders who understand classic search and need a plain starting point for ChatGPT, Perplexity, and similar assistants. You will learn how GEO differs from SEO, which tactics actually influence citations, how to prioritize work, and how to measure progress without guesswork.
Key takeaways
- GEO focuses on earning citations inside synthesized answers, while classic SEO focuses on ranking pages in result lists.
- The same foundations drive both: crawl access, clear structure, useful content, and evidence that readers can verify.
- Answer first pages with tables, steps, dates, and scope notes earn more citations than long opinion pieces without facts.
- Start with ten high value prompts, improve one canonical page per prompt, and track citation share weekly.
- Report GEO with ranges and methods, because prompts vary by user, region, and time.
- What GEO is and how it differs from SEO
- How generative engines build answers
- Which content types earn citations
- Page structure that models can reuse
- Evidence authority and freshness
- Technical access for answer engines
- Prioritizing prompts and pages
- Writing and rewriting for generative engine optimization
- Measuring citations traffic and value
- A starter plan for the first 30 days
- FAQ
 <!-- IMAGE-PROMPT cover: 1200x630, DependsIt brand, deep charcoal #121212 or clean white background, vibrant mint #22E3B0 accent glow, thin node-network line art, Clash Display style bold heading space on left, General Sans clean labels, subject: web pages distilled into AI answer with cited sources, flat vector, high contrast, accessible, no photorealistic faces, no text smaller than 24px, no em dash in rendered text, export PNG then cwebp -q 82 to WEBP -->
What GEO is and how it differs from SEO
Generative engine optimization, often shortened to GEO, is the practice of making your content easy for AI assistants to retrieve and cite when they compose answers. Classic SEO asks how a page ranks for a query in a list of results. GEO asks whether passages from the page appear as sources inside a synthesized answer, with a link the reader can follow. Both care about visibility, but the unit of success differs. SEO wins clicks from a results page. GEO wins citations inside an answer that may satisfy the user before any click.
The overlap is larger than the difference. Assistants retrieve from web indexes that depend on crawling, structure, and quality signals familiar from SEO. Pages that are blocked, slow, duplicated, or thin rarely earn citations, just as they rarely rank. Internal linking, sitemaps, canonicals, and rendering hygiene help both. Teams with strong SEO foundations usually see faster GEO progress than teams starting from a messy site. The new work sits on top: shaping pages so models can extract short, self contained, verifiable passages and attribute them correctly.
Intent handling also differs. Classic search maps one query to a ranked list where the user chooses. Generative engines map one prompt to a composed answer that blends several sources. That means a page does not need to be the single best result to earn value. It can win by being the clearest source for one subquestion, such as prerequisites, limits, error fixes, or version notes, even if a larger publisher covers the broader topic. Specialists benefit from this dynamic when they own narrow tasks fully rather than publishing shallow overviews of everything.
Another difference is presentation. In classic results, title and snippet decide clicks. In AI answers, the model decides which passages to quote and how to phrase the synthesis. Clear headings, short paragraphs, tables, and explicit scope notes give the model quotable material. Long introductions, mixed opinion with fact, and key details split across sections make quotation harder. Writing for GEO means writing so that any single paragraph still makes sense when retrieved alone, with its conditions and dates included.
Measurement differs too. SEO tracks rankings, impressions, and clicks per query. GEO tracks citation frequency for a set of prompts, which URLs are cited, and what happens after the citation in terms of qualified visits. Prompt outputs vary between runs, so GEO reporting uses ranges and repeated tests rather than single snapshots. The goal is citation share for tasks that matter to the business, not vanity coverage for broad prompts that never convert. This focus keeps effort tied to outcomes.
A final distinction is control. You control your pages, structure, and facts. You do not control how models weigh sources or phrase answers. GEO improves odds through eligibility, clarity, and evidence, but it cannot guarantee placement for any single prompt. Honest planning treats GEO as a portfolio: improve ten canonical pages, test twenty prompts, and expect gradual gains in citation share over one to two quarters. That framing avoids disappointment and builds steady support for the work that actually moves results.
When teams compare geo vs seo in planning meetings, the clearest summary is that SEO earns a place in a list while GEO earns a sentence inside an answer. A practical geo seo routine therefore starts with classic hygiene such as crawl access and internal links, then adds answer first rewrites for ten priority pages. The approach in this generative engine optimization guide keeps both channels in one backlog instead of two competing projects.
How generative engines build answers
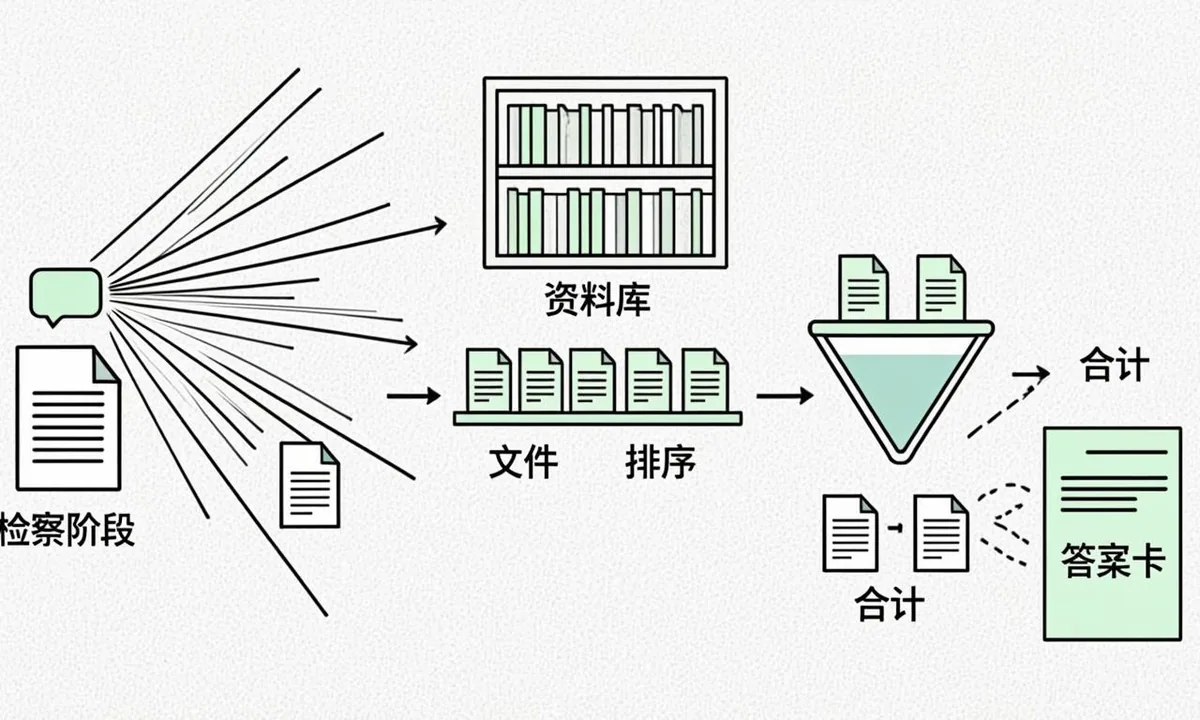
Most generative engines follow a similar pipeline. They interpret the prompt, retrieve candidate passages from web indexes or vector stores, rank those passages for relevance and reliability, and then generate an answer that synthesizes the best pieces with citations. Some systems lean on training knowledge for stable topics and call live retrieval only when freshness matters. Others retrieve live for almost every query. In all cases, retrieval decides which pages can be cited, and generation decides how they are presented. Optimization must serve both stages.
Query understanding shapes retrieval. The engine expands the prompt into subquestions, such as definition, steps, requirements, limits, and alternatives, then seeks passages for each. Pages that explicitly cover those subquestions with matching headings earn more retrievals than pages that cover only the main term. For a how to prompt, steps with preconditions and expected outcomes match well. For a comparison prompt, criteria tables match well. For a troubleshooting prompt, error messages with fixes match well. Mapping each target prompt to its likely subquestions before writing keeps coverage complete.
Passage ranking favors directness, completeness, and trust. A passage that states the answer plus its scope in 40 to 70 words outranks a longer passage where the answer is implied. A passage with numbers, dates, and named entities outranks vague claims. A passage from a page with consistent titles, authors, dates, and primary source links outranks a similar passage without those cues. Recency matters more for procedures, prices, and compatibility than for stable definitions. Structure your pages so the ranker finds such passages without having to assemble them from fragments.
Generation then blends selected passages into fluent text. Models prefer passages they can quote with little editing, because heavy rewriting increases the risk of errors. Short self contained paragraphs, one fact per table cell, and list items that include their own context survive this step best. Passages that depend on earlier paragraphs for meaning often get summarized rather than cited, and summaries link less reliably. Writing each block to stand alone improves both accuracy and attribution.
Citations themselves follow system rules you cannot set, but you can make them easier. Stable URLs with clear titles help models link correctly. Visible dates and version notes help them choose the current source among similar candidates. Consistent naming for products, features, and codes prevents misattribution. When several sources cover the same facts, these small trust signals decide tie breaks. They do not require new tools, only consistent templates and review.
Understanding this pipeline prevents wasted tactics. Keyword repetition without structure does not help passage ranking. Hidden text does not survive verification. Separate pages per assistant split signals and hurt all engines. The durable levers are eligibility for crawling, retrievability of passages, and quotability of facts. Every GEO task in this guide maps to one of those three, which keeps the program focused on changes that affect the pipeline rather than surface tweaks.
Teams that treat ai answer optimization as passage ranking plus quotable writing make faster progress than teams that chase generic tips. In practice, generative search seo work overlaps here because the same clear headings and tables that help classic crawlers also help answer rankers select passages.
 <!-- IMAGE-PROMPT diagram-01: 1600px max, DependsIt brand mint #22E3B0 on charcoal #121212 or white, node-network line art, subject: prompt expanded to subquestions matched to passages then synthesized answer with citations, flat vector, accessible, no em dash -->
Which content types earn citations
Not all formats earn citations equally. Task focused guides earn the most, because they match how people prompt assistants: how to complete a task, what the requirements are, what the limits cost, and how to fix errors. Reference pages earn well for factual prompts about codes, fields, endpoints, and definitions. Comparisons earn well when they use defined criteria and current data. Troubleshooting pages earn well when they pair exact error text with causes and fixes. Opinion pieces without verifiable facts earn the least, because there is little to quote safely.
How to guides work when they are complete on one URL. Cover prerequisites, exact steps in order, expected output after each step, common errors, and limits. State the tested version and date. Use numbered lists where order matters, with each item starting with the action and including inputs. Close with next actions and related tasks. A guide that forces the reader to open three more pages to finish the task will lose citations to a guide that completes the task in one place. Completeness on a single canonical URL is a GEO advantage.
Reference content works when it is precise and current. Each entry should define the item, state its scope, list allowed values or formats, and note version changes. Tables suit this well, with one fact per cell and clear headers. Keep units, date formats, and code names exact. Link each section to primary specs where relevant so the answer can pair your practical summary with an authoritative source. Stale reference pages are risky, because models repeat their facts. Review them on a fixed schedule and show verification dates in visible text.
Comparisons work when criteria are explicit and fair. Define the use case first, then compare options on the same dimensions, such as price, limits, setup effort, and support for specific features. Use tables with the same units across rows. State the date you checked and where readers can recheck. Avoid vague winners without conditions. Conditional conclusions such as best for a stated need with stated limits are more citable than absolute claims, because assistants can repeat the condition alongside the recommendation without misleading.
Troubleshooting pages work when they start from observable symptoms. Lead with the exact error message or behavior, then list likely causes in order, each with a check and a fix. Include commands or menu paths that match the current interface and describe what success looks like after the fix. Group related errors so the model can distinguish them. These pages earn citations for long tail prompts that larger publishers ignore, which makes them efficient GEO targets for specialist sites.
Choose formats based on prompt value, not volume. Ten complete task pages that match high intent prompts outperform fifty thin posts that restate the same background. Audit existing content for quotability: does the first screen state the answer, does each fact sit with its context, can a paragraph be quoted alone. Upgrade the pages closest to revenue or support deflection first. Among proven geo tactics, the highest return comes from completing troubleshooting pages with exact error text and from adding comparison tables with current dates. These focused upgrades turn existing drafts into citable sources without requiring new sections. The patterns for answer first structure are detailed in the broader overview of AI search indexing for ChatGPT and Perplexity.
Page structure that models can reuse
Structure decides whether a strong draft becomes citable. Start with a specific H1 that names the task and scope, not a brand slogan. Open with a direct answer of one to two sentences that states the conclusion. Follow with prerequisites or scope notes so readers know whether the answer applies to them. Then present steps, tables, or criteria in order. Close each major section with limits and next actions. This answer first shape serves both skimmers and retrievers.
Headings should mirror user questions. Phrase H2s as tasks such as requirements, setup steps, limits, errors, and verification. Phrase H3s as steps within each task. Parallel wording across sections helps both humans and machines scan. Avoid vague headings such as Overview or Details that give retrieval nothing to match. Each heading should make sense out of context, because passage rankers often see headings alongside candidate paragraphs when scoring.
Paragraphs should stay short and self contained. Aim for 40 to 70 words per paragraph, one idea per block, with conditions and dates included rather than assumed from earlier text. A paragraph about a limit should name what the limit applies to, the value, and when it resets. A paragraph about a step should name its precondition and expected result. Read each paragraph alone and ask whether it still makes sense. If it relies on the previous paragraph for meaning, add the missing context. This habit alone lifts citation rates for many sites.
Lists and tables need introductions and consistent forms. Introduce each list with one sentence stating what it covers and its scope. Start ordered steps with verbs and include inputs and outputs. Keep unordered items parallel and complete. For tables, use header cells, short cell text, and consistent units. One fact per cell lets models cite precisely. Long merged cells force broad quotations that are less useful. After building a table, check the text only version to confirm headers still align with rows when styles are removed.
Close pages with provenance and navigation. Show author or team, publication date, and last update in visible text. Link to primary sources for specs and to related canonical guides for next tasks. Keep related links contextual rather than a generic dump. To optimize for ai answers, keep the direct conclusion in the first screen and repeat scope notes with each fact so retrieved passages stay correct when quoted alone. This habit also helps human skimmers who decide in seconds whether the page solves their task. A calm ending with clear next steps helps the model see how your pages relate and helps readers continue without bouncing to competitors for the follow up question.
Evidence authority and freshness
Citations favor pages that show their work. For each important claim, include the evidence a skeptical reader would need: numbers with units and dates, steps with expected outputs, or a link to the primary doc that defines the behavior. Attribute third party claims clearly. Separate tested findings from general advice with labels such as tested, observed, or reported. This transparency lets assistants repeat facts with appropriate hedging and lets readers verify without hunting. Pages that assert without support lose tie breaks to pages that document.
Authority here means relevance plus consistency, not fame alone. A small specialist that tests procedures and reports methods can outrank larger publishers for narrow tasks. Strengthen that position with author bios that state real experience, about pages that explain scope, and consistent details across articles. Keep names, prices, limits, and version notes identical wherever they repeat. Inconsistencies force models to choose, and they may choose a competitor with cleaner agreement. Quarterly consistency checks catch drift before it costs citations.
Freshness signals tell retrieval whether the page reflects current behavior. Show publication and update dates in both visible text and valid markup that agree. For versioned topics, state the tested version and summarize what changed since the prior version. For prices and limits, state the verification date and where to recheck. Add update notes rather than silently rewriting history for news like changes. Touching dates without changing content erodes trust when crawlers compare snapshots, so only update dates when substance changes.
Evidence placement matters as much as presence. Put the key number next to what it measures, the date next to what happened, and the condition next to the claim it limits. Do not separate facts from their scope across distant sections. When a fact has exceptions, state them in the same block. Explicit scope prevents misquotation where a model applies a plan specific limit to all plans or a version specific step to all versions. Precision protects both accuracy and your reputation when answers quote you.
Link out to primary sources for endpoints, quotas, and protocol claims. Use stable documentation rather than secondary roundups. Keep outbound links relevant and few, so the page reads as a coherent source rather than a link farm. Consistent evidence is the fastest lever for generative engine visibility because tie breaks among similar passages favor pages with numbers, dates, and primary source links. When two pages state the same fact, the one that shows verification details in the same block usually wins the citation. For docs heavy topics, pair your practical steps with spec references so answers can cite your procedure and the spec together. This pairing is common in high quality AI answers and increases the chance your page is included as the practical source.
Technical access for answer engines
GEO cannot work if answer engines cannot fetch your pages. Confirm every canonical guide returns 200 to anonymous GET over HTTPS without long redirect chains. Check that AI search agents are allowed in robots.txt on public paths and that edge defenses do not challenge their fetches. Review firewall events by user agent for blocks affecting browsing and search agents while classic crawlers succeed. Keep public article HTML easy to fetch and reserve strict protection for login, POST, and API routes. Technical eligibility comes before any writing tactic.
Rendering is often the silent blocker. Many assistant fetchers parse server rendered HTML quickly but have limited patience for client side rendering. If main content appears only after scripts run, some systems will see partial text or an empty shell. Prefer server rendering or static generation for guide templates. Keep headings, paragraphs, lists, and tables in the initial HTML. Defer non critical scripts and test with JavaScript disabled to confirm the answer still reads coherently. Fast text first pages earn more retrievals than heavy interactive pages with the same words.
Canonicals and duplicates shape which URL gets cited. Keep one stable canonical per task with self referencing tags and consistent internal links. Avoid parameter variants, print views, and AMP forks in sitemaps. For series that must paginate, give each part a clear title and step range so retrieved passages map to the right URL. Update internal links to point directly at final URLs rather than through redirects. Stable canonicals preserve the link between stored passages and live pages that citations depend on.
Sitemaps and internal links control discovery speed. List only indexable canonicals with honest lastmod values that change when substance changes. Submit in both Google Search Console and Bing Webmaster Tools, since several retrieval stacks build on Bing data. Link new guides from at least three relevant existing pages at publish time and bring key hubs closer to the home page. The same linking discipline that speeds classic indexing also speeds answer engine discovery. Prune thin duplicates and dead URLs quarterly so crawl capacity concentrates on citable pages.
Monitor technical health continuously. Track robots.txt responses, sitemap validity, canonical stability, time to first byte for article templates, and text only content presence for a sample of high value URLs. Alert on template or firewall changes that affect fetch success. After migrations or theme updates, revalidate eligibility before assuming GEO performance will hold. Many citation losses trace to infrastructure edits that nobody linked to answers until referrals dropped weeks later.
Prioritizing prompts and pages
GEO works best as a focused portfolio, not a site wide rewrite. Start by listing the tasks that matter to revenue, support load, or authority in your niche. Convert each task into three to five realistic prompts as users would phrase them, including definition, procedure, comparison, troubleshooting, and limits variants. You will have 30 to 50 candidate prompts. Score each by business value, current citation presence, and page readiness. Pick ten prompts where value is high and a single canonical page could win with a focused rewrite. Depth on ten beats shallow edits on fifty.
Map one canonical URL to each chosen prompt. If two URLs compete for the same task, consolidate to one stronger page with redirects rather than optimizing both. If no URL exists, create one complete guide instead of splitting across several thin posts. Ensure each mapped URL is eligible, linked from relevant hubs, and present in sitemaps. This mapping becomes your GEO backlog. Review it monthly and promote only pages that have proven stable URLs and accurate facts.
Sequence work by expected lift and effort. Quick wins include tightening the opening answer, adding a missing comparison table, restating scope and dates with each fact, and fixing a blocking robots or rendering issue. Medium efforts include merging duplicates, adding error catalogs, and building version histories. Larger efforts include creating missing canonical guides for high value tasks with no good page. Timebox rewrites to avoid perfectionism. A focused two hour pass that improves quotability often moves citations more than a week long rebuild.
Coordinate with classic SEO rather than competing. The same canonical consolidation, internal linking, and freshness work helps both channels. Share keyword and prompt research so titles serve typed queries and spoken prompts together. Keep metadata accurate for both result snippets and answer selection. When trade offs arise, prefer clarity for humans first, because structures that help people skim usually help models retrieve. Avoid separate AI only pages that split signals and double maintenance.
Document decisions so the program compounds. For each target prompt, record the canonical URL, what changed, when it shipped, and what citation tests showed over the next four weeks. A simple geo strategy is to score thirty candidate prompts by revenue value and page readiness, then commit to ten prompts for one quarter. This narrow portfolio keeps rewriting, linking, and testing in one place where results compound instead of scattering across fifty thin pages. Note competitor pages that displaced you and what structure they used. Over a quarter, this log reveals which shapes work in your niche, such as tables for limits or step blocks for setup, and lets you apply winning patterns to the next batch without relearning. Steady iteration on a small set outperforms sporadic large projects.
Writing and rewriting for generative engine optimization
Good GEO writing is plain, specific, and verifiable. Lead with the answer in the first screen, then support it with conditions, steps, or data. Use short paragraphs where each block states one fact with its context. Prefer concrete nouns, numbers, and dates over adjectives. State scope explicitly in the same block as each claim. This style feels direct to humans and gives models clean passages to quote. It also exposes weak content quickly, because vague drafts cannot survive answer first restructuring without revealing gaps.
Rewrite in passes rather than all at once. First pass tightens the opening and headings to match target prompts. Second pass makes paragraphs self contained and adds missing scope notes. Third pass adds or fixes one table or checklist that the prompt needs. Fourth pass verifies facts, dates, links, and version notes. Each pass takes under an hour for a typical guide and produces a testable change. After each pass, run your fixed prompt set and record movement before the next edit. Isolated changes teach you what works in your niche faster than combined overhauls.
Examples and errors deserve concrete detail. Show exact menu labels, field names, paths, and sample values that match the current interface. Describe what success looks like after each step so readers and models can verify completion. Catalog common errors with their messages, causes, and fixes, because error passages earn long tail citations competitors ignore. Use clearly fake example values where redaction is needed and label them as examples. Assistants repeat examples, so accuracy here prevents propagated mistakes.
Tone stays neutral and helpful. Avoid superlatives and promotional claims that cannot be verified. Replace broad assertions with measured statements plus evidence. Link key claims to primary docs or to your own test notes with methods. Keep advertising and sponsored blocks visually separate from editorial steps so the main text reads as one coherent source. Calm specificity beats loud generality when models choose among similar candidates for the same prompt.
Templates lock in gains as teams grow. Define page types for guides, references, comparisons, and troubleshooting, each with required blocks for answer, prerequisites, steps or tables, limits, dates, authors, and sources. Require pre publish checks for crawl access, canonical, sitemap inclusion, and text only readability. Require post publish review after one week for early citation signals. These routines take minutes and prevent most avoidable misses while keeping voice consistent across authors.
Measuring citations traffic and value
Measure GEO with three layers: citation presence, referral quality, and business outcomes. For presence, run a fixed set of 15 to 30 prompts weekly in target assistants with consistent settings. Record whether your pages appear, which URLs are cited, and which competitors appear alongside. Track citation share per prompt over time rather than single wins. For referrals, segment visits by assistant hosts and landing pages in analytics. For outcomes, track assisted actions such as signups, purchases, docs success, or ticket deflection after AI referred visits. Together these show whether citations turn into value.
Stability matters in testing. Prompt outputs vary by account, region, and time, so use the same prompts, note the date, and report ranges over four week windows. Do not judge a rewrite after one run. Wait at least two crawl cycles and several test rounds. Change one page element at a time so you can attribute movement. Focus on prompts where business value justifies patience. Chasing every missing prompt spreads effort thin and invites noisy conclusions.
Competitor review turns losses into plans. When a competitor displaces you, open their page and note structure, freshness, and evidence. Often the gap is concrete: a clearer opening answer, a comparison table you lack, current dates where yours are stale, or faster rendering. Replicate the structural advantage on your canonical page rather than copying text. Then retest the same prompts for four weeks. Focused responses to concrete gaps recover citations faster than broad rewrites.
Connect results to stakeholders with honest reporting. Show citation share for target prompts, AI referral volume and quality by landing page, and downstream actions where measurable. State methods and limits, including prompt count, assistants tested, and variance. Avoid claiming exact attribution for influenced deals or deflected tickets without a defined method. Ranges with clear methods build trust and sustain investment better than single point wins that do not repeat.
Avoid common measurement traps. Do not rely on rank style trackers alone without checking actual answers, because citation context matters. Do not optimize for broad informational prompts with no path to value. Do not change five variables at once. Keep a simple sheet with date, prompt, assistant, cited URLs, and notes, plus analytics segments for referrals. Small consistent data beats elaborate dashboards that nobody updates. The pages that consistently earn citations for valuable tasks deserve more investment. The rest can wait.
A starter plan for the first 30 days
Week one focuses on foundations and selection. Audit robots.txt and edge rules for AI search agents, confirm rendering of main content without JavaScript, and fix any noindex or canonical conflicts on candidate guides. Build your prompt set of 20 to 30 realistic tasks and run a baseline citation test in ChatGPT and Perplexity. For teams new to geo basics, week one should end with a one page map that lists ten prompts, ten canonical URLs, and baseline citation share. That map prevents random edits and makes week two rewrites testable. Map each high value prompt to one canonical URL, consolidating duplicates where needed. Pick ten prompts for the first cycle based on value and readiness. Document baselines so later movement is visible.
Week two rewrites the first five pages. For each, tighten the opening answer, make headings match prompt subquestions, split long prose into self contained paragraphs, and add one missing table or checklist. Restate scope and dates with each fact. Verify facts, links, and version notes. Ensure each URL is sitemapped, internally linked from at least three relevant pages, and fast to fetch. Run prompt tests at the end of the week and log early signals without judging yet. Most movement appears after crawlers revisit.
Week three rewrites the next five pages with the same pattern, applying lessons from week two about which structures moved. Add error catalogs where troubleshooting prompts matter. Improve author, date, and source displays. Review server logs for AI fetches and fix any blocks or timeouts. Check text only rendering for each rewritten URL. Keep changes isolated per page so results stay attributable. Update your backlog notes with what worked and what did not.
Week four measures and plans the next cycle. Rerun the full prompt set twice and compare citation share with baseline using four week ranges. Segment AI referrals by landing page and note quality signals. Choose the next ten prompts based on remaining value and readiness, carrying over any pages that need another pass. Share a short report with methods, ranges, and next actions. Then repeat monthly: refresh dates and facts, prune weak pages, and keep technical monitoring continuous. After two to three cycles, the program compounds as templates and patterns stabilize.
Throughout the plan, keep one canonical per task and resist forks for assistants. If you maintain discovery helpers, keep them in sync, as explained in the complete guide to the AI crawler file. For deeper prompt level tactics, use the focused playbooks for getting cited in ChatGPT answers and getting quoted in Perplexity. Steady small cycles beat occasional large pushes for durable answer presence.
 <!-- IMAGE-PROMPT workflow-02: 1600px max, DependsIt brand, deep charcoal #121212 or clean white background, vibrant mint #22E3B0 accent glow, thin node-network line art, Clash Display style bold headings, General Sans clean labels, subject: 30 day GEO plan from prompt selection to page rewrite to citation tracking, flat vector, accessible, no em dash -->
FAQ
Is GEO replacing SEO?
No. The discussion around geo vs seo is best understood as addition rather than replacement, because crawl access, structure, and quality still decide which pages can be retrieved. GEO shapes those eligible pages so models can quote them inside answers with correct scope and dates. A steady geo seo workflow keeps classic tasks such as sitemaps, internal links, canonicals, and rendering hygiene while adding answer first rewrites and weekly prompt tests for high value tasks. Teams that maintain both channels see stronger results than teams that pause SEO to chase answers. Either channel alone is weaker than both together for durable growth.
How many pages should I optimize first?
Start with ten canonical pages mapped to ten high value prompts that sit close to revenue or support deflection. This focused geo strategy fits in a month and produces readable signals without spreading edits thin. Choose one URL per task, consolidate duplicates with redirects, and ensure each page is eligible, linked, and sitemapped. Apply proven geo tactics such as tightening the opening answer, making paragraphs self contained, adding one comparison table, and restating dates with each fact. Depth on a few canonicals teaches which patterns work in your niche. You can then apply winning shapes to the next batch with less rework and faster review.
Do I need new tools to do GEO?
No. The geo basics can be handled with server logs, analytics segments, and a fixed prompt sheet that records date, prompt, assistant, cited URLs, and notes. Use your existing SEO crawler for technical checks and text only fetch tests for rendering review. This generative engine optimization guide recommends starting manual and consistent, with baselines and four week ranges, before buying specialized trackers. Add visibility tools later only when prompt volume justifies cost. Consistent manual testing with recorded methods beats sporadic tool runs without baselines for learning what moves citations.
How long before GEO changes show in answers?
Expect weeks, not days, because systems must recrawl, reindex passages, and then select them amid competition. Wait at least two crawl cycles and several weekly test rounds, often three to six weeks, and judge citation share over four week windows. If generative engine visibility does not move after six to eight weeks, revisit technical eligibility and page structure before adding more pages. Small gains in ai answer optimization such as clearer openings or added tables often appear first for troubleshooting prompts. Track ranges rather than single runs to avoid noisy conclusions and premature rewrites.
Should I write different content for ChatGPT and Perplexity?
No. Maintain one canonical URL per task that serves humans and all assistants. Both systems benefit when you optimize for ai answers with answer first structure, tables, dates, and scope notes. Separate versions split signals and double maintenance while creating duplicates that hurt all engines. Good generative search seo practice uses the same page for classic search and AI retrieval, with robots permission and sitemaps guiding each system to the single canonical source. Keep templates consistent so every new page starts citable instead of needing rescue rewrites later.
What is the most common GEO mistake?
Publishing more thin pages instead of improving canonical answers is the most frequent error. Thin pages dilute crawl budget, split internal links, and give models no clear passage to cite. A better geo strategy is to consolidate duplicates, complete the task on one URL, state scope with each fact, and keep dates current. These basic geo tactics outperform volume in almost every test. Fewer stronger pages earn more citations than many weak ones, and they are easier to maintain, link, and refresh on a quarterly cycle.
Sources
- https://developers.google.com/search/docs/crawling-indexing/overview
- https://schema.org/HowTo