Content Refreshes: How to Trigger Reindexing After Updates
This guide is for site owners, developers and SEOs who work with reindex after content update and need a clear routine without guesswork. Many teams see the same pattern: coverage reports stall, important pages wait in Discovered or Crawled, and stakeholders ask when results will show. The facts help here. Plan for efficient crawling, clean sitemaps, honest quality signals and steady measurement. You will learn exact checks, safe defaults and a review rhythm that fits a busy week. Follow the sections in order, test on a small sample first, then scale once responses and reports stay clean. The focus keyword reindex after content update appears where it helps mapping, never as filler.
Key takeaways
- reindex after content update rewards steady routines: clean templates, honest sitemaps and hub links for priority pages.
- Map each URL group to an owner, a sitemap chunk and a hub link before any bulk submission.
- Track submitted, crawled and indexed counts in two week windows before judging a fix.
- Fix templates once, prune low value pages and review monthly so gains hold.
- Why reindex after content update takes time
- What signals tell Google a page truly changed
- How to use lastmod correctly after edits
- How to request recrawling without waste
- How internal links and sitemaps support refreshes
- How to prioritize which updates deserve submission
- How to handle large scale content refresh programs
- How to measure whether refreshes were reindexed
- Common mistakes that block reindexing after updates
- How to keep a changelog that helps indexing
- A repeatable refresh to reindex workflow
- FAQ
- Sources
- Further reading
 <!-- IMAGE-PROMPT cover: 1200x630, DependsIt brand, deep charcoal #121212 background with vibrant mint #22E3B0 accent glow, thin node-network line art, Clash Display style bold heading space on left, General Sans clean labels, subject: reindex after content update cover illustration, flat vector, high contrast, accessible, no photorealistic faces, no text smaller than 24px, no em dash in rendered text, export PNG then cwebp -q 82 to WEBP -->
Why reindex after content update takes time
This section covers why updated pages wait for recrawling in the context of reindex after content update. Many teams treat this step as a one time task, but results come from a repeatable routine that fits a normal week. Start by defining the exact URL set, the template that renders it and the signal that proves a change is real.
For content update reindex planning, define what counts as meaningful before you trigger recrawl after edit. This content refresh seo habit avoids wasted pushes on typo fixes and keeps reindex changed pages queues focused on real gains. Then connect discovery, internal links and sitemaps so crawlers can reach the page without detours. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates. The goal is steady progress you can see in coverage, not a single spike that fades after a deploy.
Google does not support IndexNow, so plan for two ecosystems. IndexNow notifies Bing, Yandex, Naver, Seznam and other partners that share the protocol, while Google relies on sitemaps, Search Console inspection and the Indexing API for eligible types. A practical setup sends updates to both paths at publish time. One worker prepares the URL list, then one branch pings IndexNow endpoints and another branch queues Google notifications within quota. Coverage improves without double counting. Always verify the current partner list on the official spec before promising coverage to stakeholders.
Thin or duplicated content slows indexing because search engines prioritize pages likely to satisfy searchers. Short descriptions copied from suppliers, empty category pages and near duplicate articles often sit in Discovered or Crawled without indexing. Add specific details such as dimensions, materials, compatibility, usage steps and original photos. Consolidate near duplicates into one strong page with redirects. Better content earns more frequent revisits and steadier indexing. Treat quality as a crawl budget lever, not only as a ranking lever, and prune pages that cannot carry their weight.
| Item | What to record | Where to check |
| Item | What to record | Where to check |
|---|---|---|
| URL group | Template for why updated pages wait for recrawling | Crawl export by path |
| Fetch | Status plus response time | Logs and crawl stats |
| Signal | Sitemap plus internal inlinks | Sitemap index and crawler |
| Action | Allow, canonical, noindex or fix | Change log with date |
- Define the URL set for why updated pages wait for recrawling and record template plus parameter pattern in one sheet.
- Confirm each URL returns 200, loads fast and links to a canonical that is self referencing.
- Check robots, meta robots and headers so the keepers are fully allowed.
- Update the sitemap chunk and add at least one contextual internal link from a hub.
- Submit the priority slice first, log responses, then schedule a coverage review in seven days.
Robots directives and meta tags can silently block indexing. A stray noindex in a template, an X Robots Tag header from a staging config, or a disallow in robots that covers new paths will keep pages out even after successful submission. Audit headers with a fetch tool, render pages as the crawler sees them, and check the coverage report for Excluded by noindex or Blocked by robots. Fix the template once rather than patching URLs one by one. Log analysis also helps. Group hits by user agent, path template, status code and hour to see waste and priority coverage in one view.
In practice, make a short runbook for why updated pages wait for recrawling and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
What signals tell Google a page truly changed
This section covers what signals tell google a page truly changed in the context of reindex after content update. Many teams treat this step as a one time task, but results come from a repeatable routine that fits a normal week. Start by defining the exact URL set, the template that renders it and the signal that proves a change is real. Then connect discovery, internal links and sitemaps so crawlers can reach the page without detours. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates. The goal is steady progress you can see in coverage, not a single spike that fades after a deploy.
Sitemaps remain the backbone of discovery. A clean sitemap lists only canonical, indexable URLs that return 200 and load quickly.
To refresh content google can trust, keep lastmod honest and list only canonical 200 URLs. An updated page recrawl follows faster when sitemaps, hub links, and recrawl updated urls logs all point to the same changed set. Split large sets into chunks of 10000 to 40000 URLs, compress with gzip, and reference each chunk from a sitemap index. Update the lastmod field only when content truly changes. Submit the index in Search Console and keep it reachable. A tidy sitemap reduces wasted fetches and leaves room for priority pages. Review the index weekly, remove dead URLs fast, and keep chunk names stable so monitoring stays simple across deploys.
Quotas shape every automation decision. Many projects start with a limited daily allowance for URL notifications, plus per minute limits that trigger 429 responses when bursts arrive. Track usage in Cloud Console under APIs and Services, set alerts at 60 percent and 85 percent, and log each publish with timestamp, URL, response code and notification type. When you know burn rate by hour, you can pace jobs, defer low priority URLs and avoid midnight surprises. A 429 means slow down, not try harder. Wait with exponential backoff and jitter, cap retries at four or five, then move the URL to a delayed queue.
| Item | What to record | Where to check |
| Item | What to record | Where to check |
|---|---|---|
| URL group | Template for what signals tell google a page truly changed | Crawl export by path |
| Fetch | Status plus response time | Logs and crawl stats |
| Signal | Sitemap plus internal inlinks | Sitemap index and crawler |
| Action | Allow, canonical, noindex or fix | Change log with date |
- Define the URL set for what signals tell google a page truly changed and record template plus parameter pattern in one sheet.
- Confirm each URL returns 200, loads fast and links to a canonical that is self referencing.
- Check robots, meta robots and headers so the keepers are fully allowed.
- Update the sitemap chunk and add at least one contextual internal link from a hub.
- Submit the priority slice first, log responses, then schedule a coverage review in seven days.
Measurement keeps indexing work honest. Track submitted URLs, crawled URLs and indexed URLs as three separate counts, then review them in two week windows. Coverage in Search Console, crawl stats and server logs tell different parts of the story, so read them together. Look for patterns by template, by sitemap chunk and by internal depth. When a fix works, the effect shows first in crawl frequency, then in indexed count, then in impressions. Record what changed and when, so movement links clearly to specific fixes and dates. Share a one page summary with developers and editors each cycle.
In practice, make a short runbook for what signals tell google a page truly changed and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
For official details, see crawl documentation which defines the current behavior and limits.
How to use lastmod correctly after edits
This section covers how to use lastmod correctly after edits in the context of reindex after content update. Many teams treat this step as a one time task, but results come from a repeatable routine that fits a normal week. Start by defining the exact URL set, the template that renders it and the signal that proves a change is real. Then connect discovery, internal links and sitemaps so crawlers can reach the page without detours. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates. The goal is steady progress you can see in coverage, not a single spike that fades after a deploy.
Internal linking does more for indexing than most teams expect. New URLs that sit four clicks from the home page may wait days for a visit, while URLs linked from a popular category or a recent posts block get visited quickly. Add new pages to relevant hubs, link related items, and keep pagination crawlable with plain anchors. Avoid loading key links only through scripts that require clicks. Simple, stable links help both Google and IndexNow driven crawlers find changes fast. Audit depth monthly with a crawler and fix orphaned groups before they stall in coverage.
Robots directives and meta tags can silently block indexing. A stray noindex in a template, an X Robots Tag header from a staging config, or a disallow in robots that covers new paths will keep pages out even after successful submission. Audit headers with a fetch tool, render pages as the crawler sees them, and check the coverage report for Excluded by noindex or Blocked by robots. Fix the template once rather than patching URLs one by one. Log analysis also helps. Group hits by user agent, path template, status code and hour to see waste and priority coverage in one view.
| Item | What to record | Where to check |
| Item | What to record | Where to check |
|---|---|---|
| URL group | Template for how to use lastmod correctly after edits | Crawl export by path |
| Fetch | Status plus response time | Logs and crawl stats |
| Signal | Sitemap plus internal inlinks | Sitemap index and crawler |
| Action | Allow, canonical, noindex or fix | Change log with date |
- Define the URL set for how to use lastmod correctly after edits and record template plus parameter pattern in one sheet.
- Confirm each URL returns 200, loads fast and links to a canonical that is self referencing.
- Check robots, meta robots and headers so the keepers are fully allowed.
- Update the sitemap chunk and add at least one contextual internal link from a hub.
- Submit the priority slice first, log responses, then schedule a coverage review in seven days.
Google discovers most pages through crawl, not through a single submission. A submission is a hint that asks for a fresh look, but storage and ranking still depend on quality, uniqueness and site trust. That is why steady technical hygiene matters more than any single push. Keep response times low, avoid redirect chains, and return clear status codes. When the crawler can fetch quickly and without loops, each hint carries more weight and uses less of the daily allowance. Teams that fix fetch waste first usually see faster revisits across the whole site, not only for the URLs they pinged.
In practice, make a short runbook for how to use lastmod correctly after edits and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
For background on a related report, see fix Discovered without indexing which explains how fetch data maps to coverage decisions.
How to request recrawling without waste
This section covers how to request recrawling without waste in the context of reindex after content update. Many teams treat this step as a one time task, but results come from a repeatable routine that fits a normal week. Start by defining the exact URL set, the template that renders it and the signal that proves a change is real. Then connect discovery, internal links and sitemaps so crawlers can reach the page without detours. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates. The goal is steady progress you can see in coverage, not a single spike that fades after a deploy.
Thin or duplicated content slows indexing because search engines prioritize pages likely to satisfy searchers. Short descriptions copied from suppliers, empty category pages and near duplicate articles often sit in Discovered or Crawled without indexing. Add specific details such as dimensions, materials, compatibility, usage steps and original photos. Consolidate near duplicates into one strong page with redirects. Better content earns more frequent revisits and steadier indexing. Treat quality as a crawl budget lever, not only as a ranking lever, and prune pages that cannot carry their weight.
Measurement keeps indexing work honest. Track submitted URLs, crawled URLs and indexed URLs as three separate counts, then review them in two week windows. Coverage in Search Console, crawl stats and server logs tell different parts of the story, so read them together. Look for patterns by template, by sitemap chunk and by internal depth. When a fix works, the effect shows first in crawl frequency, then in indexed count, then in impressions. Record what changed and when, so movement links clearly to specific fixes and dates. Share a one page summary with developers and editors each cycle.
| Item | What to record | Where to check |
| Item | What to record | Where to check |
|---|---|---|
| URL group | Template for how to request recrawling without waste | Crawl export by path |
| Fetch | Status plus response time | Logs and crawl stats |
| Signal | Sitemap plus internal inlinks | Sitemap index and crawler |
| Action | Allow, canonical, noindex or fix | Change log with date |
- Define the URL set for how to request recrawling without waste and record template plus parameter pattern in one sheet.
- Confirm each URL returns 200, loads fast and links to a canonical that is self referencing.
- Check robots, meta robots and headers so the keepers are fully allowed.
- Update the sitemap chunk and add at least one contextual internal link from a hub.
- Submit the priority slice first, log responses, then schedule a coverage review in seven days.
Google does not support IndexNow, so plan for two ecosystems. IndexNow notifies Bing, Yandex, Naver, Seznam and other partners that share the protocol, while Google relies on sitemaps, Search Console inspection and the Indexing API for eligible types. A practical setup sends updates to both paths at publish time. One worker prepares the URL list, then one branch pings IndexNow endpoints and another branch queues Google notifications within quota. Coverage improves without double counting. Always verify the current partner list on the official spec before promising coverage to stakeholders.
In practice, make a short runbook for how to request recrawling without waste and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
How internal links and sitemaps support refreshes
This section covers how internal links and sitemaps support refreshes in the context of reindex after content update. Many teams treat this step as a one time task, but results come from a repeatable routine that fits a normal week. Start by defining the exact URL set, the template that renders it and the signal that proves a change is real. Then connect discovery, internal links and sitemaps so crawlers can reach the page without detours. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates. The goal is steady progress you can see in coverage, not a single spike that fades after a deploy.
Quotas shape every automation decision. Many projects start with a limited daily allowance for URL notifications, plus per minute limits that trigger 429 responses when bursts arrive. Track usage in Cloud Console under APIs and Services, set alerts at 60 percent and 85 percent, and log each publish with timestamp, URL, response code and notification type. When you know burn rate by hour, you can pace jobs, defer low priority URLs and avoid midnight surprises. A 429 means slow down, not try harder. Wait with exponential backoff and jitter, cap retries at four or five, then move the URL to a delayed queue.
Google discovers most pages through crawl, not through a single submission. A submission is a hint that asks for a fresh look, but storage and ranking still depend on quality, uniqueness and site trust. That is why steady technical hygiene matters more than any single push. Keep response times low, avoid redirect chains, and return clear status codes. When the crawler can fetch quickly and without loops, each hint carries more weight and uses less of the daily allowance. Teams that fix fetch waste first usually see faster revisits across the whole site, not only for the URLs they pinged.
| Item | What to record | Where to check |
| Item | What to record | Where to check |
|---|---|---|
| URL group | Template for how internal links and sitemaps support refreshes | Crawl export by path |
| Fetch | Status plus response time | Logs and crawl stats |
| Signal | Sitemap plus internal inlinks | Sitemap index and crawler |
| Action | Allow, canonical, noindex or fix | Change log with date |
- Define the URL set for how internal links and sitemaps support refreshes and record template plus parameter pattern in one sheet.
- Confirm each URL returns 200, loads fast and links to a canonical that is self referencing.
- Check robots, meta robots and headers so the keepers are fully allowed.
- Update the sitemap chunk and add at least one contextual internal link from a hub.
- Submit the priority slice first, log responses, then schedule a coverage review in seven days.
Sitemaps remain the backbone of discovery. A clean sitemap lists only canonical, indexable URLs that return 200 and load quickly. Split large sets into chunks of 10000 to 40000 URLs, compress with gzip, and reference each chunk from a sitemap index. Update the lastmod field only when content truly changes. Submit the index in Search Console and keep it reachable. A tidy sitemap reduces wasted fetches and leaves room for priority pages. Review the index weekly, remove dead URLs fast, and keep chunk names stable so monitoring stays simple across deploys.
In practice, make a short runbook for how internal links and sitemaps support refreshes and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
curl -X POST "https://api.indexnow.org/indexnow" -H "Content-Type: application/json" -d @payload.jsonHow to prioritize which updates deserve submission
This section covers how to prioritize which updates deserve submission in the context of reindex after content update. Many teams treat this step as a one time task, but results come from a repeatable routine that fits a normal week. Start by defining the exact URL set, the template that renders it and the signal that proves a change is real. Then connect discovery, internal links and sitemaps so crawlers can reach the page without detours. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates. The goal is steady progress you can see in coverage, not a single spike that fades after a deploy.
Robots directives and meta tags can silently block indexing. A stray noindex in a template, an X Robots Tag header from a staging config, or a disallow in robots that covers new paths will keep pages out even after successful submission. Audit headers with a fetch tool, render pages as the crawler sees them, and check the coverage report for Excluded by noindex or Blocked by robots. Fix the template once rather than patching URLs one by one. Log analysis also helps. Group hits by user agent, path template, status code and hour to see waste and priority coverage in one view.
Google does not support IndexNow, so plan for two ecosystems. IndexNow notifies Bing, Yandex, Naver, Seznam and other partners that share the protocol, while Google relies on sitemaps, Search Console inspection and the Indexing API for eligible types. A practical setup sends updates to both paths at publish time. One worker prepares the URL list, then one branch pings IndexNow endpoints and another branch queues Google notifications within quota. Coverage improves without double counting. Always verify the current partner list on the official spec before promising coverage to stakeholders.
| Item | What to record | Where to check |
| Item | What to record | Where to check |
|---|---|---|
| URL group | Template for how to prioritize which updates deserve submission | Crawl export by path |
| Fetch | Status plus response time | Logs and crawl stats |
| Signal | Sitemap plus internal inlinks | Sitemap index and crawler |
| Action | Allow, canonical, noindex or fix | Change log with date |
- Define the URL set for how to prioritize which updates deserve submission and record template plus parameter pattern in one sheet.
- Confirm each URL returns 200, loads fast and links to a canonical that is self referencing.
- Check robots, meta robots and headers so the keepers are fully allowed.
- Update the sitemap chunk and add at least one contextual internal link from a hub.
- Submit the priority slice first, log responses, then schedule a coverage review in seven days.
Internal linking does more for indexing than most teams expect. New URLs that sit four clicks from the home page may wait days for a visit, while URLs linked from a popular category or a recent posts block get visited quickly. Add new pages to relevant hubs, link related items, and keep pagination crawlable with plain anchors. Avoid loading key links only through scripts that require clicks. Simple, stable links help both Google and IndexNow driven crawlers find changes fast. Audit depth monthly with a crawler and fix orphaned groups before they stall in coverage.
In practice, make a short runbook for how to prioritize which updates deserve submission and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
For background on a related workflow, see how internal linking speeds indexing which covers adjacent checks in one place.
How to handle large scale content refresh programs
This section covers how to handle large scale content refresh programs in the context of reindex after content update. Many teams treat this step as a one time task, but results come from a repeatable routine that fits a normal week. Start by defining the exact URL set, the template that renders it and the signal that proves a change is real. Then connect discovery, internal links and sitemaps so crawlers can reach the page without detours. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates. The goal is steady progress you can see in coverage, not a single spike that fades after a deploy.
Measurement keeps indexing work honest. Track submitted URLs, crawled URLs and indexed URLs as three separate counts, then review them in two week windows. Coverage in Search Console, crawl stats and server logs tell different parts of the story, so read them together. Look for patterns by template, by sitemap chunk and by internal depth. When a fix works, the effect shows first in crawl frequency, then in indexed count, then in impressions. Record what changed and when, so movement links clearly to specific fixes and dates. Share a one page summary with developers and editors each cycle.
Sitemaps remain the backbone of discovery. A clean sitemap lists only canonical, indexable URLs that return 200 and load quickly. Split large sets into chunks of 10000 to 40000 URLs, compress with gzip, and reference each chunk from a sitemap index. Update the lastmod field only when content truly changes. Submit the index in Search Console and keep it reachable. A tidy sitemap reduces wasted fetches and leaves room for priority pages. Review the index weekly, remove dead URLs fast, and keep chunk names stable so monitoring stays simple across deploys.
| Item | What to record | Where to check |
| Item | What to record | Where to check |
|---|---|---|
| URL group | Template for how to handle large scale content refresh programs | Crawl export by path |
| Fetch | Status plus response time | Logs and crawl stats |
| Signal | Sitemap plus internal inlinks | Sitemap index and crawler |
| Action | Allow, canonical, noindex or fix | Change log with date |
- Define the URL set for how to handle large scale content refresh programs and record template plus parameter pattern in one sheet.
- Confirm each URL returns 200, loads fast and links to a canonical that is self referencing.
- Check robots, meta robots and headers so the keepers are fully allowed.
- Update the sitemap chunk and add at least one contextual internal link from a hub.
- Submit the priority slice first, log responses, then schedule a coverage review in seven days.
Thin or duplicated content slows indexing because search engines prioritize pages likely to satisfy searchers. Short descriptions copied from suppliers, empty category pages and near duplicate articles often sit in Discovered or Crawled without indexing. Add specific details such as dimensions, materials, compatibility, usage steps and original photos. Consolidate near duplicates into one strong page with redirects. Better content earns more frequent revisits and steadier indexing. Treat quality as a crawl budget lever, not only as a ranking lever, and prune pages that cannot carry their weight.
In practice, make a short runbook for how to handle large scale content refresh programs and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
 <!-- IMAGE-PROMPT diagram-01: 1600px max, DependsIt brand mint #22E3B0 on charcoal #121212, node-network line art, Clash Display style headings feel with General Sans clean labels, subject: reindex after content update diagram with crawl and queue nodes, flat vector, accessible, no em dash in rendered text -->
 <!-- IMAGE-PROMPT diagram-02: 1600px max, DependsIt brand, subject: verification checklist pipeline with done-state nodes about What signals tell Google a page truly changed | How to request recrawling withou, flat vector, accessible, no em dash -->
How to measure whether refreshes were reindexed
This section covers how to measure whether refreshes were reindexed in the context of reindex after content update. Many teams treat this step as a one time task, but results come from a repeatable routine that fits a normal week. Start by defining the exact URL set, the template that renders it and the signal that proves a change is real. Then connect discovery, internal links and sitemaps so crawlers can reach the page without detours. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates. The goal is steady progress you can see in coverage, not a single spike that fades after a deploy.
Google discovers most pages through crawl, not through a single submission. A submission is a hint that asks for a fresh look, but storage and ranking still depend on quality, uniqueness and site trust. That is why steady technical hygiene matters more than any single push. Keep response times low, avoid redirect chains, and return clear status codes. When the crawler can fetch quickly and without loops, each hint carries more weight and uses less of the daily allowance. Teams that fix fetch waste first usually see faster revisits across the whole site, not only for the URLs they pinged.
Internal linking does more for indexing than most teams expect. New URLs that sit four clicks from the home page may wait days for a visit, while URLs linked from a popular category or a recent posts block get visited quickly. Add new pages to relevant hubs, link related items, and keep pagination crawlable with plain anchors. Avoid loading key links only through scripts that require clicks. Simple, stable links help both Google and IndexNow driven crawlers find changes fast. Audit depth monthly with a crawler and fix orphaned groups before they stall in coverage.
| Item | What to record | Where to check |
| Item | What to record | Where to check |
|---|---|---|
| URL group | Template for how to measure whether refreshes were reindexed | Crawl export by path |
| Fetch | Status plus response time | Logs and crawl stats |
| Signal | Sitemap plus internal inlinks | Sitemap index and crawler |
| Action | Allow, canonical, noindex or fix | Change log with date |
- Define the URL set for how to measure whether refreshes were reindexed and record template plus parameter pattern in one sheet.
- Confirm each URL returns 200, loads fast and links to a canonical that is self referencing.
- Check robots, meta robots and headers so the keepers are fully allowed.
- Update the sitemap chunk and add at least one contextual internal link from a hub.
- Submit the priority slice first, log responses, then schedule a coverage review in seven days.
Quotas shape every automation decision. Many projects start with a limited daily allowance for URL notifications, plus per minute limits that trigger 429 responses when bursts arrive. Track usage in Cloud Console under APIs and Services, set alerts at 60 percent and 85 percent, and log each publish with timestamp, URL, response code and notification type. When you know burn rate by hour, you can pace jobs, defer low priority URLs and avoid midnight surprises. A 429 means slow down, not try harder. Wait with exponential backoff and jitter, cap retries at four or five, then move the URL to a delayed queue.
In practice, make a short runbook for how to measure whether refreshes were reindexed and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
For protocol limits, see Search Console sitemaps report for the current quota and response notes.
Common mistakes that block reindexing after updates
This section covers common mistakes that block reindexing after updates in the context of reindex after content update. Many teams treat this step as a one time task, but results come from a repeatable routine that fits a normal week. Start by defining the exact URL set, the template that renders it and the signal that proves a change is real. Then connect discovery, internal links and sitemaps so crawlers can reach the page without detours. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates. The goal is steady progress you can see in coverage, not a single spike that fades after a deploy.
Google does not support IndexNow, so plan for two ecosystems. IndexNow notifies Bing, Yandex, Naver, Seznam and other partners that share the protocol, while Google relies on sitemaps, Search Console inspection and the Indexing API for eligible types. A practical setup sends updates to both paths at publish time. One worker prepares the URL list, then one branch pings IndexNow endpoints and another branch queues Google notifications within quota. Coverage improves without double counting. Always verify the current partner list on the official spec before promising coverage to stakeholders.
Thin or duplicated content slows indexing because search engines prioritize pages likely to satisfy searchers. Short descriptions copied from suppliers, empty category pages and near duplicate articles often sit in Discovered or Crawled without indexing. Add specific details such as dimensions, materials, compatibility, usage steps and original photos. Consolidate near duplicates into one strong page with redirects. Better content earns more frequent revisits and steadier indexing. Treat quality as a crawl budget lever, not only as a ranking lever, and prune pages that cannot carry their weight.
| Item | What to record | Where to check |
| Item | What to record | Where to check |
|---|---|---|
| URL group | Template for common mistakes that block reindexing after updates | Crawl export by path |
| Fetch | Status plus response time | Logs and crawl stats |
| Signal | Sitemap plus internal inlinks | Sitemap index and crawler |
| Action | Allow, canonical, noindex or fix | Change log with date |
- Define the URL set for common mistakes that block reindexing after updates and record template plus parameter pattern in one sheet.
- Confirm each URL returns 200, loads fast and links to a canonical that is self referencing.
- Check robots, meta robots and headers so the keepers are fully allowed.
- Update the sitemap chunk and add at least one contextual internal link from a hub.
- Submit the priority slice first, log responses, then schedule a coverage review in seven days.
Robots directives and meta tags can silently block indexing. A stray noindex in a template, an X Robots Tag header from a staging config, or a disallow in robots that covers new paths will keep pages out even after successful submission. Audit headers with a fetch tool, render pages as the crawler sees them, and check the coverage report for Excluded by noindex or Blocked by robots. Fix the template once rather than patching URLs one by one. Log analysis also helps. Group hits by user agent, path template, status code and hour to see waste and priority coverage in one view.
In practice, make a short runbook for common mistakes that block reindexing after updates and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
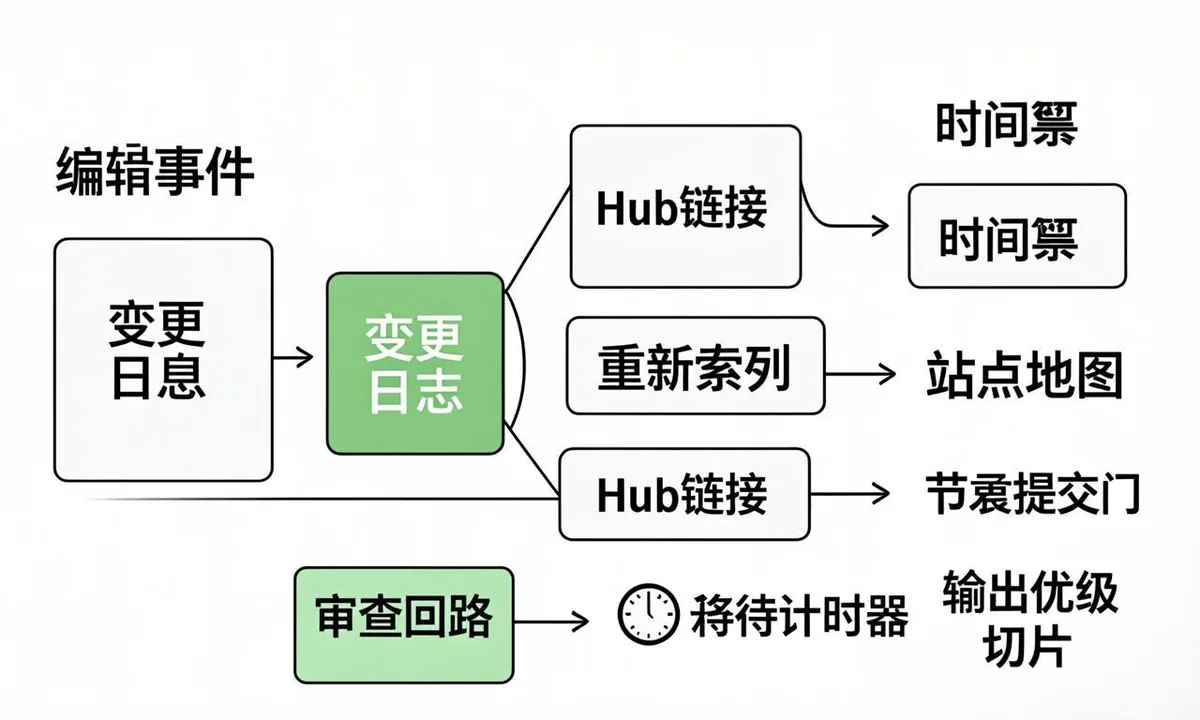 <!-- IMAGE-PROMPT workflow-02: 1600px max, DependsIt brand mint #22E3B0 on charcoal #121212, node-network line art, Clash Display style headings feel with General Sans clean labels, subject: reindex after content update workflow from publish to coverage, flat vector, accessible, no em dash in rendered text -->
How to keep a changelog that helps indexing
This section covers how to keep a changelog that helps indexing in the context of reindex after content update. Many teams treat this step as a one time task, but results come from a repeatable routine that fits a normal week. Start by defining the exact URL set, the template that renders it and the signal that proves a change is real. Then connect discovery, internal links and sitemaps so crawlers can reach the page without detours. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates. The goal is steady progress you can see in coverage, not a single spike that fades after a deploy.
Sitemaps remain the backbone of discovery. A clean sitemap lists only canonical, indexable URLs that return 200 and load quickly. Split large sets into chunks of 10000 to 40000 URLs, compress with gzip, and reference each chunk from a sitemap index. Update the lastmod field only when content truly changes. Submit the index in Search Console and keep it reachable. A tidy sitemap reduces wasted fetches and leaves room for priority pages. Review the index weekly, remove dead URLs fast, and keep chunk names stable so monitoring stays simple across deploys.
Quotas shape every automation decision. Many projects start with a limited daily allowance for URL notifications, plus per minute limits that trigger 429 responses when bursts arrive. Track usage in Cloud Console under APIs and Services, set alerts at 60 percent and 85 percent, and log each publish with timestamp, URL, response code and notification type. When you know burn rate by hour, you can pace jobs, defer low priority URLs and avoid midnight surprises. A 429 means slow down, not try harder. Wait with exponential backoff and jitter, cap retries at four or five, then move the URL to a delayed queue.
| Item | What to record | Where to check |
| Item | What to record | Where to check |
|---|---|---|
| URL group | Template for how to keep a changelog that helps indexing | Crawl export by path |
| Fetch | Status plus response time | Logs and crawl stats |
| Signal | Sitemap plus internal inlinks | Sitemap index and crawler |
| Action | Allow, canonical, noindex or fix | Change log with date |
- Define the URL set for how to keep a changelog that helps indexing and record template plus parameter pattern in one sheet.
- Confirm each URL returns 200, loads fast and links to a canonical that is self referencing.
- Check robots, meta robots and headers so the keepers are fully allowed.
- Update the sitemap chunk and add at least one contextual internal link from a hub.
- Submit the priority slice first, log responses, then schedule a coverage review in seven days.
Measurement keeps indexing work honest. Track submitted URLs, crawled URLs and indexed URLs as three separate counts, then review them in two week windows. Coverage in Search Console, crawl stats and server logs tell different parts of the story, so read them together. Look for patterns by template, by sitemap chunk and by internal depth. When a fix works, the effect shows first in crawl frequency, then in indexed count, then in impressions. Record what changed and when, so movement links clearly to specific fixes and dates. Share a one page summary with developers and editors each cycle.
In practice, make a short runbook for how to keep a changelog that helps indexing and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
A repeatable refresh to reindex workflow
This section covers a repeatable refresh to reindex workflow in the context of reindex after content update. Many teams treat this step as a one time task, but results come from a repeatable routine that fits a normal week. Start by defining the exact URL set, the template that renders it and the signal that proves a change is real. Then connect discovery, internal links and sitemaps so crawlers can reach the page without detours. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates. The goal is steady progress you can see in coverage, not a single spike that fades after a deploy.
Internal linking does more for indexing than most teams expect. New URLs that sit four clicks from the home page may wait days for a visit, while URLs linked from a popular category or a recent posts block get visited quickly. Add new pages to relevant hubs, link related items, and keep pagination crawlable with plain anchors. Avoid loading key links only through scripts that require clicks. Simple, stable links help both Google and IndexNow driven crawlers find changes fast. Audit depth monthly with a crawler and fix orphaned groups before they stall in coverage.
Robots directives and meta tags can silently block indexing. A stray noindex in a template, an X Robots Tag header from a staging config, or a disallow in robots that covers new paths will keep pages out even after successful submission. Audit headers with a fetch tool, render pages as the crawler sees them, and check the coverage report for Excluded by noindex or Blocked by robots. Fix the template once rather than patching URLs one by one. Log analysis also helps. Group hits by user agent, path template, status code and hour to see waste and priority coverage in one view.
| Item | What to record | Where to check |
| Item | What to record | Where to check |
|---|---|---|
| URL group | Template for a repeatable refresh to reindex workflow | Crawl export by path |
| Fetch | Status plus response time | Logs and crawl stats |
| Signal | Sitemap plus internal inlinks | Sitemap index and crawler |
| Action | Allow, canonical, noindex or fix | Change log with date |
- Define the URL set for a repeatable refresh to reindex workflow and record template plus parameter pattern in one sheet.
- Confirm each URL returns 200, loads fast and links to a canonical that is self referencing.
- Check robots, meta robots and headers so the keepers are fully allowed.
- Update the sitemap chunk and add at least one contextual internal link from a hub.
- Submit the priority slice first, log responses, then schedule a coverage review in seven days.
Google discovers most pages through crawl, not through a single submission. A submission is a hint that asks for a fresh look, but storage and ranking still depend on quality, uniqueness and site trust. That is why steady technical hygiene matters more than any single push. Keep response times low, avoid redirect chains, and return clear status codes. When the crawler can fetch quickly and without loops, each hint carries more weight and uses less of the daily allowance. Teams that fix fetch waste first usually see faster revisits across the whole site, not only for the URLs they pinged.
In practice, make a short runbook for a repeatable refresh to reindex workflow and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
FAQ
How long does content update reindex take after an update?
It varies from hours to weeks based on crawl frequency, site trust and update size. This content update reindex window shortens with strong links and clean sitemaps. Popular pages with strong links often refresh in days. Deep pages may need sitemap updates, internal links and a manual inspection to move faster.
Does changing lastmod trigger recrawl after edit?
Lastmod helps when it is honest. To trigger recrawl after edit reliably, update lastmod only on real changes and keep the sitemap fresh. Update it only when visible content truly changes, keep sitemaps fresh and avoid rewriting unchanged timestamps. False lastmod trains crawlers to ignore the signal.
Should I request content refresh seo submission for every edit?
No. Reserve manual requests and API style pushes for meaningful updates on priority pages. This content refresh seo rule saves quota for reindex changed pages that matter. Small typo fixes do not need a push. Batch minor edits into the normal crawl cycle to save quota.
Why did my updated page not change in results?
Either the recrawl has not happened yet, the change was too small to shift signals, or a cache and template issue serves stale HTML. Check fetch and render, confirm headers and compare cached text with live text.
Do internal links help updated page recrawl for refreshed content?
Yes. A fresh link from a hub or recent list often brings a faster revisit than a lone submission. This updated page recrawl lift plus recrawl updated urls tracking proves which hubs work fastest. Add contextual links when you refresh a group so crawlers find the new version during normal passes.
How do I track refreshes across many pages?
Keep a simple log with URL, edit date, change summary, sitemap chunk and submission status. Review coverage in two week windows by group. This log proves what moved and what still needs attention.
Sources
- https://www.indexnow.org/documentation
- https://developers.google.com/search/docs/crawling/overview
- https://support.google.com/webmasters/answer/7451001