XML Sitemap Best Practices for Faster Indexing

A tidy XML sitemap helps search engines find the right pages sooner, while a bloated file teaches them to check less often. This guide is for site owners, SEOs, and developers who need xml sitemap best practices that translate into faster indexing without guesswork. You will learn which URLs belong in the file, how to structure index files for scale, how to handle freshness and media selectively, and how to validate and maintain quality over time. The focus keyword xml sitemap best practices anchors each section so you can audit your current file and rebuild it into a reliable discovery feed.
Key takeaways
- XML sitemap best practices start with listing only live canonical 200 pages that allow indexing and add value.
- Split into small fast children under one stable index, compress, cache, and reference from robots.
- Set lastmod from real CMS edit times and keep canonical, robots, and status aligned on every URL.
- Validate before submission, review warnings monthly, and audit fully each quarter to hold gains.
- What makes an XML sitemap trustworthy
- Choosing which URLs belong in the file
- Structuring sitemap index files for clarity
- Keeping files small fast and fetchable
- Writing accurate lastmod dates from real edits
- Handling images videos and news the selective way
- Canonical robots and status alignment
- Multilingual and multi store sitemap rules
- Common sitemap mistakes that slow indexing
- Validating and testing before submission
- Maintaining xml sitemap best practices over time
- FAQ
- Sources
- Further reading
 <!-- IMAGE-PROMPT cover: 1200x630, DependsIt brand, deep charcoal #121212 background, vibrant mint #22E3B0 accent glow, thin node-network line art, Clash Display style bold heading space on left, General Sans clean labels, subject: xml sitemap best practices explanatory cover for site owners, flat vector, high contrast, accessible, no photorealistic faces, no text smaller than 24px, no em dash in rendered text, export PNG then cwebp -q 82 to WEBP -->
What makes an XML sitemap trustworthy
Trustworthy sitemaps list only live canonical pages, fetch quickly, validate as XML, and carry honest metadata. This section defines the quality bar behind xml sitemap best practices so every later rule traces to trust and fetch frequency. Follow core sitemap guidelines for membership and sitemap optimization for fetch speed, since clean files with strict sitemap url rules earn steadier crawls than bloated inventories. In practical terms, this relates directly to xml sitemap best practices. Site owners often treat each URL in isolation, but Google evaluates patterns across templates, link graphs, and quality thresholds. Understanding the pattern saves time because one template fix can move hundreds of URLs at once.
Consider how xml sitemap best practices appears in the Pages indexing report. Google groups sample URLs under one status, yet the underlying causes vary by section, CMS, and history. Some sites accumulate the status after migrations where redirects and canonicals were incomplete. Others accumulate it gradually as thin archives, tag pages, or faceted filters grow unchecked. Large catalogs add parameter combinations that multiply crawlable paths faster than editorial value grows. Blogs add date archives, author archives, and paginated series that look similar to crawlers. In each case the fix starts with grouping, not with editing a single page. Export up to 1,000 examples, add columns for template, word count, internal inlinks, canonical target, status code, and sitemap presence. That sheet reveals whether xml sitemap best practices clusters on one template or spreads across the site. Template clusters point to code or settings. Spread points to broader quality or linking weakness.
For what makes an xml sitemap trustworthy, start with three checks that catch most issues. First, verify technical eligibility. Confirm the URL returns 200, allows crawling in robots.txt, has no noindex in meta or headers, and declares a clean canonical. Use view source, dev tools network headers, and a header fetch. Second, verify discovery signals. Check which sitemaps list the URL, how many internal links point to it, and whether those links use descriptive anchors from relevant hubs. Pages with zero referring internal links rely solely on sitemaps, which weakens demand. Third, verify value signals. Compare title, headings, intro, and main content against indexed competitors. Look for boilerplate repetition, missing specifics, and unclear intent. If a page could be mistaken for another page on your own site, Google may hesitate. Document each check with dates and examples so later monitoring ties changes to outcomes.
Key checks for this stage:
- Audit templates first because xml sitemap best practices rarely affects random singletons. One header, plugin, or filter rule often explains hundreds of rows.
- Compare rendered HTML to raw HTML. JavaScript delayed content can make a page look thin to crawlers even when browsers show full text.
- Review canonical chains. A canonical that points to a redirect, a 404, or a noindexed page confuses consolidation and delays indexing.
- Clean sitemap signals. List only canonical 200 URLs with accurate lastmod. Remove variants, redirects, and excluded pages that dilute attention.
- Strengthen internal context. Add specific links from indexed hubs with natural anchors. Avoid sitewide boilerplate links that carry little topical weight.
Next, apply fixes in priority order. Address eligibility blockers first because no content improvement can overcome a noindex or crawl block. Then fix canonical and duplicate clarity so Google knows which URL should accumulate signals. Then improve content differentiation with specifics such as steps, examples, data points,FAQs, and original observations that separate the page from near duplicates. Then improve internal linking so the page sits fewer clicks from the homepage and receives topical context. Finally, improve freshness and maintenance by updating dates only when content truly changes, fixing broken outbound links, compressing images, and stabilizing server response times. Each layer builds on the previous one. Skipping eligibility and jumping to content expansion wastes effort when a header still carries noindex.
Measurement closes the loop for xml sitemap best practices. Record baseline counts for Valid, Excluded, Discovered, and Crawled statuses. After changes, inspect live samples to confirm eligibility, check Google selected canonical where relevant, and confirm referring sitemap correctness. Request recrawls for a handful of priority URLs rather than every affected URL. Watch crawl stats for increased fetching without server errors. Expect gradual movement across one to two crawl cycles. If counts stall, revisit grouping. Perhaps a second template contributes, or quality thresholds remain unmet. Keep a simple log with change date, template, action, sample URLs, and before and after counts. That log turns xml sitemap best practices from a confusing label into a manageable workflow with clear ownership and repeatable steps.
Use this quick reference while working on what makes an xml sitemap trustworthy.
| Check | What to confirm | Tool |
|---|---|---|
| Status code and robots | 200 response, allowed by robots, no noindex in meta or headers | View source, headers, URL Inspection live test |
| Canonical intent | Single absolute canonical to preferred 200 URL, matching sitemap | Crawl export, inspection |
| Discovery path | Sitemap inclusion plus at least one contextual internal link | Sitemap index, crawl inlinks |
| Uniqueness | Specific details that differ from site siblings and search competitors | Manual comparison, similarity check |
| Stability | Fast responses, no 5xx spikes, consistent rendering | Crawl stats, server logs |
To finish this stage, pick one cluster related to xml sitemap best practices, apply the checks above, and document the result before expanding to the next cluster. Small batches reduce risk and make cause and effect visible. Share the sheet with developers when code changes are needed, with editors when content rewrites are needed, and with site owners when pruning decisions are needed. Clear ownership keeps what makes an xml sitemap trustworthy from drifting back after temporary gains.
Choosing which URLs belong in the file
Include indexable 200 pages with useful content and self referencing canonicals. Exclude drafts, noindex, redirects, variants, search results, staging, and thin placeholders. This section turns xml sitemap best practices into clear inclusion and exclusion lists. In practical terms, this relates directly to xml sitemap best practices. Site owners often treat each URL in isolation, but Google evaluates patterns across templates, link graphs, and quality thresholds. Understanding the pattern saves time because one template fix can move hundreds of URLs at once.
Consider how xml sitemap best practices appears in the Pages indexing report. Google groups sample URLs under one status, yet the underlying causes vary by section, CMS, and history. Some sites accumulate the status after migrations where redirects and canonicals were incomplete. Others accumulate it gradually as thin archives, tag pages, or faceted filters grow unchecked. Large catalogs add parameter combinations that multiply crawlable paths faster than editorial value grows. Blogs add date archives, author archives, and paginated series that look similar to crawlers. In each case the fix starts with grouping, not with editing a single page. Export up to 1,000 examples, add columns for template, word count, internal inlinks, canonical target, status code, and sitemap presence. That sheet reveals whether xml sitemap best practices clusters on one template or spreads across the site. Template clusters point to code or settings. Spread points to broader quality or linking weakness.
For choosing which urls belong in the file, start with three checks that catch most issues. First, verify technical eligibility. Confirm the URL returns 200, allows crawling in robots.txt, has no noindex in meta or headers, and declares a clean canonical. Use view source, dev tools network headers, and a header fetch. Second, verify discovery signals. Check which sitemaps list the URL, how many internal links point to it, and whether those links use descriptive anchors from relevant hubs. Pages with zero referring internal links rely solely on sitemaps, which weakens demand. Third, verify value signals. Compare title, headings, intro, and main content against indexed competitors. Look for boilerplate repetition, missing specifics, and unclear intent. If a page could be mistaken for another page on your own site, Google may hesitate. Document each check with dates and examples so later monitoring ties changes to outcomes.
Key checks for this stage:
- Audit templates first because xml sitemap best practices rarely affects random singletons. One header, plugin, or filter rule often explains hundreds of rows.
- Compare rendered HTML to raw HTML. JavaScript delayed content can make a page look thin to crawlers even when browsers show full text.
- Review canonical chains. A canonical that points to a redirect, a 404, or a noindexed page confuses consolidation and delays indexing.
- Clean sitemap signals. List only canonical 200 URLs with accurate lastmod. Remove variants, redirects, and excluded pages that dilute attention.
- Strengthen internal context. Add specific links from indexed hubs with natural anchors. Avoid sitewide boilerplate links that carry little topical weight.
Next, apply fixes in priority order. Address eligibility blockers first because no content improvement can overcome a noindex or crawl block. Then fix canonical and duplicate clarity so Google knows which URL should accumulate signals. Then improve content differentiation with specifics such as steps, examples, data points,FAQs, and original observations that separate the page from near duplicates. Then improve internal linking so the page sits fewer clicks from the homepage and receives topical context. Finally, improve freshness and maintenance by updating dates only when content truly changes, fixing broken outbound links, compressing images, and stabilizing server response times. Each layer builds on the previous one. Skipping eligibility and jumping to content expansion wastes effort when a header still carries noindex.
Measurement closes the loop for xml sitemap best practices. Record baseline counts for Valid, Excluded, Discovered, and Crawled statuses. After changes, inspect live samples to confirm eligibility, check Google selected canonical where relevant, and confirm referring sitemap correctness. Request recrawls for a handful of priority URLs rather than every affected URL. Watch crawl stats for increased fetching without server errors. Expect gradual movement across one to two crawl cycles. If counts stall, revisit grouping. Perhaps a second template contributes, or quality thresholds remain unmet. Keep a simple log with change date, template, action, sample URLs, and before and after counts. That log turns xml sitemap best practices from a confusing label into a manageable workflow with clear ownership and repeatable steps.
Use this quick reference while working on choosing which urls belong in the file.
| Check | What to confirm | Tool |
|---|---|---|
| Status code and robots | 200 response, allowed by robots, no noindex in meta or headers | View source, headers, URL Inspection live test |
| Canonical intent | Single absolute canonical to preferred 200 URL, matching sitemap | Crawl export, inspection |
| Discovery path | Sitemap inclusion plus at least one contextual internal link | Sitemap index, crawl inlinks |
| Uniqueness | Specific details that differ from site siblings and search competitors | Manual comparison, similarity check |
| Stability | Fast responses, no 5xx spikes, consistent rendering | Crawl stats, server logs |
To finish this stage, pick one cluster related to xml sitemap best practices, apply the checks above, and document the result before expanding to the next cluster. Small batches reduce risk and make cause and effect visible. Share the sheet with developers when code changes are needed, with editors when content rewrites are needed, and with site owners when pruning decisions are needed. Clear ownership keeps choosing which urls belong in the file from drifting back after temporary gains.
 <!-- IMAGE-PROMPT diagram-01: 1600px max, DependsIt brand mint #22E3B0 on charcoal #121212, node-network line art, Clash Display style headings, General Sans clean labels, subject: xml sitemap best practices pipeline diagram from discovery through crawl to indexing decision, flat vector, accessible, no em dash in rendered text -->
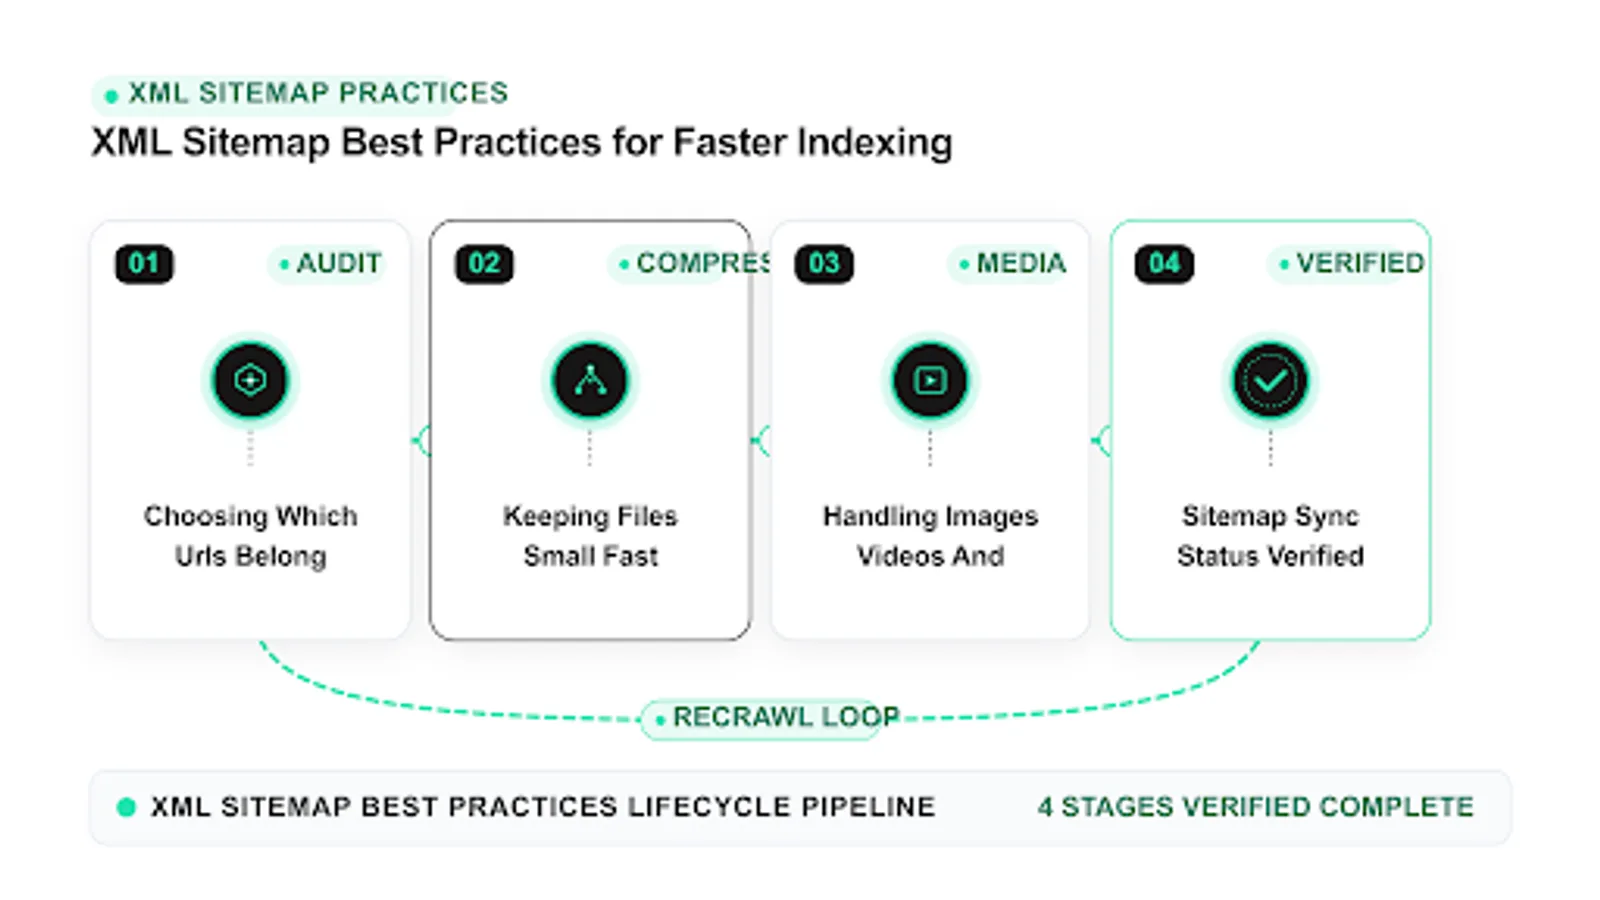 <!-- IMAGE-PROMPT diagram-02: 1600px max, DependsIt brand, subject: lifecycle loop with 4 stages and return arrow about Choosing which URLs belong in the file | Keeping files small fast and fetchable | Handli, flat vector, accessible, no em dash -->
Structuring sitemap index files for clarity
One index that references stable children by section or type keeps errors isolated and ownership clear. This section names children consistently, avoids date stamped churn, and links the index from robots for reliable discovery. A sitemap structure best layout uses small stable children under one index, which is the closest thing to a perfect xml sitemap for large sites and supports long term sitemap freshness. In practical terms, this relates directly to xml sitemap best practices. Site owners often treat each URL in isolation, but Google evaluates patterns across templates, link graphs, and quality thresholds. Understanding the pattern saves time because one template fix can move hundreds of URLs at once.
Consider how xml sitemap best practices appears in the Pages indexing report. Google groups sample URLs under one status, yet the underlying causes vary by section, CMS, and history. Some sites accumulate the status after migrations where redirects and canonicals were incomplete. Others accumulate it gradually as thin archives, tag pages, or faceted filters grow unchecked. Large catalogs add parameter combinations that multiply crawlable paths faster than editorial value grows. Blogs add date archives, author archives, and paginated series that look similar to crawlers. In each case the fix starts with grouping, not with editing a single page. Export up to 1,000 examples, add columns for template, word count, internal inlinks, canonical target, status code, and sitemap presence. That sheet reveals whether xml sitemap best practices clusters on one template or spreads across the site. Template clusters point to code or settings. Spread points to broader quality or linking weakness.
For structuring sitemap index files for clarity, start with three checks that catch most issues. First, verify technical eligibility. Confirm the URL returns 200, allows crawling in robots.txt, has no noindex in meta or headers, and declares a clean canonical. Use view source, dev tools network headers, and a header fetch. Second, verify discovery signals. Check which sitemaps list the URL, how many internal links point to it, and whether those links use descriptive anchors from relevant hubs. Pages with zero referring internal links rely solely on sitemaps, which weakens demand. Third, verify value signals. Compare title, headings, intro, and main content against indexed competitors. Look for boilerplate repetition, missing specifics, and unclear intent. If a page could be mistaken for another page on your own site, Google may hesitate. Document each check with dates and examples so later monitoring ties changes to outcomes.
Key checks for this stage:
- Audit templates first because xml sitemap best practices rarely affects random singletons. One header, plugin, or filter rule often explains hundreds of rows.
- Compare rendered HTML to raw HTML. JavaScript delayed content can make a page look thin to crawlers even when browsers show full text.
- Review canonical chains. A canonical that points to a redirect, a 404, or a noindexed page confuses consolidation and delays indexing.
- Clean sitemap signals. List only canonical 200 URLs with accurate lastmod. Remove variants, redirects, and excluded pages that dilute attention.
- Strengthen internal context. Add specific links from indexed hubs with natural anchors. Avoid sitewide boilerplate links that carry little topical weight.
Next, apply fixes in priority order. Address eligibility blockers first because no content improvement can overcome a noindex or crawl block. Then fix canonical and duplicate clarity so Google knows which URL should accumulate signals. Then improve content differentiation with specifics such as steps, examples, data points,FAQs, and original observations that separate the page from near duplicates. Then improve internal linking so the page sits fewer clicks from the homepage and receives topical context. Finally, improve freshness and maintenance by updating dates only when content truly changes, fixing broken outbound links, compressing images, and stabilizing server response times. Each layer builds on the previous one. Skipping eligibility and jumping to content expansion wastes effort when a header still carries noindex.
Measurement closes the loop for xml sitemap best practices. Record baseline counts for Valid, Excluded, Discovered, and Crawled statuses. After changes, inspect live samples to confirm eligibility, check Google selected canonical where relevant, and confirm referring sitemap correctness. Request recrawls for a handful of priority URLs rather than every affected URL. Watch crawl stats for increased fetching without server errors. Expect gradual movement across one to two crawl cycles. If counts stall, revisit grouping. Perhaps a second template contributes, or quality thresholds remain unmet. Keep a simple log with change date, template, action, sample URLs, and before and after counts. That log turns xml sitemap best practices from a confusing label into a manageable workflow with clear ownership and repeatable steps.
Use this quick reference while working on structuring sitemap index files for clarity.
| Check | What to confirm | Tool |
|---|---|---|
| Status code and robots | 200 response, allowed by robots, no noindex in meta or headers | View source, headers, URL Inspection live test |
| Canonical intent | Single absolute canonical to preferred 200 URL, matching sitemap | Crawl export, inspection |
| Discovery path | Sitemap inclusion plus at least one contextual internal link | Sitemap index, crawl inlinks |
| Uniqueness | Specific details that differ from site siblings and search competitors | Manual comparison, similarity check |
| Stability | Fast responses, no 5xx spikes, consistent rendering | Crawl stats, server logs |
To finish this stage, pick one cluster related to xml sitemap best practices, apply the checks above, and document the result before expanding to the next cluster. Small batches reduce risk and make cause and effect visible. Share the sheet with developers when code changes are needed, with editors when content rewrites are needed, and with site owners when pruning decisions are needed. Clear ownership keeps structuring sitemap index files for clarity from drifting back after temporary gains.
For a related status that often appears alongside this one, see how lastmod really affects crawling and indexing.
Keeping files small fast and fetchable
Small compressed files served quickly get fetched more often than giant slow dumps. This section applies size caps, gzip, edge caching, and stable URLs that make xml sitemap best practices work in production. In practical terms, this relates directly to xml sitemap best practices. Site owners often treat each URL in isolation, but Google evaluates patterns across templates, link graphs, and quality thresholds. Understanding the pattern saves time because one template fix can move hundreds of URLs at once.
Consider how xml sitemap best practices appears in the Pages indexing report. Google groups sample URLs under one status, yet the underlying causes vary by section, CMS, and history. Some sites accumulate the status after migrations where redirects and canonicals were incomplete. Others accumulate it gradually as thin archives, tag pages, or faceted filters grow unchecked. Large catalogs add parameter combinations that multiply crawlable paths faster than editorial value grows. Blogs add date archives, author archives, and paginated series that look similar to crawlers. In each case the fix starts with grouping, not with editing a single page. Export up to 1,000 examples, add columns for template, word count, internal inlinks, canonical target, status code, and sitemap presence. That sheet reveals whether xml sitemap best practices clusters on one template or spreads across the site. Template clusters point to code or settings. Spread points to broader quality or linking weakness.
For keeping files small fast and fetchable, start with three checks that catch most issues. First, verify technical eligibility. Confirm the URL returns 200, allows crawling in robots.txt, has no noindex in meta or headers, and declares a clean canonical. Use view source, dev tools network headers, and a header fetch. Second, verify discovery signals. Check which sitemaps list the URL, how many internal links point to it, and whether those links use descriptive anchors from relevant hubs. Pages with zero referring internal links rely solely on sitemaps, which weakens demand. Third, verify value signals. Compare title, headings, intro, and main content against indexed competitors. Look for boilerplate repetition, missing specifics, and unclear intent. If a page could be mistaken for another page on your own site, Google may hesitate. Document each check with dates and examples so later monitoring ties changes to outcomes.
Key checks for this stage:
- Audit templates first because xml sitemap best practices rarely affects random singletons. One header, plugin, or filter rule often explains hundreds of rows.
- Compare rendered HTML to raw HTML. JavaScript delayed content can make a page look thin to crawlers even when browsers show full text.
- Review canonical chains. A canonical that points to a redirect, a 404, or a noindexed page confuses consolidation and delays indexing.
- Clean sitemap signals. List only canonical 200 URLs with accurate lastmod. Remove variants, redirects, and excluded pages that dilute attention.
- Strengthen internal context. Add specific links from indexed hubs with natural anchors. Avoid sitewide boilerplate links that carry little topical weight.
Next, apply fixes in priority order. Address eligibility blockers first because no content improvement can overcome a noindex or crawl block. Then fix canonical and duplicate clarity so Google knows which URL should accumulate signals. Then improve content differentiation with specifics such as steps, examples, data points,FAQs, and original observations that separate the page from near duplicates. Then improve internal linking so the page sits fewer clicks from the homepage and receives topical context. Finally, improve freshness and maintenance by updating dates only when content truly changes, fixing broken outbound links, compressing images, and stabilizing server response times. Each layer builds on the previous one. Skipping eligibility and jumping to content expansion wastes effort when a header still carries noindex.
Measurement closes the loop for xml sitemap best practices. Record baseline counts for Valid, Excluded, Discovered, and Crawled statuses. After changes, inspect live samples to confirm eligibility, check Google selected canonical where relevant, and confirm referring sitemap correctness. Request recrawls for a handful of priority URLs rather than every affected URL. Watch crawl stats for increased fetching without server errors. Expect gradual movement across one to two crawl cycles. If counts stall, revisit grouping. Perhaps a second template contributes, or quality thresholds remain unmet. Keep a simple log with change date, template, action, sample URLs, and before and after counts. That log turns xml sitemap best practices from a confusing label into a manageable workflow with clear ownership and repeatable steps.
Use this quick reference while working on keeping files small fast and fetchable.
| Check | What to confirm | Tool |
|---|---|---|
| Status code and robots | 200 response, allowed by robots, no noindex in meta or headers | View source, headers, URL Inspection live test |
| Canonical intent | Single absolute canonical to preferred 200 URL, matching sitemap | Crawl export, inspection |
| Discovery path | Sitemap inclusion plus at least one contextual internal link | Sitemap index, crawl inlinks |
| Uniqueness | Specific details that differ from site siblings and search competitors | Manual comparison, similarity check |
| Stability | Fast responses, no 5xx spikes, consistent rendering | Crawl stats, server logs |
To finish this stage, pick one cluster related to xml sitemap best practices, apply the checks above, and document the result before expanding to the next cluster. Small batches reduce risk and make cause and effect visible. Share the sheet with developers when code changes are needed, with editors when content rewrites are needed, and with site owners when pruning decisions are needed. Clear ownership keeps keeping files small fast and fetchable from drifting back after temporary gains.
Check headers and HTML quickly with these commands. Replace the example URL with one of your affected pages.
curl -sI "https://www.example.com/sample-page" | grep -i -E "HTTP|robots|x-robots"
curl -s "https://www.example.com/sample-page" | grep -i -o "<meta[^>]*robots[^>]*>"
import requests
url = "https://www.example.com/sample-page"
r = requests.get(url, timeout=20)
print(r.status_code)
print(r.headers.get("X-Robots-Tag", "no header"))
print("noindex in html:", "noindex" in r.text.lower())Writing accurate lastmod dates from real edits
Lastmod should reflect true content modification from the CMS, not build times. This section wires edit timestamps through the generator and stops daily blanket rewrites that teach engines to ignore freshness. In practical terms, this relates directly to xml sitemap best practices. Site owners often treat each URL in isolation, but Google evaluates patterns across templates, link graphs, and quality thresholds. Understanding the pattern saves time because one template fix can move hundreds of URLs at once.
Consider how xml sitemap best practices appears in the Pages indexing report. Google groups sample URLs under one status, yet the underlying causes vary by section, CMS, and history. Some sites accumulate the status after migrations where redirects and canonicals were incomplete. Others accumulate it gradually as thin archives, tag pages, or faceted filters grow unchecked. Large catalogs add parameter combinations that multiply crawlable paths faster than editorial value grows. Blogs add date archives, author archives, and paginated series that look similar to crawlers. In each case the fix starts with grouping, not with editing a single page. Export up to 1,000 examples, add columns for template, word count, internal inlinks, canonical target, status code, and sitemap presence. That sheet reveals whether xml sitemap best practices clusters on one template or spreads across the site. Template clusters point to code or settings. Spread points to broader quality or linking weakness.
For writing accurate lastmod dates from real edits, start with three checks that catch most issues. First, verify technical eligibility. Confirm the URL returns 200, allows crawling in robots.txt, has no noindex in meta or headers, and declares a clean canonical. Use view source, dev tools network headers, and a header fetch. Second, verify discovery signals. Check which sitemaps list the URL, how many internal links point to it, and whether those links use descriptive anchors from relevant hubs. Pages with zero referring internal links rely solely on sitemaps, which weakens demand. Third, verify value signals. Compare title, headings, intro, and main content against indexed competitors. Look for boilerplate repetition, missing specifics, and unclear intent. If a page could be mistaken for another page on your own site, Google may hesitate. Document each check with dates and examples so later monitoring ties changes to outcomes.
Key checks for this stage:
- Audit templates first because xml sitemap best practices rarely affects random singletons. One header, plugin, or filter rule often explains hundreds of rows.
- Compare rendered HTML to raw HTML. JavaScript delayed content can make a page look thin to crawlers even when browsers show full text.
- Review canonical chains. A canonical that points to a redirect, a 404, or a noindexed page confuses consolidation and delays indexing.
- Clean sitemap signals. List only canonical 200 URLs with accurate lastmod. Remove variants, redirects, and excluded pages that dilute attention.
- Strengthen internal context. Add specific links from indexed hubs with natural anchors. Avoid sitewide boilerplate links that carry little topical weight.
Next, apply fixes in priority order. Address eligibility blockers first because no content improvement can overcome a noindex or crawl block. Then fix canonical and duplicate clarity so Google knows which URL should accumulate signals. Then improve content differentiation with specifics such as steps, examples, data points,FAQs, and original observations that separate the page from near duplicates. Then improve internal linking so the page sits fewer clicks from the homepage and receives topical context. Finally, improve freshness and maintenance by updating dates only when content truly changes, fixing broken outbound links, compressing images, and stabilizing server response times. Each layer builds on the previous one. Skipping eligibility and jumping to content expansion wastes effort when a header still carries noindex.
Measurement closes the loop for xml sitemap best practices. Record baseline counts for Valid, Excluded, Discovered, and Crawled statuses. After changes, inspect live samples to confirm eligibility, check Google selected canonical where relevant, and confirm referring sitemap correctness. Request recrawls for a handful of priority URLs rather than every affected URL. Watch crawl stats for increased fetching without server errors. Expect gradual movement across one to two crawl cycles. If counts stall, revisit grouping. Perhaps a second template contributes, or quality thresholds remain unmet. Keep a simple log with change date, template, action, sample URLs, and before and after counts. That log turns xml sitemap best practices from a confusing label into a manageable workflow with clear ownership and repeatable steps.
Use this quick reference while working on writing accurate lastmod dates from real edits.
| Check | What to confirm | Tool |
|---|---|---|
| Status code and robots | 200 response, allowed by robots, no noindex in meta or headers | View source, headers, URL Inspection live test |
| Canonical intent | Single absolute canonical to preferred 200 URL, matching sitemap | Crawl export, inspection |
| Discovery path | Sitemap inclusion plus at least one contextual internal link | Sitemap index, crawl inlinks |
| Uniqueness | Specific details that differ from site siblings and search competitors | Manual comparison, similarity check |
| Stability | Fast responses, no 5xx spikes, consistent rendering | Crawl stats, server logs |
To finish this stage, pick one cluster related to xml sitemap best practices, apply the checks above, and document the result before expanding to the next cluster. Small batches reduce risk and make cause and effect visible. Share the sheet with developers when code changes are needed, with editors when content rewrites are needed, and with site owners when pruning decisions are needed. Clear ownership keeps writing accurate lastmod dates from real edits from drifting back after temporary gains.
 <!-- IMAGE-PROMPT workflow-02: 1600px max, DependsIt brand mint #22E3B0 on charcoal #121212 or white, node-network line art, Clash Display style headings, General Sans clean labels, subject: xml sitemap best practices remediation workflow from audit to fix to monitoring, flat vector, accessible, no em dash in rendered text -->
Handling images videos and news the selective way
Media and news sitemaps help only when assets add search value and meet policy rules. This section selects valuable images, videos with landing pages, and recent news entries while keeping evergreen files clean. In practical terms, this relates directly to xml sitemap best practices. Site owners often treat each URL in isolation, but Google evaluates patterns across templates, link graphs, and quality thresholds. Understanding the pattern saves time because one template fix can move hundreds of URLs at once.
Consider how xml sitemap best practices appears in the Pages indexing report. Google groups sample URLs under one status, yet the underlying causes vary by section, CMS, and history. Some sites accumulate the status after migrations where redirects and canonicals were incomplete. Others accumulate it gradually as thin archives, tag pages, or faceted filters grow unchecked. Large catalogs add parameter combinations that multiply crawlable paths faster than editorial value grows. Blogs add date archives, author archives, and paginated series that look similar to crawlers. In each case the fix starts with grouping, not with editing a single page. Export up to 1,000 examples, add columns for template, word count, internal inlinks, canonical target, status code, and sitemap presence. That sheet reveals whether xml sitemap best practices clusters on one template or spreads across the site. Template clusters point to code or settings. Spread points to broader quality or linking weakness.
For handling images videos and news the selective way, start with three checks that catch most issues. First, verify technical eligibility. Confirm the URL returns 200, allows crawling in robots.txt, has no noindex in meta or headers, and declares a clean canonical. Use view source, dev tools network headers, and a header fetch. Second, verify discovery signals. Check which sitemaps list the URL, how many internal links point to it, and whether those links use descriptive anchors from relevant hubs. Pages with zero referring internal links rely solely on sitemaps, which weakens demand. Third, verify value signals. Compare title, headings, intro, and main content against indexed competitors. Look for boilerplate repetition, missing specifics, and unclear intent. If a page could be mistaken for another page on your own site, Google may hesitate. Document each check with dates and examples so later monitoring ties changes to outcomes.
Key checks for this stage:
- Audit templates first because xml sitemap best practices rarely affects random singletons. One header, plugin, or filter rule often explains hundreds of rows.
- Compare rendered HTML to raw HTML. JavaScript delayed content can make a page look thin to crawlers even when browsers show full text.
- Review canonical chains. A canonical that points to a redirect, a 404, or a noindexed page confuses consolidation and delays indexing.
- Clean sitemap signals. List only canonical 200 URLs with accurate lastmod. Remove variants, redirects, and excluded pages that dilute attention.
- Strengthen internal context. Add specific links from indexed hubs with natural anchors. Avoid sitewide boilerplate links that carry little topical weight.
Next, apply fixes in priority order. Address eligibility blockers first because no content improvement can overcome a noindex or crawl block. Then fix canonical and duplicate clarity so Google knows which URL should accumulate signals. Then improve content differentiation with specifics such as steps, examples, data points,FAQs, and original observations that separate the page from near duplicates. Then improve internal linking so the page sits fewer clicks from the homepage and receives topical context. Finally, improve freshness and maintenance by updating dates only when content truly changes, fixing broken outbound links, compressing images, and stabilizing server response times. Each layer builds on the previous one. Skipping eligibility and jumping to content expansion wastes effort when a header still carries noindex.
Measurement closes the loop for xml sitemap best practices. Record baseline counts for Valid, Excluded, Discovered, and Crawled statuses. After changes, inspect live samples to confirm eligibility, check Google selected canonical where relevant, and confirm referring sitemap correctness. Request recrawls for a handful of priority URLs rather than every affected URL. Watch crawl stats for increased fetching without server errors. Expect gradual movement across one to two crawl cycles. If counts stall, revisit grouping. Perhaps a second template contributes, or quality thresholds remain unmet. Keep a simple log with change date, template, action, sample URLs, and before and after counts. That log turns xml sitemap best practices from a confusing label into a manageable workflow with clear ownership and repeatable steps.
Use this quick reference while working on handling images videos and news the selective way.
| Check | What to confirm | Tool |
|---|---|---|
| Status code and robots | 200 response, allowed by robots, no noindex in meta or headers | View source, headers, URL Inspection live test |
| Canonical intent | Single absolute canonical to preferred 200 URL, matching sitemap | Crawl export, inspection |
| Discovery path | Sitemap inclusion plus at least one contextual internal link | Sitemap index, crawl inlinks |
| Uniqueness | Specific details that differ from site siblings and search competitors | Manual comparison, similarity check |
| Stability | Fast responses, no 5xx spikes, consistent rendering | Crawl stats, server logs |
To finish this stage, pick one cluster related to xml sitemap best practices, apply the checks above, and document the result before expanding to the next cluster. Small batches reduce risk and make cause and effect visible. Share the sheet with developers when code changes are needed, with editors when content rewrites are needed, and with site owners when pruning decisions are needed. Clear ownership keeps handling images videos and news the selective way from drifting back after temporary gains.
Canonical robots and status alignment
Every listed URL should allow crawling, allow indexing, return 200 in zero hops, and self declare canonical. This section audits headers, meta robots, canonical tags, and sitemap membership together for xml sitemap best practices. In practical terms, this relates directly to xml sitemap best practices. Site owners often treat each URL in isolation, but Google evaluates patterns across templates, link graphs, and quality thresholds. Understanding the pattern saves time because one template fix can move hundreds of URLs at once.
Consider how xml sitemap best practices appears in the Pages indexing report. Google groups sample URLs under one status, yet the underlying causes vary by section, CMS, and history. Some sites accumulate the status after migrations where redirects and canonicals were incomplete. Others accumulate it gradually as thin archives, tag pages, or faceted filters grow unchecked. Large catalogs add parameter combinations that multiply crawlable paths faster than editorial value grows. Blogs add date archives, author archives, and paginated series that look similar to crawlers. In each case the fix starts with grouping, not with editing a single page. Export up to 1,000 examples, add columns for template, word count, internal inlinks, canonical target, status code, and sitemap presence. That sheet reveals whether xml sitemap best practices clusters on one template or spreads across the site. Template clusters point to code or settings. Spread points to broader quality or linking weakness.
For canonical robots and status alignment, start with three checks that catch most issues. First, verify technical eligibility. Confirm the URL returns 200, allows crawling in robots.txt, has no noindex in meta or headers, and declares a clean canonical. Use view source, dev tools network headers, and a header fetch. Second, verify discovery signals. Check which sitemaps list the URL, how many internal links point to it, and whether those links use descriptive anchors from relevant hubs. Pages with zero referring internal links rely solely on sitemaps, which weakens demand. Third, verify value signals. Compare title, headings, intro, and main content against indexed competitors. Look for boilerplate repetition, missing specifics, and unclear intent. If a page could be mistaken for another page on your own site, Google may hesitate. Document each check with dates and examples so later monitoring ties changes to outcomes.
Key checks for this stage:
- Audit templates first because xml sitemap best practices rarely affects random singletons. One header, plugin, or filter rule often explains hundreds of rows.
- Compare rendered HTML to raw HTML. JavaScript delayed content can make a page look thin to crawlers even when browsers show full text.
- Review canonical chains. A canonical that points to a redirect, a 404, or a noindexed page confuses consolidation and delays indexing.
- Clean sitemap signals. List only canonical 200 URLs with accurate lastmod. Remove variants, redirects, and excluded pages that dilute attention.
- Strengthen internal context. Add specific links from indexed hubs with natural anchors. Avoid sitewide boilerplate links that carry little topical weight.
Next, apply fixes in priority order. Address eligibility blockers first because no content improvement can overcome a noindex or crawl block. Then fix canonical and duplicate clarity so Google knows which URL should accumulate signals. Then improve content differentiation with specifics such as steps, examples, data points,FAQs, and original observations that separate the page from near duplicates. Then improve internal linking so the page sits fewer clicks from the homepage and receives topical context. Finally, improve freshness and maintenance by updating dates only when content truly changes, fixing broken outbound links, compressing images, and stabilizing server response times. Each layer builds on the previous one. Skipping eligibility and jumping to content expansion wastes effort when a header still carries noindex.
Measurement closes the loop for xml sitemap best practices. Record baseline counts for Valid, Excluded, Discovered, and Crawled statuses. After changes, inspect live samples to confirm eligibility, check Google selected canonical where relevant, and confirm referring sitemap correctness. Request recrawls for a handful of priority URLs rather than every affected URL. Watch crawl stats for increased fetching without server errors. Expect gradual movement across one to two crawl cycles. If counts stall, revisit grouping. Perhaps a second template contributes, or quality thresholds remain unmet. Keep a simple log with change date, template, action, sample URLs, and before and after counts. That log turns xml sitemap best practices from a confusing label into a manageable workflow with clear ownership and repeatable steps.
Use this quick reference while working on canonical robots and status alignment.
| Check | What to confirm | Tool |
|---|---|---|
| Status code and robots | 200 response, allowed by robots, no noindex in meta or headers | View source, headers, URL Inspection live test |
| Canonical intent | Single absolute canonical to preferred 200 URL, matching sitemap | Crawl export, inspection |
| Discovery path | Sitemap inclusion plus at least one contextual internal link | Sitemap index, crawl inlinks |
| Uniqueness | Specific details that differ from site siblings and search competitors | Manual comparison, similarity check |
| Stability | Fast responses, no 5xx spikes, consistent rendering | Crawl stats, server logs |
To finish this stage, pick one cluster related to xml sitemap best practices, apply the checks above, and document the result before expanding to the next cluster. Small batches reduce risk and make cause and effect visible. Share the sheet with developers when code changes are needed, with editors when content rewrites are needed, and with site owners when pruning decisions are needed. Clear ownership keeps canonical robots and status alignment from drifting back after temporary gains.
Multilingual and multi store sitemap rules
Each locale should list only its own canonical finals with correct hreflang returns. This section separates locales into clear children, validates language annotations, and keeps translated thin shells out until improved. In practical terms, this relates directly to xml sitemap best practices. Site owners often treat each URL in isolation, but Google evaluates patterns across templates, link graphs, and quality thresholds. Understanding the pattern saves time because one template fix can move hundreds of URLs at once.
Consider how xml sitemap best practices appears in the Pages indexing report. Google groups sample URLs under one status, yet the underlying causes vary by section, CMS, and history. Some sites accumulate the status after migrations where redirects and canonicals were incomplete. Others accumulate it gradually as thin archives, tag pages, or faceted filters grow unchecked. Large catalogs add parameter combinations that multiply crawlable paths faster than editorial value grows. Blogs add date archives, author archives, and paginated series that look similar to crawlers. In each case the fix starts with grouping, not with editing a single page. Export up to 1,000 examples, add columns for template, word count, internal inlinks, canonical target, status code, and sitemap presence. That sheet reveals whether xml sitemap best practices clusters on one template or spreads across the site. Template clusters point to code or settings. Spread points to broader quality or linking weakness.
For multilingual and multi store sitemap rules, start with three checks that catch most issues. First, verify technical eligibility. Confirm the URL returns 200, allows crawling in robots.txt, has no noindex in meta or headers, and declares a clean canonical. Use view source, dev tools network headers, and a header fetch. Second, verify discovery signals. Check which sitemaps list the URL, how many internal links point to it, and whether those links use descriptive anchors from relevant hubs. Pages with zero referring internal links rely solely on sitemaps, which weakens demand. Third, verify value signals. Compare title, headings, intro, and main content against indexed competitors. Look for boilerplate repetition, missing specifics, and unclear intent. If a page could be mistaken for another page on your own site, Google may hesitate. Document each check with dates and examples so later monitoring ties changes to outcomes.
Key checks for this stage:
- Audit templates first because xml sitemap best practices rarely affects random singletons. One header, plugin, or filter rule often explains hundreds of rows.
- Compare rendered HTML to raw HTML. JavaScript delayed content can make a page look thin to crawlers even when browsers show full text.
- Review canonical chains. A canonical that points to a redirect, a 404, or a noindexed page confuses consolidation and delays indexing.
- Clean sitemap signals. List only canonical 200 URLs with accurate lastmod. Remove variants, redirects, and excluded pages that dilute attention.
- Strengthen internal context. Add specific links from indexed hubs with natural anchors. Avoid sitewide boilerplate links that carry little topical weight.
Next, apply fixes in priority order. Address eligibility blockers first because no content improvement can overcome a noindex or crawl block. Then fix canonical and duplicate clarity so Google knows which URL should accumulate signals. Then improve content differentiation with specifics such as steps, examples, data points,FAQs, and original observations that separate the page from near duplicates. Then improve internal linking so the page sits fewer clicks from the homepage and receives topical context. Finally, improve freshness and maintenance by updating dates only when content truly changes, fixing broken outbound links, compressing images, and stabilizing server response times. Each layer builds on the previous one. Skipping eligibility and jumping to content expansion wastes effort when a header still carries noindex.
Measurement closes the loop for xml sitemap best practices. Record baseline counts for Valid, Excluded, Discovered, and Crawled statuses. After changes, inspect live samples to confirm eligibility, check Google selected canonical where relevant, and confirm referring sitemap correctness. Request recrawls for a handful of priority URLs rather than every affected URL. Watch crawl stats for increased fetching without server errors. Expect gradual movement across one to two crawl cycles. If counts stall, revisit grouping. Perhaps a second template contributes, or quality thresholds remain unmet. Keep a simple log with change date, template, action, sample URLs, and before and after counts. That log turns xml sitemap best practices from a confusing label into a manageable workflow with clear ownership and repeatable steps.
Use this quick reference while working on multilingual and multi store sitemap rules.
| Check | What to confirm | Tool |
|---|---|---|
| Status code and robots | 200 response, allowed by robots, no noindex in meta or headers | View source, headers, URL Inspection live test |
| Canonical intent | Single absolute canonical to preferred 200 URL, matching sitemap | Crawl export, inspection |
| Discovery path | Sitemap inclusion plus at least one contextual internal link | Sitemap index, crawl inlinks |
| Uniqueness | Specific details that differ from site siblings and search competitors | Manual comparison, similarity check |
| Stability | Fast responses, no 5xx spikes, consistent rendering | Crawl stats, server logs |
To finish this stage, pick one cluster related to xml sitemap best practices, apply the checks above, and document the result before expanding to the next cluster. Small batches reduce risk and make cause and effect visible. Share the sheet with developers when code changes are needed, with editors when content rewrites are needed, and with site owners when pruning decisions are needed. Clear ownership keeps multilingual and multi store sitemap rules from drifting back after temporary gains.
Common sitemap mistakes that slow indexing
Dead entries, redirect targets missed, noindex conflicts, hostname leaks, and synthetic freshness are the frequent culprits. This section catalogs each mistake with the generator setting that prevents it under xml sitemap best practices. In practical terms, this relates directly to xml sitemap best practices. Site owners often treat each URL in isolation, but Google evaluates patterns across templates, link graphs, and quality thresholds. Understanding the pattern saves time because one template fix can move hundreds of URLs at once.
Consider how xml sitemap best practices appears in the Pages indexing report. Google groups sample URLs under one status, yet the underlying causes vary by section, CMS, and history. Some sites accumulate the status after migrations where redirects and canonicals were incomplete. Others accumulate it gradually as thin archives, tag pages, or faceted filters grow unchecked. Large catalogs add parameter combinations that multiply crawlable paths faster than editorial value grows. Blogs add date archives, author archives, and paginated series that look similar to crawlers. In each case the fix starts with grouping, not with editing a single page. Export up to 1,000 examples, add columns for template, word count, internal inlinks, canonical target, status code, and sitemap presence. That sheet reveals whether xml sitemap best practices clusters on one template or spreads across the site. Template clusters point to code or settings. Spread points to broader quality or linking weakness.
For common sitemap mistakes that slow indexing, start with three checks that catch most issues. First, verify technical eligibility. Confirm the URL returns 200, allows crawling in robots.txt, has no noindex in meta or headers, and declares a clean canonical. Use view source, dev tools network headers, and a header fetch. Second, verify discovery signals. Check which sitemaps list the URL, how many internal links point to it, and whether those links use descriptive anchors from relevant hubs. Pages with zero referring internal links rely solely on sitemaps, which weakens demand. Third, verify value signals. Compare title, headings, intro, and main content against indexed competitors. Look for boilerplate repetition, missing specifics, and unclear intent. If a page could be mistaken for another page on your own site, Google may hesitate. Document each check with dates and examples so later monitoring ties changes to outcomes.
Key checks for this stage:
- Audit templates first because xml sitemap best practices rarely affects random singletons. One header, plugin, or filter rule often explains hundreds of rows.
- Compare rendered HTML to raw HTML. JavaScript delayed content can make a page look thin to crawlers even when browsers show full text.
- Review canonical chains. A canonical that points to a redirect, a 404, or a noindexed page confuses consolidation and delays indexing.
- Clean sitemap signals. List only canonical 200 URLs with accurate lastmod. Remove variants, redirects, and excluded pages that dilute attention.
- Strengthen internal context. Add specific links from indexed hubs with natural anchors. Avoid sitewide boilerplate links that carry little topical weight.
Next, apply fixes in priority order. Address eligibility blockers first because no content improvement can overcome a noindex or crawl block. Then fix canonical and duplicate clarity so Google knows which URL should accumulate signals. Then improve content differentiation with specifics such as steps, examples, data points,FAQs, and original observations that separate the page from near duplicates. Then improve internal linking so the page sits fewer clicks from the homepage and receives topical context. Finally, improve freshness and maintenance by updating dates only when content truly changes, fixing broken outbound links, compressing images, and stabilizing server response times. Each layer builds on the previous one. Skipping eligibility and jumping to content expansion wastes effort when a header still carries noindex.
Measurement closes the loop for xml sitemap best practices. Record baseline counts for Valid, Excluded, Discovered, and Crawled statuses. After changes, inspect live samples to confirm eligibility, check Google selected canonical where relevant, and confirm referring sitemap correctness. Request recrawls for a handful of priority URLs rather than every affected URL. Watch crawl stats for increased fetching without server errors. Expect gradual movement across one to two crawl cycles. If counts stall, revisit grouping. Perhaps a second template contributes, or quality thresholds remain unmet. Keep a simple log with change date, template, action, sample URLs, and before and after counts. That log turns xml sitemap best practices from a confusing label into a manageable workflow with clear ownership and repeatable steps.
Use this quick reference while working on common sitemap mistakes that slow indexing.
| Check | What to confirm | Tool |
|---|---|---|
| Status code and robots | 200 response, allowed by robots, no noindex in meta or headers | View source, headers, URL Inspection live test |
| Canonical intent | Single absolute canonical to preferred 200 URL, matching sitemap | Crawl export, inspection |
| Discovery path | Sitemap inclusion plus at least one contextual internal link | Sitemap index, crawl inlinks |
| Uniqueness | Specific details that differ from site siblings and search competitors | Manual comparison, similarity check |
| Stability | Fast responses, no 5xx spikes, consistent rendering | Crawl stats, server logs |
To finish this stage, pick one cluster related to xml sitemap best practices, apply the checks above, and document the result before expanding to the next cluster. Small batches reduce risk and make cause and effect visible. Share the sheet with developers when code changes are needed, with editors when content rewrites are needed, and with site owners when pruning decisions are needed. Clear ownership keeps common sitemap mistakes that slow indexing from drifting back after temporary gains.
Validating and testing before submission
Parse XML, fetch every URL, check status and directives, and confirm index references before submitting in Search Console. This section gives a preflight sequence that blocks dirty files from deploying. In practical terms, this relates directly to xml sitemap best practices. Site owners often treat each URL in isolation, but Google evaluates patterns across templates, link graphs, and quality thresholds. Understanding the pattern saves time because one template fix can move hundreds of URLs at once.
Consider how xml sitemap best practices appears in the Pages indexing report. Google groups sample URLs under one status, yet the underlying causes vary by section, CMS, and history. Some sites accumulate the status after migrations where redirects and canonicals were incomplete. Others accumulate it gradually as thin archives, tag pages, or faceted filters grow unchecked. Large catalogs add parameter combinations that multiply crawlable paths faster than editorial value grows. Blogs add date archives, author archives, and paginated series that look similar to crawlers. In each case the fix starts with grouping, not with editing a single page. Export up to 1,000 examples, add columns for template, word count, internal inlinks, canonical target, status code, and sitemap presence. That sheet reveals whether xml sitemap best practices clusters on one template or spreads across the site. Template clusters point to code or settings. Spread points to broader quality or linking weakness.
For validating and testing before submission, start with three checks that catch most issues. First, verify technical eligibility. Confirm the URL returns 200, allows crawling in robots.txt, has no noindex in meta or headers, and declares a clean canonical. Use view source, dev tools network headers, and a header fetch. Second, verify discovery signals. Check which sitemaps list the URL, how many internal links point to it, and whether those links use descriptive anchors from relevant hubs. Pages with zero referring internal links rely solely on sitemaps, which weakens demand. Third, verify value signals. Compare title, headings, intro, and main content against indexed competitors. Look for boilerplate repetition, missing specifics, and unclear intent. If a page could be mistaken for another page on your own site, Google may hesitate. Document each check with dates and examples so later monitoring ties changes to outcomes.
Key checks for this stage:
- Audit templates first because xml sitemap best practices rarely affects random singletons. One header, plugin, or filter rule often explains hundreds of rows.
- Compare rendered HTML to raw HTML. JavaScript delayed content can make a page look thin to crawlers even when browsers show full text.
- Review canonical chains. A canonical that points to a redirect, a 404, or a noindexed page confuses consolidation and delays indexing.
- Clean sitemap signals. List only canonical 200 URLs with accurate lastmod. Remove variants, redirects, and excluded pages that dilute attention.
- Strengthen internal context. Add specific links from indexed hubs with natural anchors. Avoid sitewide boilerplate links that carry little topical weight.
Next, apply fixes in priority order. Address eligibility blockers first because no content improvement can overcome a noindex or crawl block. Then fix canonical and duplicate clarity so Google knows which URL should accumulate signals. Then improve content differentiation with specifics such as steps, examples, data points,FAQs, and original observations that separate the page from near duplicates. Then improve internal linking so the page sits fewer clicks from the homepage and receives topical context. Finally, improve freshness and maintenance by updating dates only when content truly changes, fixing broken outbound links, compressing images, and stabilizing server response times. Each layer builds on the previous one. Skipping eligibility and jumping to content expansion wastes effort when a header still carries noindex.
Measurement closes the loop for xml sitemap best practices. Record baseline counts for Valid, Excluded, Discovered, and Crawled statuses. After changes, inspect live samples to confirm eligibility, check Google selected canonical where relevant, and confirm referring sitemap correctness. Request recrawls for a handful of priority URLs rather than every affected URL. Watch crawl stats for increased fetching without server errors. Expect gradual movement across one to two crawl cycles. If counts stall, revisit grouping. Perhaps a second template contributes, or quality thresholds remain unmet. Keep a simple log with change date, template, action, sample URLs, and before and after counts. That log turns xml sitemap best practices from a confusing label into a manageable workflow with clear ownership and repeatable steps.
Use this quick reference while working on validating and testing before submission.
| Check | What to confirm | Tool |
|---|---|---|
| Status code and robots | 200 response, allowed by robots, no noindex in meta or headers | View source, headers, URL Inspection live test |
| Canonical intent | Single absolute canonical to preferred 200 URL, matching sitemap | Crawl export, inspection |
| Discovery path | Sitemap inclusion plus at least one contextual internal link | Sitemap index, crawl inlinks |
| Uniqueness | Specific details that differ from site siblings and search competitors | Manual comparison, similarity check |
| Stability | Fast responses, no 5xx spikes, consistent rendering | Crawl stats, server logs |
To finish this stage, pick one cluster related to xml sitemap best practices, apply the checks above, and document the result before expanding to the next cluster. Small batches reduce risk and make cause and effect visible. Share the sheet with developers when code changes are needed, with editors when content rewrites are needed, and with site owners when pruning decisions are needed. Clear ownership keeps validating and testing before submission from drifting back after temporary gains.
Maintaining xml sitemap best practices over time
Monthly warning reviews, quarterly full audits, and deploy time checks keep files clean for years. This section assigns owners per child, logs rule changes, and tracks indexed share so xml sitemap best practices survive team turnover. In practical terms, this relates directly to xml sitemap best practices. Site owners often treat each URL in isolation, but Google evaluates patterns across templates, link graphs, and quality thresholds. Understanding the pattern saves time because one template fix can move hundreds of URLs at once.
Consider how xml sitemap best practices appears in the Pages indexing report. Google groups sample URLs under one status, yet the underlying causes vary by section, CMS, and history. Some sites accumulate the status after migrations where redirects and canonicals were incomplete. Others accumulate it gradually as thin archives, tag pages, or faceted filters grow unchecked. Large catalogs add parameter combinations that multiply crawlable paths faster than editorial value grows. Blogs add date archives, author archives, and paginated series that look similar to crawlers. In each case the fix starts with grouping, not with editing a single page. Export up to 1,000 examples, add columns for template, word count, internal inlinks, canonical target, status code, and sitemap presence. That sheet reveals whether xml sitemap best practices clusters on one template or spreads across the site. Template clusters point to code or settings. Spread points to broader quality or linking weakness.
For maintaining sitemap quality over time, start with three checks that catch most issues. First, verify technical eligibility. Confirm the URL returns 200, allows crawling in robots.txt, has no noindex in meta or headers, and declares a clean canonical. Use view source, dev tools network headers, and a header fetch. Second, verify discovery signals. Check which sitemaps list the URL, how many internal links point to it, and whether those links use descriptive anchors from relevant hubs. Pages with zero referring internal links rely solely on sitemaps, which weakens demand. Third, verify value signals. Compare title, headings, intro, and main content against indexed competitors. Look for boilerplate repetition, missing specifics, and unclear intent. If a page could be mistaken for another page on your own site, Google may hesitate. Document each check with dates and examples so later monitoring ties changes to outcomes.
Key checks for this stage:
- Audit templates first because xml sitemap best practices rarely affects random singletons. One header, plugin, or filter rule often explains hundreds of rows.
- Compare rendered HTML to raw HTML. JavaScript delayed content can make a page look thin to crawlers even when browsers show full text.
- Review canonical chains. A canonical that points to a redirect, a 404, or a noindexed page confuses consolidation and delays indexing.
- Clean sitemap signals. List only canonical 200 URLs with accurate lastmod. Remove variants, redirects, and excluded pages that dilute attention.
- Strengthen internal context. Add specific links from indexed hubs with natural anchors. Avoid sitewide boilerplate links that carry little topical weight.
Next, apply fixes in priority order. Address eligibility blockers first because no content improvement can overcome a noindex or crawl block. Then fix canonical and duplicate clarity so Google knows which URL should accumulate signals. Then improve content differentiation with specifics such as steps, examples, data points,FAQs, and original observations that separate the page from near duplicates. Then improve internal linking so the page sits fewer clicks from the homepage and receives topical context. Finally, improve freshness and maintenance by updating dates only when content truly changes, fixing broken outbound links, compressing images, and stabilizing server response times. Each layer builds on the previous one. Skipping eligibility and jumping to content expansion wastes effort when a header still carries noindex.
Measurement closes the loop for xml sitemap best practices. Record baseline counts for Valid, Excluded, Discovered, and Crawled statuses. After changes, inspect live samples to confirm eligibility, check Google selected canonical where relevant, and confirm referring sitemap correctness. Request recrawls for a handful of priority URLs rather than every affected URL. Watch crawl stats for increased fetching without server errors. Expect gradual movement across one to two crawl cycles. If counts stall, revisit grouping. Perhaps a second template contributes, or quality thresholds remain unmet. Keep a simple log with change date, template, action, sample URLs, and before and after counts. That log turns xml sitemap best practices from a confusing label into a manageable workflow with clear ownership and repeatable steps.
Use this quick reference while working on maintaining sitemap quality over time.
| Check | What to confirm | Tool |
|---|---|---|
| Status code and robots | 200 response, allowed by robots, no noindex in meta or headers | View source, headers, URL Inspection live test |
| Canonical intent | Single absolute canonical to preferred 200 URL, matching sitemap | Crawl export, inspection |
| Discovery path | Sitemap inclusion plus at least one contextual internal link | Sitemap index, crawl inlinks |
| Uniqueness | Specific details that differ from site siblings and search competitors | Manual comparison, similarity check |
| Stability | Fast responses, no 5xx spikes, consistent rendering | Crawl stats, server logs |
To finish this stage, pick one cluster related to xml sitemap best practices, apply the checks above, and document the result before expanding to the next cluster. Small batches reduce risk and make cause and effect visible. Share the sheet with developers when code changes are needed, with editors when content rewrites are needed, and with site owners when pruning decisions are needed. Clear ownership keeps maintaining sitemap quality over time from drifting back after temporary gains.
FAQ
What URLs should an XML sitemap include?
Include only canonical URLs that return 200, allow crawling and indexing, self reference as canonical, and contain useful distinct content. Exclude drafts, noindex pages, redirecting URLs, parameter variants, internal search results, staging hosts, and thin placeholders. A smaller accurate file earns more frequent fetching and clearer reports than a large file that mixes valuable pages with dead ends. These sitemap tips mirror a concise sitemap format guide that editors can follow without guessing, and they double as sitemap seo tips for keeping reports clean while following core sitemap guidelines.
How large can a sitemap be?
Keep each file under 50000 URLs and 50 MB uncompressed, with much smaller files preferred for speed and debugging. Split by section or type into stable children under one index. Compress with gzip, cache at the edge, and serve quickly. Small fast files get fetched more reliably, isolate errors to one owner, and make diffs readable during audits.
Do changefreq and priority still matter?
Google largely ignores changefreq and priority, so focus on accurate membership and honest lastmod instead. If your generator includes those fields, set conservative values and spend effort on listing the right URLs with truthful modification dates. Overstating freshness or priority blends into the same distrust created by dead entries and provides no crawling benefit. Treat sitemap priorities as hints at best and focus on sitemap optimization, strict sitemap url rules, honest sitemap freshness, and a sitemap structure best layout that approaches a perfect xml sitemap for your size.
How often should I update my sitemap?
Update on content events such as publish, meaningful edit, redirect, and delete, with a nightly full rebuild as backup. Avoid daily blanket lastmod updates for unchanged pages. Resubmit the index in Search Console after major corrections, then let natural refetching carry routine changes. Review warnings monthly and run full validation quarterly plus after every migration.
Should images and videos go in the sitemap?
Include media only when it adds search value, such as product photos, tutorial images, or hosted videos with dedicated indexable landing pages. Exclude decorative assets and duplicates of landing page content without distinct queries. For news, include only recent policy compliant articles and remove entries as they age out. Selective media files improve discovery without adding maintenance noise.
Will a perfect sitemap guarantee indexing?
No. A clean sitemap removes friction and improves discovery speed, but indexing still depends on content quality, uniqueness, internal links, and site trust. Expect faster fetching and clearer coverage first, then gradual indexing gains as pages prove value. Pair sitemap hygiene with content depth, canonical clarity, and hub linking for durable results.