Google Indexing API Rate Limits: What to Do When You Hit the Ceiling
This guide is for developers and SEO leads who keep hitting an indexing API rate limit on the Google Indexing API and need a calm fix. Limits include daily publish quotas and per minute throttles that return 429 when bursts arrive. The API documents JobPosting and BroadcastEvent pages, so normal pages already face filtering. You will learn how to read 429 responses, apply exponential backoff with jitter, design queues, prioritize URLs and monitor Cloud Console before the ceiling hits. By the end you can pace bulk work safely and recover without losing pending URLs.
Key takeaways
- Daily quotas and per minute throttles are separate, and both can return 429.
- Backoff with jitter plus a paced queue prevents most repeat blocks.
- Prioritize new and changed URLs so limited quota serves business needs first.
- Cloud Console alerts at 60 and 85 percent give time to slow down before failure.
- How rate limits and quotas differ on the Indexing API
- Default publish limits and per minute throttles
- What a 429 response really means and what headers to read
- Exponential backoff that respects Retry After
- Designing a queue for indexing API rate limit safety
- Prioritizing URLs when you cannot submit everything
- Monitoring usage in Cloud Console before you hit the ceiling
- Handling bursts after migrations, launches and sales
- Code patterns for Python, Node and PHP with retry logic
- Recovering after repeated throttling without losing URLs
- Long term strategies to request more headroom
 <!-- IMAGE-PROMPT cover: 1200x630, DependsIt brand, deep charcoal #121212 background with vibrant mint #22E3B0 accent glow, thin node-network line art, Clash Display style bold heading space on left, General Sans clean labels, subject: indexing api rate limit cover illustration, flat vector, high contrast, accessible, no photorealistic faces, no text smaller than 24px, no em dash in rendered text, export PNG then cwebp -q 82 to WEBP -->
How rate limits and quotas differ on the Indexing API
This section covers how rate limits and quotas differ on the indexing api in the context of indexing api rate limit. Quota caps total calls per day, while rate limits cap burst speed per minute or per second. We keep the advice practical for owners without a large SEO team. Each step below uses plain checks you can run with Search Console, server logs and a small script. The goal is steady progress you can measure in coverage reports, not a one time spike. Keep notes on what you change and when, so you can link indexing movement to specific fixes.
Google discovers most pages through crawl, not through a single submission. A submission is a hint that asks for a fresh look, but ranking and storage still depend on quality, uniqueness and site trust. That is why steady technical hygiene matters more than any one push. Keep response times low, avoid redirect chains, and return clear status codes. When the crawler can fetch quickly and without loops, each hint carries more weight and uses less of your daily allowance.
Sitemaps remain the backbone of discovery. A clean product or article sitemap lists only canonical, indexable URLs that return 200 and load quickly. Split large catalogs into chunks of 10,000 to 40,000 URLs, compress with gzip, and reference each chunk from a sitemap index. Update the lastmod field only when content truly changes. Submit the index in Search Console and keep it reachable. A tidy sitemap reduces wasted fetches and leaves room for priority pages.
Crawl budget is often misunderstood. For small sites it rarely limits indexing, but for catalogs with 50,000 to 500,000 URLs it shapes what gets visited each day. Facets, session parameters, internal search results and duplicate variants can trap crawlers in low value loops. Use robots rules to block filtered views, use canonical tags to consolidate variants, and link best sellers from the home page and category hubs. Fewer dead ends means faster visits to new and updated pages.
In practice, set a worker that pulls one URL at a time, sends the request with a 15 second timeout, and records status, latency and response snippet. On 200, mark done and continue. On 429, read Retry After, sleep for that period plus jitter, then halve the pull rate. On 403 or 401, pause the queue and alert, since retries will not fix auth. On 400, fix the payload and do not retry blindly. This small state machine keeps you under the ceiling even during busy catalog days.
| Signal | Meaning | Next step |
|---|---|---|
| 200 | Hint accepted | Continue at same pace |
| 400 | Bad request | Fix payload, do not blind retry |
| 401 | Auth failed | Refresh token, check key |
| 403 | Permission failed | Check Search Console owners |
| 429 | Too many requests | Back off and slow queue |
Default publish limits and per minute throttles
This section covers default publish limits and per minute throttles in the context of indexing api rate limit. Publish calls often start near 200 per day per project, with metadata calls counted separately. We keep the advice practical for owners without a large SEO team. Each step below uses plain checks you can run with Search Console, server logs and a small script. The goal is steady progress you can measure in coverage reports, not a one time spike. Keep notes on what you change and when, so you can link indexing movement to specific fixes.
Search Console verification is the gate for any Google submission. The service account that calls the API must be added as an Owner on the exact property, including the correct scheme and subdomain. Domain properties and URL prefix properties behave differently, so match the property you verify with the URLs you submit. If you see permission denied or 403, check sharing settings first, then OAuth scope, then key expiry. Most auth failures trace to a missed sharing step, not to code.
The Google Indexing API only documents JobPosting and BroadcastEvent pages, which covers job listings and livestream video. Many site owners still test it for product or article URLs, but that use is off label and results vary. Google may process the hint, ignore it, or throttle it. State this plainly to stakeholders. Use the API for eligible content first, and rely on sitemaps, internal links and IndexNow for broad coverage on other page types.
Google does not support IndexNow, so plan for two ecosystems. IndexNow notifies Bing, Yandex, Naver, Seznam and other partners that share the protocol, while Google relies on sitemaps, Search Console inspection and the Indexing API for eligible types. A practical setup sends product updates to both paths at publish time. One worker prepares the URL list, then one branch pings IndexNow endpoints and another branch queues Google notifications within quota. Coverage improves without double counting.
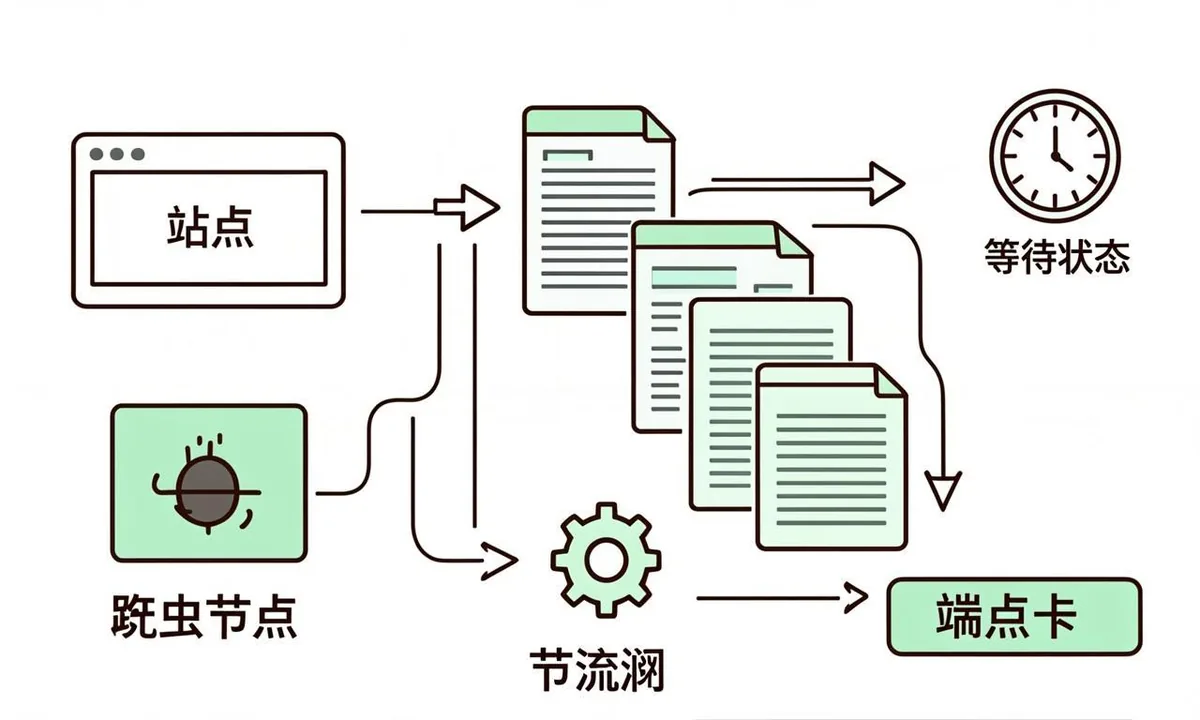
In practice, set a worker that pulls one URL at a time, sends the request with a 15 second timeout, and records status, latency and response snippet. On 200, mark done and continue. On 429, read Retry After, sleep for that period plus jitter, then halve the pull rate. On 403 or 401, pause the queue and alert, since retries will not fix auth. On 400, fix the payload and do not retry blindly. This small state machine keeps you under the ceiling even during busy catalog days.
For background on a related setup, see quota limits explained for daily planning which explains how publishers structure notifications and sitemaps for time sensitive pages.
- Step 1: Export the full URL list from your CMS or commerce platform with last change dates.
- Step 2: Join with Search Console coverage to flag Discovered, Crawled, Excluded and Indexed states.
- Step 3: Remove duplicates, 404s, noindex pages and non canonical variants from the submit set.
- Step 4: Sort by priority such as new, price change, availability change, then evergreen refresh.
- Step 5: Queue at a paced rate, log every response, and pause on repeated 429 or 403.
 <!-- IMAGE-PROMPT diagram-01: 1600px max, DependsIt brand mint #22E3B0 on charcoal #121212, node-network line art, Clash Display style headings feel with General Sans clean labels, subject: indexing api rate limit diagram with crawl and queue nodes, flat vector, accessible, no em dash in rendered text -->
What a 429 response really means and what headers to read
This section covers what a 429 response really means and what headers to read in the context of indexing api rate limit. A 429 with Retry After asks for patience, while repeated 429 without waiting extends the block. When you see rate limit exceeded in logs, treat it as an indexing api 429 fix task: pause, honor Retry After, then resume slower. We keep the advice practical for owners without a large SEO team. Each step below uses plain checks you can run with Search Console, server logs and a small script. The goal is steady progress you can measure in coverage reports, not a one time spike. Keep notes on what you change and when, so you can link indexing movement to specific fixes.
Quotas shape every automation decision. Many projects start with about 200 publish requests per day for URL notifications, plus per minute limits that trigger 429 when bursts arrive. Track usage in Cloud Console under APIs and Services, set alerts at 60 percent and 85 percent, and log each publish with timestamp, URL, response code and notification type. When you know your burn rate by hour, you can pace jobs, defer low priority URLs and avoid midnight surprises.
A 429 means slow down, not try harder. Read the Retry After header when present, then wait with exponential backoff and jitter before retrying. A common pattern waits 2 seconds, then 4, then 8, then 16, with a small random addition to avoid synchronized retries. Cap retries at 4 or 5 and move the URL to a delayed queue after that. Hammering the endpoint during a limit only extends the block and burns log space.
A 403 usually points to permissions or scope. Confirm the service account email has Owner access in Search Console, confirm the OAuth scope includes the indexing scope, and confirm the JSON key file matches the active key in Cloud Console. Check clock skew on the server, since JWT auth fails when time drifts by more than a few minutes. Rotate keys on a schedule, store them in a secret manager, and never paste private keys into chat tools or shared docs.
In practice, set a worker that pulls one URL at a time, sends the request with a 15 second timeout, and records status, latency and response snippet. On 200, mark done and continue. On 429, read Retry After, sleep for that period plus jitter, then halve the pull rate. On 403 or 401, pause the queue and alert, since retries will not fix auth. On 400, fix the payload and do not retry blindly. This small state machine keeps you under the ceiling even during busy catalog days.
For official details, see HTTP status codes on MDN which documents the expected fields and behavior.
| Signal | Meaning | Next step |
|---|---|---|
| 200 | Hint accepted | Continue at same pace |
| 400 | Bad request | Fix payload, do not blind retry |
| 401 | Auth failed | Refresh token, check key |
| 403 | Permission failed | Check Search Console owners |
| 429 | Too many requests | Back off and slow queue |
Exponential backoff that respects Retry After
This section covers exponential backoff that respects retry after in the context of indexing api rate limit. Backoff spreads retries over seconds to minutes and adds jitter to avoid synchronized storms. We keep the advice practical for owners without a large SEO team. Each step below uses plain checks you can run with Search Console, server logs and a small script. The goal is steady progress you can measure in coverage reports, not a one time spike. Keep notes on what you change and when, so you can link indexing movement to specific fixes.
JWT failures look cryptic but follow a pattern. Invalid signature often means the wrong key file or a corrupted newline in the private key. Invalid grant often means the service account is disabled or the project never enabled the API. Failed to parse often means the token was truncated in logs or copied with extra spaces. Keep token lifetimes short, request a fresh access token per batch, and log the key ID without logging the secret. Small hygiene steps remove most auth noise.
Logging turns guesses into fixes. For each submission store the URL, notification type, HTTP status, response body snippet, latency and a correlation ID. Keep success and error logs separate so you can scan error rates by hour. Export daily counts to a sheet or dashboard that shows submits, 200 responses, 403 responses, 429 responses and remaining quota. When stakeholders ask why a product is not visible, you can point to exact evidence instead of general theories.
Internal linking does more for indexing than most teams expect. New URLs that sit four clicks from the home page may wait days for a visit, while URLs linked from a popular category or a recent posts block get visited quickly. Add new products to relevant category pages, link related items, and keep pagination crawlable with plain anchors. Avoid loading key links only through scripts that require clicks. Simple, stable links help both Google and IndexNow driven crawlers find changes fast.
In practice, set a worker that pulls one URL at a time, sends the request with a 15 second timeout, and records status, latency and response snippet. On 200, mark done and continue. On 429, read Retry After, sleep for that period plus jitter, then halve the pull rate. On 403 or 401, pause the queue and alert, since retries will not fix auth. On 400, fix the payload and do not retry blindly. This small state machine keeps you under the ceiling even during busy catalog days.
To compare paths side by side, read a recovery playbook for quota exceeded before you commit quota to one route.
- Step 1: Export the full URL list from your CMS or commerce platform with last change dates.
- Step 2: Join with Search Console coverage to flag Discovered, Crawled, Excluded and Indexed states.
- Step 3: Remove duplicates, 404s, noindex pages and non canonical variants from the submit set.
- Step 4: Sort by priority such as new, price change, availability change, then evergreen refresh.
- Step 5: Queue at a paced rate, log every response, and pause on repeated 429 or 403.
Designing a queue for indexing API rate limit safety
This section covers designing a queue for indexing API rate limit safety. A durable indexing queue system with next retry times keeps order and prevents duplicate submits. Respect indexing api requests per minute by capping the worker below the observed ceiling, since api throttling triggers as soon as bursts stack up. The practical rate limit workaround is to throttle url submissions to a steady pace rather than sending bursts. We keep the advice practical for owners without a large SEO team. Each step below uses plain checks you can run with Search Console, server logs and a small script. The goal is steady progress you can measure in coverage reports, not a one time spike. Keep notes on what you change and when, so you can link indexing movement to specific fixes.
Canonical tags decide which URL keeps the indexing credit. If variants with color, size or tracking parameters lack a canonical, Google may pick a different URL or delay indexing while it compares duplicates. Point each variant to the preferred canonical, keep the canonical self referencing on the main URL, and make sure sitemaps list only canonicals. For translated or regional pages, add hreflang and keep each locale self consistent. Clean signals shorten the decision time.
Robots directives and meta tags can silently block indexing. A stray noindex in a template, an X-Robots-Tag header from a staging config, or a disallow in robots that covers new paths will keep pages out even after successful submission. Audit headers with a fetch tool, render pages as Googlebot, and check the coverage report for Excluded by noindex or Blocked by robots. Fix the template once rather than patching URLs one by one.
Thin or duplicated content slows indexing because Google prioritizes pages likely to satisfy searchers. Short product descriptions copied from suppliers, empty category pages and near duplicate articles often sit in Discovered or Crawled without indexing. Add specific details such as dimensions, materials, compatibility, usage steps and original photos. Consolidate near duplicates into one strong page with redirects. Better content earns more frequent revisits and steadier indexing.
In practice, set a worker that pulls one URL at a time, sends the request with a 15 second timeout, and records status, latency and response snippet. On 200, mark done and continue. On 429, read Retry After, sleep for that period plus jitter, then halve the pull rate. On 403 or 401, pause the queue and alert, since retries will not fix auth. On 400, fix the payload and do not retry blindly. This small state machine keeps you under the ceiling even during busy catalog days.
| Signal | Meaning | Next step |
|---|---|---|
| 200 | Hint accepted | Continue at same pace |
| 400 | Bad request | Fix payload, do not blind retry |
| 401 | Auth failed | Refresh token, check key |
| 403 | Permission failed | Check Search Console owners |
| 429 | Too many requests | Back off and slow queue |
# Python submit with backoff and logging, no em dash in comments
import time, random, requests
from google.oauth2 import service_account
from google.auth.transport.requests import Request

SCOPES = ['https://www.googleapis.com/auth/indexing']
creds = service_account.Credentials.from_service_account_file('key.json', scopes=SCOPES)
creds.refresh(Request())
headers = {'Content-Type': 'application/json', 'Authorization': 'Bearer ' + creds.token}
payload = {'url': 'https://example.com/jobs/123', 'type': 'URL_UPDATED'}
for attempt in range(5):
    r = requests.post('https://indexing.googleapis.com/v3/urlNotifications:publish', json=payload, headers=headers, timeout=15)
    print(r.status_code, r.text[:300])
    if r.status_code != 429:
        break
    wait = 2 ** attempt + random.uniform(0, 1)
    time.sleep(wait)
Prioritizing URLs when you cannot submit everything
This section covers prioritizing urls when you cannot submit everything in the context of indexing api rate limit. When allowance is tight, new jobs, live pages and price changes outrank routine refreshes. We keep the advice practical for owners without a large SEO team. Each step below uses plain checks you can run with Search Console, server logs and a small script. The goal is steady progress you can measure in coverage reports, not a one time spike. Keep notes on what you change and when, so you can link indexing movement to specific fixes.
Response codes guide the next action. A 200 with URL_UPDATED means the hint was accepted, not that the page is indexed. A 200 with URL_DELETED means the removal hint was accepted. A 400 means the request body was malformed. A 401 means auth failed. A 403 means permission failed. A 404 on metadata means no notification history exists. A 429 means quota or rate pressure. Map each code to a runbook entry so on call staff know whether to retry, fix auth or pause.
Bulk work needs a queue, not a loop without pauses. Push new and updated URLs into a table or message queue with fields for URL, change type, priority, attempts and next retry time. A worker pulls 1 to 5 URLs per minute during normal hours and slows further when 429 appears. High priority URLs such as new jobs, live videos or price changes go first, while low priority refreshes wait. This pacing respects quotas and keeps logs readable.
Edge automation can speed discovery for Bing side engines. Cloudflare Workers or a deploy hook can fire an IndexNow ping the moment a page publishes, without waiting for a nightly job. Store the IndexNow key in a secret, build the JSON payload with host, key and URL list, and POST to the IndexNow endpoint with a timeout of 10 seconds. Log response codes 200, 202, 400, 403 and 422 separately. Fast pings plus clean sitemaps give broad engines a clear trail to follow.
In practice, set a worker that pulls one URL at a time, sends the request with a 15 second timeout, and records status, latency and response snippet. On 200, mark done and continue. On 429, read Retry After, sleep for that period plus jitter, then halve the pull rate. On 403 or 401, pause the queue and alert, since retries will not fix auth. On 400, fix the payload and do not retry blindly. This small state machine keeps you under the ceiling even during busy catalog days.
A useful companion is causes and backoff for HTTP 429 which clarifies when each notification type is appropriate.
- Step 1: Export the full URL list from your CMS or commerce platform with last change dates.
- Step 2: Join with Search Console coverage to flag Discovered, Crawled, Excluded and Indexed states.
- Step 3: Remove duplicates, 404s, noindex pages and non canonical variants from the submit set.
- Step 4: Sort by priority such as new, price change, availability change, then evergreen refresh.
- Step 5: Queue at a paced rate, log every response, and pause on repeated 429 or 403.
 <!-- IMAGE-PROMPT workflow-02: 1600px max, DependsIt brand mint #22E3B0 on charcoal #121212 or white, node-network line art, Clash Display style heading feel with General Sans labels, subject: indexing api rate limit workflow with publish and retry lanes, flat vector, accessible, no em dash in rendered text -->
Monitoring usage in Cloud Console before you hit the ceiling
This section covers monitoring usage in cloud console before you hit the ceiling in the context of indexing api rate limit. Cloud Console graphs show burn rate by hour, error share and remaining headroom. We keep the advice practical for owners without a large SEO team. Each step below uses plain checks you can run with Search Console, server logs and a small script. The goal is steady progress you can measure in coverage reports, not a one time spike. Keep notes on what you change and when, so you can link indexing movement to specific fixes.
Monitoring in Cloud Console prevents most outages. Open the project, select the Indexing API, and review traffic by response code, median latency and errors over 7 and 28 days. Create an alert that fires when error rate passes 5 percent or when daily publishes pass 80 percent of quota. Review which service account or key generates the most traffic. If a test script runs wild, you will see it within minutes and can disable the key before quota is gone.
Recovery after exhaustion is about order, not speed. Pause new publishes, export the pending list, remove duplicates and noindex URLs, then sort by business priority and age. Resume at a low rate such as 1 request every 30 to 60 seconds and watch for 429. If errors return, halve the rate and extend the pause. Most daily quotas reset around midnight Pacific, but per minute throttles clear sooner. Document the incident so the next launch uses a safer schedule.
Security for service account keys deserves steady attention. Create one project per environment, grant only the roles needed for publishing, and store JSON keys in a vault with rotation every 60 to 90 days. Restrict key use by IP or workload where the platform allows it. Delete old keys after rotation and audit who accessed the vault. If a key leaks in a repo or log, revoke it at once, create a replacement, and review submissions made with the exposed key.
In practice, set a worker that pulls one URL at a time, sends the request with a 15 second timeout, and records status, latency and response snippet. On 200, mark done and continue. On 429, read Retry After, sleep for that period plus jitter, then halve the pull rate. On 403 or 401, pause the queue and alert, since retries will not fix auth. On 400, fix the payload and do not retry blindly. This small state machine keeps you under the ceiling even during busy catalog days.
| Signal | Meaning | Next step |
|---|---|---|
| 200 | Hint accepted | Continue at same pace |
| 400 | Bad request | Fix payload, do not blind retry |
| 401 | Auth failed | Refresh token, check key |
| 403 | Permission failed | Check Search Console owners |
| 429 | Too many requests | Back off and slow queue |
// Node submit with retry, plain logging
const { JWT } = require('google-auth-library');
async function publish(url, type) {
  const auth = new JWT({ keyFile: 'key.json', scopes: ['https://www.googleapis.com/auth/indexing'] });
  const token = await auth.getAccessToken();
  for (let i = 0; i < 5; i++) {
    const r = await fetch('https://indexing.googleapis.com/v3/urlNotifications:publish', {
      method: 'POST',
      headers: { 'Content-Type': 'application/json', Authorization: 'Bearer ' + token.token },
      body: JSON.stringify({ url, type })
    });
    console.log(r.status, await r.text().then(t => t.slice(0, 300)));
    if (r.status !== 429) break;
    await new Promise(x => setTimeout(x, 1000 * (2 ** i) + Math.random() * 500));
  }
}
Handling bursts after migrations, launches and sales
This section covers handling bursts after migrations, launches and sales in the context of indexing api rate limit. Launches and migrations create spikes that need staging over days, not minutes. We keep the advice practical for owners without a large SEO team. Each step below uses plain checks you can run with Search Console, server logs and a small script. The goal is steady progress you can measure in coverage reports, not a one time spike. Keep notes on what you change and when, so you can link indexing movement to specific fixes.
Google discovers most pages through crawl, not through a single submission. A submission is a hint that asks for a fresh look, but ranking and storage still depend on quality, uniqueness and site trust. That is why steady technical hygiene matters more than any one push. Keep response times low, avoid redirect chains, and return clear status codes. When the crawler can fetch quickly and without loops, each hint carries more weight and uses less of your daily allowance.
Sitemaps remain the backbone of discovery. A clean product or article sitemap lists only canonical, indexable URLs that return 200 and load quickly. Split large catalogs into chunks of 10,000 to 40,000 URLs, compress with gzip, and reference each chunk from a sitemap index. Update the lastmod field only when content truly changes. Submit the index in Search Console and keep it reachable. A tidy sitemap reduces wasted fetches and leaves room for priority pages.
Crawl budget is often misunderstood. For small sites it rarely limits indexing, but for catalogs with 50,000 to 500,000 URLs it shapes what gets visited each day. Facets, session parameters, internal search results and duplicate variants can trap crawlers in low value loops. Use robots rules to block filtered views, use canonical tags to consolidate variants, and link best sellers from the home page and category hubs. Fewer dead ends means faster visits to new and updated pages.
In practice, set a worker that pulls one URL at a time, sends the request with a 15 second timeout, and records status, latency and response snippet. On 200, mark done and continue. On 429, read Retry After, sleep for that period plus jitter, then halve the pull rate. On 403 or 401, pause the queue and alert, since retries will not fix auth. On 400, fix the payload and do not retry blindly. This small state machine keeps you under the ceiling even during busy catalog days.
If limits shape your plan, review safe bulk submission patterns for quota numbers and pacing examples.
- Step 1: Export the full URL list from your CMS or commerce platform with last change dates.
- Step 2: Join with Search Console coverage to flag Discovered, Crawled, Excluded and Indexed states.
- Step 3: Remove duplicates, 404s, noindex pages and non canonical variants from the submit set.
- Step 4: Sort by priority such as new, price change, availability change, then evergreen refresh.
- Step 5: Queue at a paced rate, log every response, and pause on repeated 429 or 403.
Code patterns for Python, Node and PHP with retry logic
This section covers code patterns for python, node and php with retry logic in the context of indexing api rate limit. Retry helpers in Python, Node and PHP share the same pattern of catch, wait and requeue. We keep the advice practical for owners without a large SEO team. Each step below uses plain checks you can run with Search Console, server logs and a small script. The goal is steady progress you can measure in coverage reports, not a one time spike. Keep notes on what you change and when, so you can link indexing movement to specific fixes.
Search Console verification is the gate for any Google submission. The service account that calls the API must be added as an Owner on the exact property, including the correct scheme and subdomain. Domain properties and URL prefix properties behave differently, so match the property you verify with the URLs you submit. If you see permission denied or 403, check sharing settings first, then OAuth scope, then key expiry. Most auth failures trace to a missed sharing step, not to code.
The Google Indexing API only documents JobPosting and BroadcastEvent pages, which covers job listings and livestream video. Many site owners still test it for product or article URLs, but that use is off label and results vary. Google may process the hint, ignore it, or throttle it. State this plainly to stakeholders. Use the API for eligible content first, and rely on sitemaps, internal links and IndexNow for broad coverage on other page types.
Google does not support IndexNow, so plan for two ecosystems. IndexNow notifies Bing, Yandex, Naver, Seznam and other partners that share the protocol, while Google relies on sitemaps, Search Console inspection and the Indexing API for eligible types. A practical setup sends product updates to both paths at publish time. One worker prepares the URL list, then one branch pings IndexNow endpoints and another branch queues Google notifications within quota. Coverage improves without double counting.
In practice, set a worker that pulls one URL at a time, sends the request with a 15 second timeout, and records status, latency and response snippet. On 200, mark done and continue. On 429, read Retry After, sleep for that period plus jitter, then halve the pull rate. On 403 or 401, pause the queue and alert, since retries will not fix auth. On 400, fix the payload and do not retry blindly. This small state machine keeps you under the ceiling even during busy catalog days.
Protocol specifics are covered in requesting indexing in Search Console if you need to confirm payload format or key handling.
| Signal | Meaning | Next step |
|---|---|---|
| 200 | Hint accepted | Continue at same pace |
| 400 | Bad request | Fix payload, do not blind retry |
| 401 | Auth failed | Refresh token, check key |
| 403 | Permission failed | Check Search Console owners |
| 429 | Too many requests | Back off and slow queue |
---
// Astro sitemap and feed wiring, runs at build time
import { getCollection } from 'astro:content';
const posts = await getCollection('blog');
const urls = posts.filter(p => !p.data.draft).map(p => ({ loc: '/blog/' + p.slug + '/', lastmod: p.data.updatedDate }));
---
<rss version="2.0">
  {urls.slice(0, 50).map(u => <item><link>{u.loc}</link></item>)}
</rss>
Recovering after repeated throttling without losing URLs
This section covers recovering after repeated throttling without losing urls in the context of indexing api rate limit. Pausing, deduplicating and resuming slowly restores trust with the endpoint. Use a written api retry strategy with capped attempts and jitter, and check api limits google pages in Cloud Console to confirm whether daily quota or per minute pacing caused the block. We keep the advice practical for owners without a large SEO team. Each step below uses plain checks you can run with Search Console, server logs and a small script. The goal is steady progress you can measure in coverage reports, not a one time spike. Keep notes on what you change and when, so you can link indexing movement to specific fixes.
Quotas shape every automation decision. Many projects start with about 200 publish requests per day for URL notifications, plus per minute limits that trigger 429 when bursts arrive. Track usage in Cloud Console under APIs and Services, set alerts at 60 percent and 85 percent, and log each publish with timestamp, URL, response code and notification type. When you know your burn rate by hour, you can pace jobs, defer low priority URLs and avoid midnight surprises.
A 429 means slow down, not try harder. Read the Retry After header when present, then wait with exponential backoff and jitter before retrying. A common pattern waits 2 seconds, then 4, then 8, then 16, with a small random addition to avoid synchronized retries. Cap retries at 4 or 5 and move the URL to a delayed queue after that. Hammering the endpoint during a limit only extends the block and burns log space.
A 403 usually points to permissions or scope. Confirm the service account email has Owner access in Search Console, confirm the OAuth scope includes the indexing scope, and confirm the JSON key file matches the active key in Cloud Console. Check clock skew on the server, since JWT auth fails when time drifts by more than a few minutes. Rotate keys on a schedule, store them in a secret manager, and never paste private keys into chat tools or shared docs.
In practice, set a worker that pulls one URL at a time, sends the request with a 15 second timeout, and records status, latency and response snippet. On 200, mark done and continue. On 429, read Retry After, sleep for that period plus jitter, then halve the pull rate. On 403 or 401, pause the queue and alert, since retries will not fix auth. On 400, fix the payload and do not retry blindly. This small state machine keeps you under the ceiling even during busy catalog days.
- Step 1: Export the full URL list from your CMS or commerce platform with last change dates.
- Step 2: Join with Search Console coverage to flag Discovered, Crawled, Excluded and Indexed states.
- Step 3: Remove duplicates, 404s, noindex pages and non canonical variants from the submit set.
- Step 4: Sort by priority such as new, price change, availability change, then evergreen refresh.
- Step 5: Queue at a paced rate, log every response, and pause on repeated 429 or 403.
Long term strategies to request more headroom
This section covers long term strategies to request more headroom in the context of indexing api rate limit. Quota increases, multi project hygiene and calmer publish cadence create long term room. We keep the advice practical for owners without a large SEO team. Each step below uses plain checks you can run with Search Console, server logs and a small script. The goal is steady progress you can measure in coverage reports, not a one time spike. Keep notes on what you change and when, so you can link indexing movement to specific fixes.
JWT failures look cryptic but follow a pattern. Invalid signature often means the wrong key file or a corrupted newline in the private key. Invalid grant often means the service account is disabled or the project never enabled the API. Failed to parse often means the token was truncated in logs or copied with extra spaces. Keep token lifetimes short, request a fresh access token per batch, and log the key ID without logging the secret. Small hygiene steps remove most auth noise.
Logging turns guesses into fixes. For each submission store the URL, notification type, HTTP status, response body snippet, latency and a correlation ID. Keep success and error logs separate so you can scan error rates by hour. Export daily counts to a sheet or dashboard that shows submits, 200 responses, 403 responses, 429 responses and remaining quota. When stakeholders ask why a product is not visible, you can point to exact evidence instead of general theories.
Internal linking does more for indexing than most teams expect. New URLs that sit four clicks from the home page may wait days for a visit, while URLs linked from a popular category or a recent posts block get visited quickly. Add new products to relevant category pages, link related items, and keep pagination crawlable with plain anchors. Avoid loading key links only through scripts that require clicks. Simple, stable links help both Google and IndexNow driven crawlers find changes fast.
In practice, set a worker that pulls one URL at a time, sends the request with a 15 second timeout, and records status, latency and response snippet. On 200, mark done and continue. On 429, read Retry After, sleep for that period plus jitter, then halve the pull rate. On 403 or 401, pause the queue and alert, since retries will not fix auth. On 400, fix the payload and do not retry blindly. This small state machine keeps you under the ceiling even during busy catalog days.
| Signal | Meaning | Next step |
|---|---|---|
| 200 | Hint accepted | Continue at same pace |
| 400 | Bad request | Fix payload, do not blind retry |
| 401 | Auth failed | Refresh token, check key |
| 403 | Permission failed | Check Search Console owners |
| 429 | Too many requests | Back off and slow queue |
FAQ
What is the difference between quota and rate limit?
Quota caps total calls in a day, rate limits cap speed per minute or per second. When dashboards show rate limit exceeded after a burst, the cause is api throttling on indexing api requests per minute rather than spent daily quota. Check Cloud Console graphs. A flat block all day points to daily quota, while short bursts that clear after pauses point to per minute throttling.
What are the default limits?
Many projects see about 200 publish requests per day for URL notifications, with per minute throttles that vary. Metadata calls count separately. Always confirm in your own Console, since history and policy can shift numbers. Design queues below the observed ceiling, not at it.
How should I handle Retry After?
Read the header value in seconds, sleep for that period plus a small random jitter, then retry once. If 429 persists, halve your send rate and extend the pause. After 4 or 5 retries, move the URL to a delayed queue and continue with other work.
What backoff pattern works well?
Exponential backoff with jitter works well. Wait 2 seconds, then 4, then 8, then 16, each plus up to 1 second of random delay. This api retry strategy is the standard indexing api 429 fix before deeper changes. Cap attempts, log each wait, and track how often backoff triggers. Frequent triggers mean the base rate is too high.
Should I prioritize URLs under limits?
Yes. Send new eligible pages, price and availability changes, and removals first. Defer evergreen refreshes and low traffic variants. Tag each queued URL with priority and age so recovery serves business needs instead of submission order.
How do I avoid limits during launches?
Stage large changes over days, pre clean sitemaps, and schedule submits outside peak crawl hours. Set a per hour cap in the worker, add alerts at 60 and 85 percent of quota, and keep a pause switch. Test the pipeline on a small batch before the full launch.
Sources
- https://developer.mozilla.org/en-US/docs/Web/HTTP/Status
- https://developers.google.com/search/docs/crawling-indexing/request-indexing
- https://developers.google.com/search/docs/crawling-indexing/sitemaps/build-sitemap