What Replaced Fetch as Google? Modern Indexing Test Tools

Fetch as Google was a familiar button for a quick crawl check, but it has been retired for years. Many guides still mention it, which confuses site owners who cannot find it in Search Console. This article is for SEOs, publishers, and developers who need a clear fetch as google alternative toolkit for testing rendering, crawl access, and index eligibility today. You will learn what replaced the old fetch, how to use URL Inspection live tests, which companion checks cover structured data and performance, and how to run a repeatable workflow for new and updated pages. The focus keyword fetch as google alternative appears early to set intent and keep the steps practical.
Key takeaways
- Fetch as Google is retired, URL Inspection live test is the direct replacement.
- Pair single URL tests with headers, logs, and sitewide crawls for patterns.
- Follow a gated workflow from status to rendering to canonicals before resubmits.
- Choose tools by question to keep debugging fast and focused.
- Why Fetch as Google was retired and which fetch as google alternative replaced it
- URL Inspection tool: live test, coverage, and rendering checks
- Rich Results Test, Mobile Friendly Test, and PageSpeed signals
- Crawl stats, server logs, and header checks for deeper tests
- Third party crawlers and how they complement Search Console
- A practical test workflow for new and updated pages
- Choosing the right tool for each indexing question
- FAQ
- Sources
- Further reading
 <!-- IMAGE-PROMPT cover: 1200x630, DependsIt brand, deep charcoal #121212 background, vibrant mint #22E3B0 accent glow, thin node-network line art, Clash Display style bold heading space on left, General Sans clean labels, subject: fetch as google alternative cover for site owners, flat vector, high contrast, accessible, no photorealistic faces, no text smaller than 24px, no em dash in rendered text, export PNG then cwebp -q 82 to WEBP -->
Why Fetch as Google was retired and which fetch as google alternative replaced it
Fetch as Google gave a simple fetch and render check inside old Search Console. For fetch as google alternative workflows, the retirement moved testing into URL Inspection with live tests, richer coverage details, and closer ties to the current index. Rendering pipelines, mobile first indexing, and JavaScript heavy pages made the old single shot fetch less useful. This section explains the timeline, what the old button actually tested, which parts carried over, and why modern checks cover crawl access, rendering, canonicals, and page experience in one place instead of a bare fetch.
To make progress on why fetch as google was retired and what changed, start with live evidence rather than assumptions. Open the URL in a clean browser session, view source, and compare it with the rendered DOM. Note the title, meta robots, canonical link, headings, and main body length in both views. Then fetch response headers to confirm status code, content type, X Robots Tag, cache directives, and redirect chain length. For fetch as google alternative, these first facts decide whether deeper work is needed or whether a single header or tag explains the symptom. Record the date, template name, and test URLs so later changes can be tied to outcomes without guesswork.
Practical checks for why fetch as google was retired and what changed work best as a short checklist with owners and dates. Confirm crawl access in robots.txt for the exact path and user agent, confirm index permission in meta and headers, confirm the canonical target returns 200 and allows indexing, confirm sitemap inclusion only for preferred URLs, and confirm at least a few relevant internal inlinks from indexed hubs. For fetch as google alternative, each check takes minutes but together they catch most blocks. Log which check failed for each sample so the repair targets the true source instead of applying broad changes that risk new issues.
Checklist for why fetch as google was retired and what changed:
- Confirm live status, headers, and rendered output on two samples from this template.
- Compare Search Console samples with crawl exports grouped by template and path.
- Align sitemap entries, internal anchors, and canonical targets to one preferred URL form.
- Fix the template or setting once, then retest across post types and archives.
- Purge page cache and edge cache, then recheck logged out HTML and headers.
- Log the change with dates and watch valid indexed counts for two weeks.
| Check for fetch as google alternative | What to look for | Next step |
|---|---|---|
| --- | --- | --- |
| Crawl access | robots result and log fetch rate | Narrow the exact disallow or allow pattern |
|---|---|---|
| Index permission | meta robots and X Robots Tag | Remove noindex from the true source layer |
| Canonical clarity | declared versus selected URL | Point all cues to one 200 indexable target |
|---|---|---|
| Internal support | inlink count and click depth | Add hub and contextual links with clear anchors |
Example: a site working on fetch as google alternative found that why fetch as google was retired and what changed affected one template more than others. The team listed fifty sample URLs, added template and inlink columns, and saw that archive pages carried the same canonical as single posts while receiving almost no internal links. They updated the template so archives self reference only when they add unique value, added three contextual links from related hubs to priority singles, cleaned the sitemap to preferred URLs only, and purged cache. Live tests then showed consistent canonicals, logs showed steadier fetching of the priority section, and the valid indexed trend rose without bulk resubmits. For more context on adjacent coverage states, see Google Indexing API vs Request Indexing in Search Console: Which Is Faster which explains how discovery and crawl states connect to this fix.
Next, widen the lens from one URL to its template group. For fetch as google alternative, single page fixes rarely move coverage because the same include, plugin, or layout rule affects hundreds of pages. Export Search Console samples for the relevant status, add columns for template, word count, inlink count, canonical target, and sitemap presence, then sort by template. When why fetch as google was retired and what changed clusters on one layout, the fix belongs in code or settings, not in the editor. When it spreads across layouts, look at sitewide signals such as navigation depth, crawl budget pressure, or recent deploy dates that shifted many pages at once.
Do not overlook rendering and performance. For fetch as google alternative, JavaScript that injects main content late, lazy loads critical links, or blocks CSS and scripts can make a healthy page look thin to crawlers. Test raw versus rendered word counts, list blocked resources reported in live tests, and confirm that canonicals, hreflang, and structured data appear in rendered HTML as well as source. Compress images, stabilize response times, and ensure the edge cache serves bots the same HTML as browsers. Faster stable rendering helps every other fix for why fetch as google was retired and what changed get noticed sooner.
curl -I https://example.com/test-urlRemember that fetch as google retired years ago, so old screenshots no longer match Search Console. The direct fetch tool replacement today is URL Inspection with a live test that shows crawl permission, fetch result, and canonical selection.
URL Inspection tool: live test, coverage, and rendering checks
URL Inspection is now the primary replacement. For fetch as google alternative needs, it shows whether the URL is in the index, the declared and Google selected canonical, last crawl time, crawl allowed status, page fetch result, and index permission. The live test fetches the current page rather than the last indexed version and reports rendered HTML, console messages, and blocked resources. This section walks through each field, how to read warnings versus errors, and when a passing live test still leaves indexing blocked by quality, duplication, or weak signals.
Next, widen the lens from one URL to its template group. For fetch as google alternative, single page fixes rarely move coverage because the same include, plugin, or layout rule affects hundreds of pages. Export Search Console samples for the relevant status, add columns for template, word count, inlink count, canonical target, and sitemap presence, then sort by template. When url inspection tool: live test, coverage, and rendering checks clusters on one layout, the fix belongs in code or settings, not in the editor. When it spreads across layouts, look at sitewide signals such as navigation depth, crawl budget pressure, or recent deploy dates that shifted many pages at once.
Content quality still decides many close calls. For fetch as google alternative, compare the thin or duplicated page against indexed competitors on specificity, steps, examples, data, and intent fit. Add concrete details that a crawler can distinguish, such as exact procedures, error strings, thresholds, timelines, and follow up actions. Keep titles and H1s distinct across the section, tighten intros that repeat the same boilerplate, and remove auto generated archives that compete with priority pages. When url inspection tool: live test, coverage, and rendering checks improves uniqueness and intent match, Google has a clearer reason to keep the preferred URL in the index.
Checklist for url inspection tool: live test, coverage, and rendering checks:
- Confirm live status, headers, and rendered output on two samples from this template.
- Compare Search Console samples with crawl exports grouped by template and path.
- Align sitemap entries, internal anchors, and canonical targets to one preferred URL form.
- Fix the template or setting once, then retest across post types and archives.
- Purge page cache and edge cache, then recheck logged out HTML and headers.
- Log the change with dates and watch valid indexed counts for two weeks.
| Check for fetch as google alternative | What to look for | Next step |
|---|---|---|
| --- | --- | --- |
| Crawl access | robots result and log fetch rate | Narrow the exact disallow or allow pattern |
|---|---|---|
| Index permission | meta robots and X Robots Tag | Remove noindex from the true source layer |
| Canonical clarity | declared versus selected URL | Point all cues to one 200 indexable target |
|---|---|---|
| Internal support | inlink count and click depth | Add hub and contextual links with clear anchors |
Example: a site working on fetch as google alternative found that url inspection tool: live test, coverage, and rendering checks affected one template more than others. The team listed fifty sample URLs, added template and inlink columns, and saw that archive pages carried the same canonical as single posts while receiving almost no internal links. They updated the template so archives self reference only when they add unique value, added three contextual links from related hubs to priority singles, cleaned the sitemap to preferred URLs only, and purged cache. Live tests then showed consistent canonicals, logs showed steadier fetching of the priority section, and the valid indexed trend rose without bulk resubmits. For more context on adjacent coverage states, see our guide on Google Indexing API vs Request Indexing in Search Console: Which Is Faster which explains how discovery and crawl states connect to this fix.
Then align the supporting signals that Google weighs alongside the main tag or directive. For fetch as google alternative, sitemaps should list only canonical 200 URLs with accurate lastmod, internal links should point to the same canonical variant with descriptive anchors, and alternate cues such as hreflang, pagination, or feed links should agree rather than compete. Mixed cues force Google to choose, which delays indexing. Pick one preferred URL form with consistent protocol, host, trailing slash, and parameter handling, update templates and feeds to emit it, and remove stale variants from sitemaps so crawlers spend time on pages that can actually be indexed.
Rollout discipline protects gains. For fetch as google alternative, back up templates and settings, change one layer at a time, and keep a simple log with template, change, date, and sample URLs. After deploy, clear caches, retest live output, and compare before and after exports rather than relying on memory. Share the log with editors and developers so no one reintroduces the old pattern during the next theme update. When url inspection tool: live test, coverage, and rendering checks is fixed at the template level with monitoring in place, coverage usually stays stable through future releases.
 <!-- IMAGE-PROMPT diagram-01: 1600px max, DependsIt brand mint #22E3B0 on charcoal #121212, node-network line art, Clash Display style headings, General Sans clean labels, subject: fetch as google alternative pipeline diagram from discovery through crawl to index, flat vector, accessible, no em dash -->
curl -I https://example.com/test-urlUse the live url test for single URL checks when you need current HTML rather than the last indexed version. Pair it with a rendering test search console review that lists blocked resources and shows whether main content appears after scripts run.
Rich Results Test, Mobile Friendly Test, and PageSpeed signals
Index eligibility is more than fetch success. For fetch as google alternative checks, structured data validity, mobile usability, and performance signals affect how pages are understood and prioritized. The Rich Results Test validates eligible markup against live HTML. Mobile checks confirm viewport, tap targets, and resource access for smartphone crawlers. PageSpeed data flags slow templates that reduce crawl budget. This section shows how to run the three tests together, which failures actually block indexing, and which only affect presentation or ranking.
Then align the supporting signals that Google weighs alongside the main tag or directive. For fetch as google alternative, sitemaps should list only canonical 200 URLs with accurate lastmod, internal links should point to the same canonical variant with descriptive anchors, and alternate cues such as hreflang, pagination, or feed links should agree rather than compete. Mixed cues force Google to choose, which delays indexing. Pick one preferred URL form with consistent protocol, host, trailing slash, and parameter handling, update templates and feeds to emit it, and remove stale variants from sitemaps so crawlers spend time on pages that can actually be indexed.
Do not overlook rendering and performance. For fetch as google alternative, JavaScript that injects main content late, lazy loads critical links, or blocks CSS and scripts can make a healthy page look thin to crawlers. Test raw versus rendered word counts, list blocked resources reported in live tests, and confirm that canonicals, hreflang, and structured data appear in rendered HTML as well as source. Compress images, stabilize response times, and ensure the edge cache serves bots the same HTML as browsers. Faster stable rendering helps every other fix for rich results test, mobile friendly test, and pagespeed signals get noticed sooner.
Checklist for rich results test, mobile friendly test, and pagespeed signals:
- Confirm live status, headers, and rendered output on two samples from this template.
- Compare Search Console samples with crawl exports grouped by template and path.
- Align sitemap entries, internal anchors, and canonical targets to one preferred URL form.
- Fix the template or setting once, then retest across post types and archives.
- Purge page cache and edge cache, then recheck logged out HTML and headers.
- Log the change with dates and watch valid indexed counts for two weeks.
| Check for fetch as google alternative | What to look for | Next step |
|---|---|---|
| --- | --- | --- |
| Crawl access | robots result and log fetch rate | Narrow the exact disallow or allow pattern |
|---|---|---|
| Index permission | meta robots and X Robots Tag | Remove noindex from the true source layer |
| Canonical clarity | declared versus selected URL | Point all cues to one 200 indexable target |
|---|---|---|
| Internal support | inlink count and click depth | Add hub and contextual links with clear anchors |
Example: a site working on fetch as google alternative found that rich results test, mobile friendly test, and pagespeed signals affected one template more than others. The team listed fifty sample URLs, added template and inlink columns, and saw that archive pages carried the same canonical as single posts while receiving almost no internal links. They updated the template so archives self reference only when they add unique value, added three contextual links from related hubs to priority singles, cleaned the sitemap to preferred URLs only, and purged cache. Live tests then showed consistent canonicals, logs showed steadier fetching of the priority section, and the valid indexed trend rose without bulk resubmits. For more context on adjacent coverage states, see our guide on Google Indexing API vs Request Indexing in Search Console: Which Is Faster which explains how discovery and crawl states connect to this fix.
Finally, validate in small loops and track trends. For fetch as google alternative, fix staging first, deploy to production, purge page and edge caches, and retest headers and source on live URLs while logged out. Run URL Inspection live tests on two to three samples per template, not on thousands of URLs. Note last crawl dates and canonical selection, then watch the Pages report for the section over one to two weeks. Stable templates plus steady internal links usually move the valid count before any single URL is manually resubmitted. If movement stalls, revisit rendering, duplication, and depth before adding more requests.
Practical checks for rich results test, mobile friendly test, and pagespeed signals work best as a short checklist with owners and dates. Confirm crawl access in robots.txt for the exact path and user agent, confirm index permission in meta and headers, confirm the canonical target returns 200 and allows indexing, confirm sitemap inclusion only for preferred URLs, and confirm at least a few relevant internal inlinks from indexed hubs. For fetch as google alternative, each check takes minutes but together they catch most blocks. Log which check failed for each sample so the repair targets the true source instead of applying broad changes that risk new issues.
curl -I https://example.com/test-urlA simple render test tool check compares raw source against rendered DOM for titles, links, and canonicals. To test rendering google sees, run the live test, inspect console messages, and confirm key content loads without user actions or long delays.
Crawl stats, server logs, and header checks for deeper tests
When Search Console looks fine but pages still lag, deeper data helps. For fetch as google alternative diagnosis, crawl stats reveal host load, response codes, and fetch purpose over time, while server logs show real Googlebot hits per path. Header checks confirm status codes, canonical link headers, X Robots Tag, and cache behavior as bots see them. This section explains how to pull a clean header sample, how to filter logs for Googlebot IPs and user agents, and how to match log gaps with deploy dates, downtime, or robots changes.
Finally, validate in small loops and track trends. For fetch as google alternative, fix staging first, deploy to production, purge page and edge caches, and retest headers and source on live URLs while logged out. Run URL Inspection live tests on two to three samples per template, not on thousands of URLs. Note last crawl dates and canonical selection, then watch the Pages report for the section over one to two weeks. Stable templates plus steady internal links usually move the valid count before any single URL is manually resubmitted. If movement stalls, revisit rendering, duplication, and depth before adding more requests.
Rollout discipline protects gains. For fetch as google alternative, back up templates and settings, change one layer at a time, and keep a simple log with template, change, date, and sample URLs. After deploy, clear caches, retest live output, and compare before and after exports rather than relying on memory. Share the log with editors and developers so no one reintroduces the old pattern during the next theme update. When crawl stats, server logs, and header checks for deeper tests is fixed at the template level with monitoring in place, coverage usually stays stable through future releases.
Checklist for crawl stats, server logs, and header checks for deeper tests:
- Confirm live status, headers, and rendered output on two samples from this template.
- Compare Search Console samples with crawl exports grouped by template and path.
- Align sitemap entries, internal anchors, and canonical targets to one preferred URL form.
- Fix the template or setting once, then retest across post types and archives.
- Purge page cache and edge cache, then recheck logged out HTML and headers.
- Log the change with dates and watch valid indexed counts for two weeks.
| Check for fetch as google alternative | What to look for | Next step |
|---|---|---|
| --- | --- | --- |
| Crawl access | robots result and log fetch rate | Narrow the exact disallow or allow pattern |
|---|---|---|
| Index permission | meta robots and X Robots Tag | Remove noindex from the true source layer |
| Canonical clarity | declared versus selected URL | Point all cues to one 200 indexable target |
|---|---|---|
| Internal support | inlink count and click depth | Add hub and contextual links with clear anchors |
Example: a site working on fetch as google alternative found that crawl stats, server logs, and header checks for deeper tests affected one template more than others. The team listed fifty sample URLs, added template and inlink columns, and saw that archive pages carried the same canonical as single posts while receiving almost no internal links. They updated the template so archives self reference only when they add unique value, added three contextual links from related hubs to priority singles, cleaned the sitemap to preferred URLs only, and purged cache. Live tests then showed consistent canonicals, logs showed steadier fetching of the priority section, and the valid indexed trend rose without bulk resubmits. For more context on adjacent coverage states, see our guide on Google Indexing API vs Request Indexing in Search Console: Which Is Faster which explains how discovery and crawl states connect to this fix.
To make progress on crawl stats, server logs, and header checks for deeper tests, start with live evidence rather than assumptions. Open the URL in a clean browser session, view source, and compare it with the rendered DOM. Note the title, meta robots, canonical link, headings, and main body length in both views. Then fetch response headers to confirm status code, content type, X Robots Tag, cache directives, and redirect chain length. For fetch as google alternative, these first facts decide whether deeper work is needed or whether a single header or tag explains the symptom. Record the date, template name, and test URLs so later changes can be tied to outcomes without guesswork.
Content quality still decides many close calls. For fetch as google alternative, compare the thin or duplicated page against indexed competitors on specificity, steps, examples, data, and intent fit. Add concrete details that a crawler can distinguish, such as exact procedures, error strings, thresholds, timelines, and follow up actions. Keep titles and H1s distinct across the section, tighten intros that repeat the same boilerplate, and remove auto generated archives that compete with priority pages. When crawl stats, server logs, and header checks for deeper tests improves uniqueness and intent match, Google has a clearer reason to keep the preferred URL in the index.
curl -I https://example.com/test-urlWhen you need to fetch googlebot behavior beyond one URL, combine header fetches, crawl stats, and server logs. These modern seo testing tools together reveal status codes, redirect chains, and real fetch frequency per template.
Third party crawlers and how they complement Search Console
Desktop crawlers do what Search Console cannot. For fetch as google alternative workflows, tools that crawl thousands of URLs surface template patterns in canonicals, titles, status codes, and inlink counts that single URL tests miss. They also render JavaScript and compare raw versus rendered HTML. This section compares single URL tests with sitewide crawls, shows which crawl settings mirror Googlebot most closely, and explains how to export grouped issues by template so one fix clears hundreds of warnings instead of chasing URLs one by one.
To make progress on third party crawlers and how they complement search console, start with live evidence rather than assumptions. Open the URL in a clean browser session, view source, and compare it with the rendered DOM. Note the title, meta robots, canonical link, headings, and main body length in both views. Then fetch response headers to confirm status code, content type, X Robots Tag, cache directives, and redirect chain length. For fetch as google alternative, these first facts decide whether deeper work is needed or whether a single header or tag explains the symptom. Record the date, template name, and test URLs so later changes can be tied to outcomes without guesswork.
Practical checks for third party crawlers and how they complement search console work best as a short checklist with owners and dates. Confirm crawl access in robots.txt for the exact path and user agent, confirm index permission in meta and headers, confirm the canonical target returns 200 and allows indexing, confirm sitemap inclusion only for preferred URLs, and confirm at least a few relevant internal inlinks from indexed hubs. For fetch as google alternative, each check takes minutes but together they catch most blocks. Log which check failed for each sample so the repair targets the true source instead of applying broad changes that risk new issues.
Checklist for third party crawlers and how they complement search console:
- Confirm live status, headers, and rendered output on two samples from this template.
- Compare Search Console samples with crawl exports grouped by template and path.
- Align sitemap entries, internal anchors, and canonical targets to one preferred URL form.
- Fix the template or setting once, then retest across post types and archives.
- Purge page cache and edge cache, then recheck logged out HTML and headers.
- Log the change with dates and watch valid indexed counts for two weeks.
| Check for fetch as google alternative | What to look for | Next step |
|---|---|---|
| --- | --- | --- |
| Crawl access | robots result and log fetch rate | Narrow the exact disallow or allow pattern |
|---|---|---|
| Index permission | meta robots and X Robots Tag | Remove noindex from the true source layer |
| Canonical clarity | declared versus selected URL | Point all cues to one 200 indexable target |
|---|---|---|
| Internal support | inlink count and click depth | Add hub and contextual links with clear anchors |
Example: a site working on fetch as google alternative found that third party crawlers and how they complement search console affected one template more than others. The team listed fifty sample URLs, added template and inlink columns, and saw that archive pages carried the same canonical as single posts while receiving almost no internal links. They updated the template so archives self reference only when they add unique value, added three contextual links from related hubs to priority singles, cleaned the sitemap to preferred URLs only, and purged cache. Live tests then showed consistent canonicals, logs showed steadier fetching of the priority section, and the valid indexed trend rose without bulk resubmits. For more context on adjacent coverage states, see our guide on Google Indexing API vs Request Indexing in Search Console: Which Is Faster which explains how discovery and crawl states connect to this fix.
Next, widen the lens from one URL to its template group. For fetch as google alternative, single page fixes rarely move coverage because the same include, plugin, or layout rule affects hundreds of pages. Export Search Console samples for the relevant status, add columns for template, word count, inlink count, canonical target, and sitemap presence, then sort by template. When third party crawlers and how they complement search console clusters on one layout, the fix belongs in code or settings, not in the editor. When it spreads across layouts, look at sitewide signals such as navigation depth, crawl budget pressure, or recent deploy dates that shifted many pages at once.
Do not overlook rendering and performance. For fetch as google alternative, JavaScript that injects main content late, lazy loads critical links, or blocks CSS and scripts can make a healthy page look thin to crawlers. Test raw versus rendered word counts, list blocked resources reported in live tests, and confirm that canonicals, hreflang, and structured data appear in rendered HTML as well as source. Compress images, stabilize response times, and ensure the edge cache serves bots the same HTML as browsers. Faster stable rendering helps every other fix for third party crawlers and how they complement search console get noticed sooner.
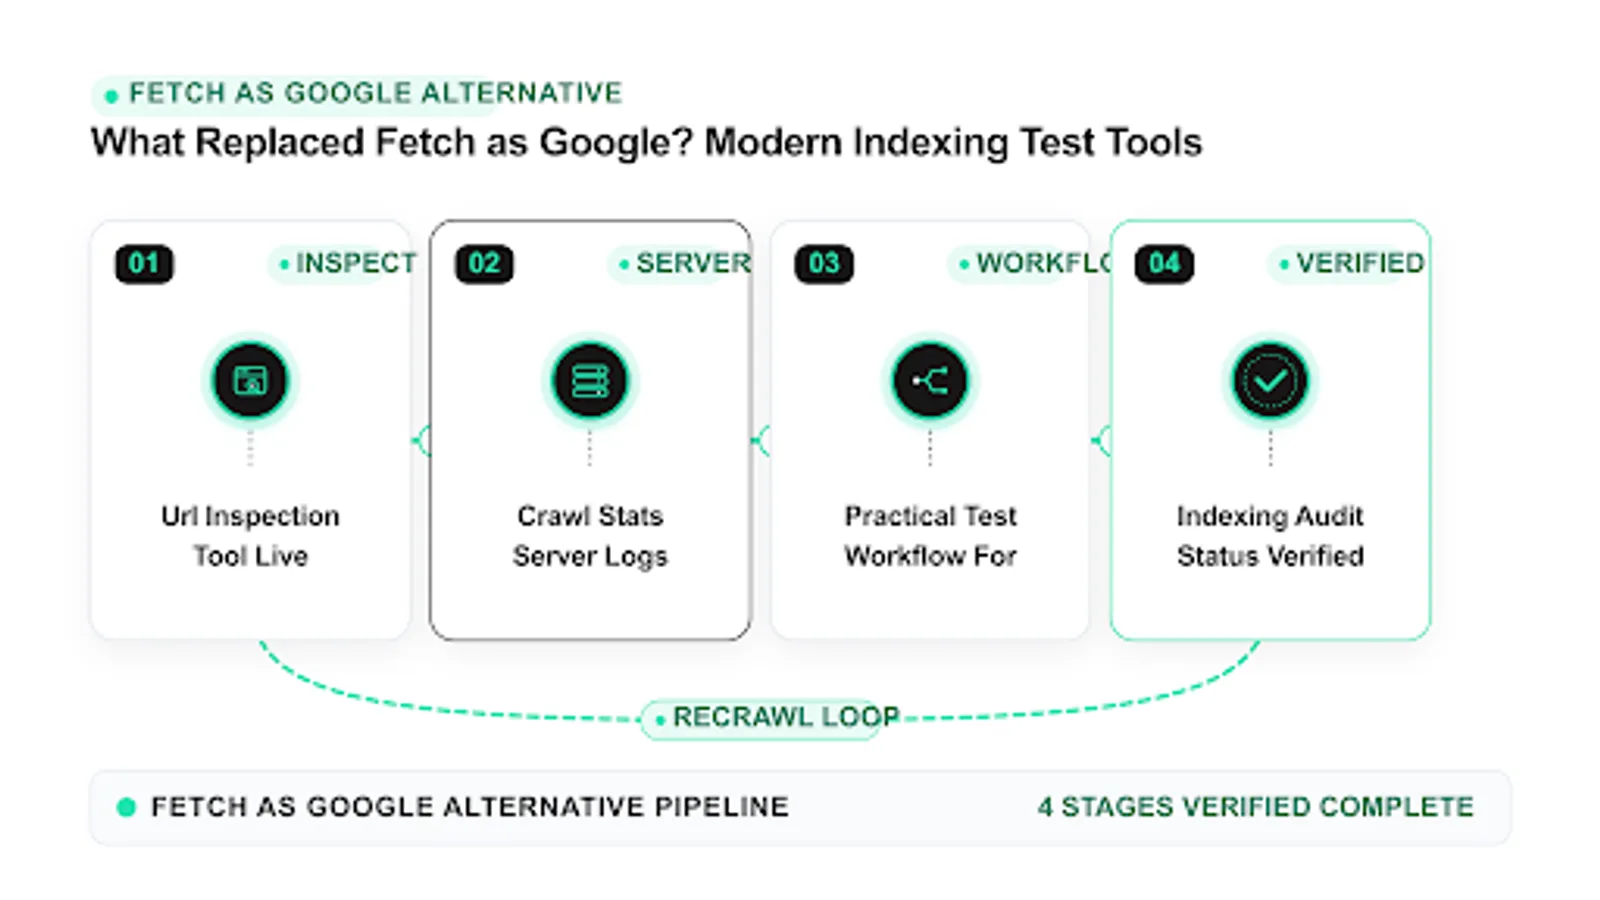 <!-- IMAGE-PROMPT workflow-02: 1600px max, DependsIt brand mint #22E3B0 on charcoal #121212 or white, node-network line art, Clash Display style headings, General Sans clean labels, subject: fetch as google alternative remediation workflow from audit to fix to monitoring, flat vector, accessible, no em dash -->
curl -I https://example.com/test-urlThink of URL Inspection plus validators as a complete fetch and render alternative for daily work. Keep the steps in a short checklist so any teammate can repeat the same sequence on new and updated pages.
A practical test workflow for new and updated pages
Order matters when testing. For fetch as google alternative routines, start with status and headers, then robots access, then rendered content checks, then canonical and sitemap alignment, then structured data and mobile checks, and only then a live URL Inspection test on a small sample. This section gives a repeatable sequence for launches and edits, with pass criteria for each gate. It shows what to log per URL, how to decide between fixing templates versus single pages, and when to wait for the next crawl cycle instead of retesting every hour.
Next, widen the lens from one URL to its template group. For fetch as google alternative, single page fixes rarely move coverage because the same include, plugin, or layout rule affects hundreds of pages. Export Search Console samples for the relevant status, add columns for template, word count, inlink count, canonical target, and sitemap presence, then sort by template. When a practical test workflow for new and updated pages clusters on one layout, the fix belongs in code or settings, not in the editor. When it spreads across layouts, look at sitewide signals such as navigation depth, crawl budget pressure, or recent deploy dates that shifted many pages at once.
Content quality still decides many close calls. For fetch as google alternative, compare the thin or duplicated page against indexed competitors on specificity, steps, examples, data, and intent fit. Add concrete details that a crawler can distinguish, such as exact procedures, error strings, thresholds, timelines, and follow up actions. Keep titles and H1s distinct across the section, tighten intros that repeat the same boilerplate, and remove auto generated archives that compete with priority pages. When a practical test workflow for new and updated pages improves uniqueness and intent match, Google has a clearer reason to keep the preferred URL in the index.
Checklist for a practical test workflow for new and updated pages:
- Confirm live status, headers, and rendered output on two samples from this template.
- Compare Search Console samples with crawl exports grouped by template and path.
- Align sitemap entries, internal anchors, and canonical targets to one preferred URL form.
- Fix the template or setting once, then retest across post types and archives.
- Purge page cache and edge cache, then recheck logged out HTML and headers.
- Log the change with dates and watch valid indexed counts for two weeks.
| Check for fetch as google alternative | What to look for | Next step |
|---|---|---|
| --- | --- | --- |
| Crawl access | robots result and log fetch rate | Narrow the exact disallow or allow pattern |
|---|---|---|
| Index permission | meta robots and X Robots Tag | Remove noindex from the true source layer |
| Canonical clarity | declared versus selected URL | Point all cues to one 200 indexable target |
|---|---|---|
| Internal support | inlink count and click depth | Add hub and contextual links with clear anchors |
Example: a site working on fetch as google alternative found that a practical test workflow for new and updated pages affected one template more than others. The team listed fifty sample URLs, added template and inlink columns, and saw that archive pages carried the same canonical as single posts while receiving almost no internal links. They updated the template so archives self reference only when they add unique value, added three contextual links from related hubs to priority singles, cleaned the sitemap to preferred URLs only, and purged cache. Live tests then showed consistent canonicals, logs showed steadier fetching of the priority section, and the valid indexed trend rose without bulk resubmits. For more context on adjacent coverage states, see our guide on Google Indexing API vs Request Indexing in Search Console: Which Is Faster which explains how discovery and crawl states connect to this fix.
Then align the supporting signals that Google weighs alongside the main tag or directive. For fetch as google alternative, sitemaps should list only canonical 200 URLs with accurate lastmod, internal links should point to the same canonical variant with descriptive anchors, and alternate cues such as hreflang, pagination, or feed links should agree rather than compete. Mixed cues force Google to choose, which delays indexing. Pick one preferred URL form with consistent protocol, host, trailing slash, and parameter handling, update templates and feeds to emit it, and remove stale variants from sitemaps so crawlers spend time on pages that can actually be indexed.
Rollout discipline protects gains. For fetch as google alternative, back up templates and settings, change one layer at a time, and keep a simple log with template, change, date, and sample URLs. After deploy, clear caches, retest live output, and compare before and after exports rather than relying on memory. Share the log with editors and developers so no one reintroduces the old pattern during the next theme update. When a practical test workflow for new and updated pages is fixed at the template level with monitoring in place, coverage usually stays stable through future releases.
curl -I https://example.com/test-urlChoosing the right tool for each indexing question
Different questions need different tools. For fetch as google alternative decisions, use URL Inspection for is this URL indexed and can it be indexed now, Rich Results Test for markup eligibility, header fetches for status and robots signals, logs and crawl stats for frequency and budget questions, and sitewide crawls for pattern questions. This section provides a simple decision map that routes common symptoms to the fastest test. It helps teams avoid running every tool on every URL and keeps debugging time focused on the check most likely to reveal the block.
Then align the supporting signals that Google weighs alongside the main tag or directive. For fetch as google alternative, sitemaps should list only canonical 200 URLs with accurate lastmod, internal links should point to the same canonical variant with descriptive anchors, and alternate cues such as hreflang, pagination, or feed links should agree rather than compete. Mixed cues force Google to choose, which delays indexing. Pick one preferred URL form with consistent protocol, host, trailing slash, and parameter handling, update templates and feeds to emit it, and remove stale variants from sitemaps so crawlers spend time on pages that can actually be indexed.
Do not overlook rendering and performance. For fetch as google alternative, JavaScript that injects main content late, lazy loads critical links, or blocks CSS and scripts can make a healthy page look thin to crawlers. Test raw versus rendered word counts, list blocked resources reported in live tests, and confirm that canonicals, hreflang, and structured data appear in rendered HTML as well as source. Compress images, stabilize response times, and ensure the edge cache serves bots the same HTML as browsers. Faster stable rendering helps every other fix for choosing the right tool for each indexing question get noticed sooner.
Checklist for choosing the right tool for each indexing question:
- Confirm live status, headers, and rendered output on two samples from this template.
- Compare Search Console samples with crawl exports grouped by template and path.
- Align sitemap entries, internal anchors, and canonical targets to one preferred URL form.
- Fix the template or setting once, then retest across post types and archives.
- Purge page cache and edge cache, then recheck logged out HTML and headers.
- Log the change with dates and watch valid indexed counts for two weeks.
| Check for fetch as google alternative | What to look for | Next step |
|---|---|---|
| --- | --- | --- |
| Crawl access | robots result and log fetch rate | Narrow the exact disallow or allow pattern |
|---|---|---|
| Index permission | meta robots and X Robots Tag | Remove noindex from the true source layer |
| Canonical clarity | declared versus selected URL | Point all cues to one 200 indexable target |
|---|---|---|
| Internal support | inlink count and click depth | Add hub and contextual links with clear anchors |
Example: a site working on fetch as google alternative found that choosing the right tool for each indexing question affected one template more than others. The team listed fifty sample URLs, added template and inlink columns, and saw that archive pages carried the same canonical as single posts while receiving almost no internal links. They updated the template so archives self reference only when they add unique value, added three contextual links from related hubs to priority singles, cleaned the sitemap to preferred URLs only, and purged cache. Live tests then showed consistent canonicals, logs showed steadier fetching of the priority section, and the valid indexed trend rose without bulk resubmits. For more context on adjacent coverage states, see our guide on Google Indexing API vs Request Indexing in Search Console: Which Is Faster which explains how discovery and crawl states connect to this fix.
Finally, validate in small loops and track trends. For fetch as google alternative, fix staging first, deploy to production, purge page and edge caches, and retest headers and source on live URLs while logged out. Run URL Inspection live tests on two to three samples per template, not on thousands of URLs. Note last crawl dates and canonical selection, then watch the Pages report for the section over one to two weeks. Stable templates plus steady internal links usually move the valid count before any single URL is manually resubmitted. If movement stalls, revisit rendering, duplication, and depth before adding more requests.
Practical checks for choosing the right tool for each indexing question work best as a short checklist with owners and dates. Confirm crawl access in robots.txt for the exact path and user agent, confirm index permission in meta and headers, confirm the canonical target returns 200 and allows indexing, confirm sitemap inclusion only for preferred URLs, and confirm at least a few relevant internal inlinks from indexed hubs. For fetch as google alternative, each check takes minutes but together they catch most blocks. Log which check failed for each sample so the repair targets the true source instead of applying broad changes that risk new issues.
curl -I https://example.com/test-urlFAQ
What replaced Fetch as Google in Search Console?
URL Inspection with its live test is the direct replacement. Enter any URL in the property, run Inspect, then choose Test Live URL to fetch the current page as Google sees it. The report shows crawl permission, fetch result, index permission, declared and selected canonical, and rendered issues. For single page checks this covers what Fetch as Google did plus canonical and coverage context. Use sitewide crawlers and logs alongside it when you need patterns rather than one URL result.
Since fetch as google retired, URL Inspection is the supported path for single URL checks. This fetch tool replacement shows crawl permission, index permission, and canonicals in one report for faster triage.
Can I still fetch a page as Googlebot without Search Console access?
You can approximate parts of it. Header fetches with curl show status, redirects, and robots headers. Mobile and rich result validators test rendering and markup without property access. Desktop crawlers with Googlebot user agent settings reveal template issues. What you cannot see without access is the property specific index status, last crawl time, and coverage details. For client work, request temporary viewer access to the relevant Search Console property so live tests reflect the true index state.
You can partly fetch googlebot results with curl headers and validators without property access. For full context, request viewer access so each live url test reflects true index status and last crawl time.
Why does live test pass but the page stays unindexed?
Passing means the page is technically fetchable and eligible, not that it will be indexed. Google may still hold it for duplication, thin content, weak internal links, or low site quality signals. Check the Google selected canonical, compare content uniqueness against indexed competitors, review inlink counts and sitemap signals, and look at overall valid indexed trends. Fix quality and signal gaps first, then allow one to two crawl cycles for reassessment rather than retesting in a loop.
A passing live test means the page is fetchable, not guaranteed to index. Run a rendering test search console review, check canonical selection, and improve uniqueness and internal links before retesting.
How do I test JavaScript rendering for indexing?
Run URL Inspection live test and compare rendered HTML with raw source. Look for main content, links, and canonical tags that appear only after scripts run. Use the Rich Results Test to see rendered markup output. Check blocked resources that prevent script or style loading. For sitewide review, crawl with rendering enabled and diff raw versus rendered word counts. If key content depends on user actions or delayed loads, move it to server rendered HTML or pre rendered output so crawlers see it on first pass.
To test rendering google uses, compare raw source with rendered HTML in the live test. A quick render test tool pass plus a blocked resource review shows scripts or styles that hide main content.
Which tool checks robots.txt and noindex fastest?
For one URL, URL Inspection shows crawl allowed and index allowed in seconds. For patterns, fetch the live robots.txt, test paths in the robots tester, and crawl the section while recording X Robots Tag and meta robots per URL. Header checks catch server level noindex that view source misses. Group results by template to find the source file or plugin rule. Fix the narrowest rule that clears priority URLs, retest live, and watch the blocked and excluded counts fall over the next crawls.
For one URL, URL Inspection is fastest for robots and noindex status. These modern seo testing tools pair well with log checks when you need patterns, grouping results by template to find the source rule.
Should I test every URL after a site change?
No. Test by template, not by brute force. Pick two to three sample URLs per template, including one priority page, one deep page, and one edge case such as paginated or filtered output. Run the full sequence on samples, fix templates, then let crawlers and sitemaps propagate the improvement. Monitor section level valid counts and log based crawl frequency. Reserve bulk inspection for small batches of money pages. Steady template fixes scale better than testing thousands of URLs one by one.
Test by template with two to three samples rather than every URL. This fetch and render alternative scales better, letting crawlers propagate template fixes while you monitor section level valid counts.