Crawl Budget Explained: How Google Decides What to Index
This guide is for site owners, developers and SEOs who work with crawl budget and need a clear routine without guesswork. Many teams see the same pattern: coverage reports stall, crawl stats swing, and stakeholders ask when priority pages will appear in results. The facts help here. Plan for efficient crawling, clean sitemaps, honest quality signals and steady measurement. You will learn exact checks, safe defaults, templates to copy and a review rhythm that fits a busy week. Follow the sections in order, test on a small sample first, then scale once responses and reports stay clean. The focus keyword crawl budget appears where it helps mapping, never as filler.
Key takeaways
- What crawl budget actually means for site owners sets the base: fast stable responses plus clean discovery signals for priority pages.
- How large sites waste crawl budget without knowing it matters most for large sites, where filters and variants consume visits.
- Track crawl stats, coverage and logs together for two week windows before judging a fix.
- Fix templates once, keep sitemaps accurate, and review monthly so gains hold.
- What crawl budget actually means for site owners
- How Google calculates crawl limit and crawl demand
- Why small sites rarely need to worry about crawl budget
- How large sites waste crawl budget without knowing it
- Practical ways to protect and improve crawl budget
- How sitemaps internal links and speed affect crawl budget
- How to measure crawl budget improvements over time
- FAQ
- Sources
- Further reading
 <!-- IMAGE-PROMPT cover: 1200x630, DependsIt brand, deep charcoal #121212 background with vibrant mint #22E3B0 accent glow, thin node-network line art, Clash Display style bold heading space on left, General Sans clean labels, subject: crawl budget cover illustration, flat vector, high contrast, accessible, no photorealistic faces, no text smaller than 24px, no em dash in rendered text, export PNG then cwebp -q 82 to WEBP -->
What crawl budget actually means for site owners
This section covers what crawl budget actually means for site owners in the context of crawl budget. Crawl budget is the number of pages Googlebot can and wants to fetch from your site in a given period. It combines server capacity with demand signals such as popularity and freshness. Owners who grasp this split stop chasing myths and start fixing fetch waste, slow responses and weak internal signals. We keep the advice practical for owners without a large team. Each check below uses Search Console, logs and a small crawl you can run today. The goal is steady progress you can see in coverage, not a one time spike. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates.
Google discovers most pages through crawl, not through a single submission. A submission is a hint that asks for a fresh look, but ranking and storage still depend on quality, uniqueness and site trust. That is why steady technical hygiene matters more than any one push. Keep response times low, avoid redirect chains, and return clear status codes. When the crawler can fetch quickly and without loops, each hint carries more weight and uses less of your daily allowance.
| Item | What to record | Where to check |
|---|---|---|
| URL group | Template plus parameter pattern | Crawl export by path |
| Fetch | Status plus response time | Logs and crawl stats |
| Signal | Sitemap plus internal inlinks | Sitemap index and crawler |
| Action | Allow, canonical, noindex or fix | Change log with date |
Google does not support IndexNow, so plan for two ecosystems. IndexNow notifies Bing, Yandex, Naver, Seznam and other partners that share the protocol, while Google relies on sitemaps, Search Console inspection and the Indexing API for eligible types. A practical setup sends product updates to both paths at publish time. One worker prepares the URL list, then one branch pings IndexNow endpoints and another branch queues Google notifications within quota. Coverage improves without double counting.
Internal linking does more for indexing than most teams expect. New URLs that sit four clicks from the home page may wait days for a visit, while URLs linked from a popular category or a recent posts block get visited quickly. Add new products to relevant category pages, link related items, and keep pagination crawlable with plain anchors. Avoid loading key links only through scripts that require clicks. Simple, stable links help both Google and IndexNow driven crawlers find changes fast.
Thin or duplicated content slows indexing because Google prioritizes pages likely to satisfy searchers. Short product descriptions copied from suppliers, empty category pages and near duplicate articles often sit in Discovered or Crawled without indexing. Add specific details such as dimensions, materials, compatibility, usage steps and original photos. Consolidate near duplicates into one strong page with redirects. Better content earns more frequent revisits and steadier indexing.
In practice, make a short runbook for what crawl budget actually means for site owners and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
How Google calculates crawl limit and crawl demand
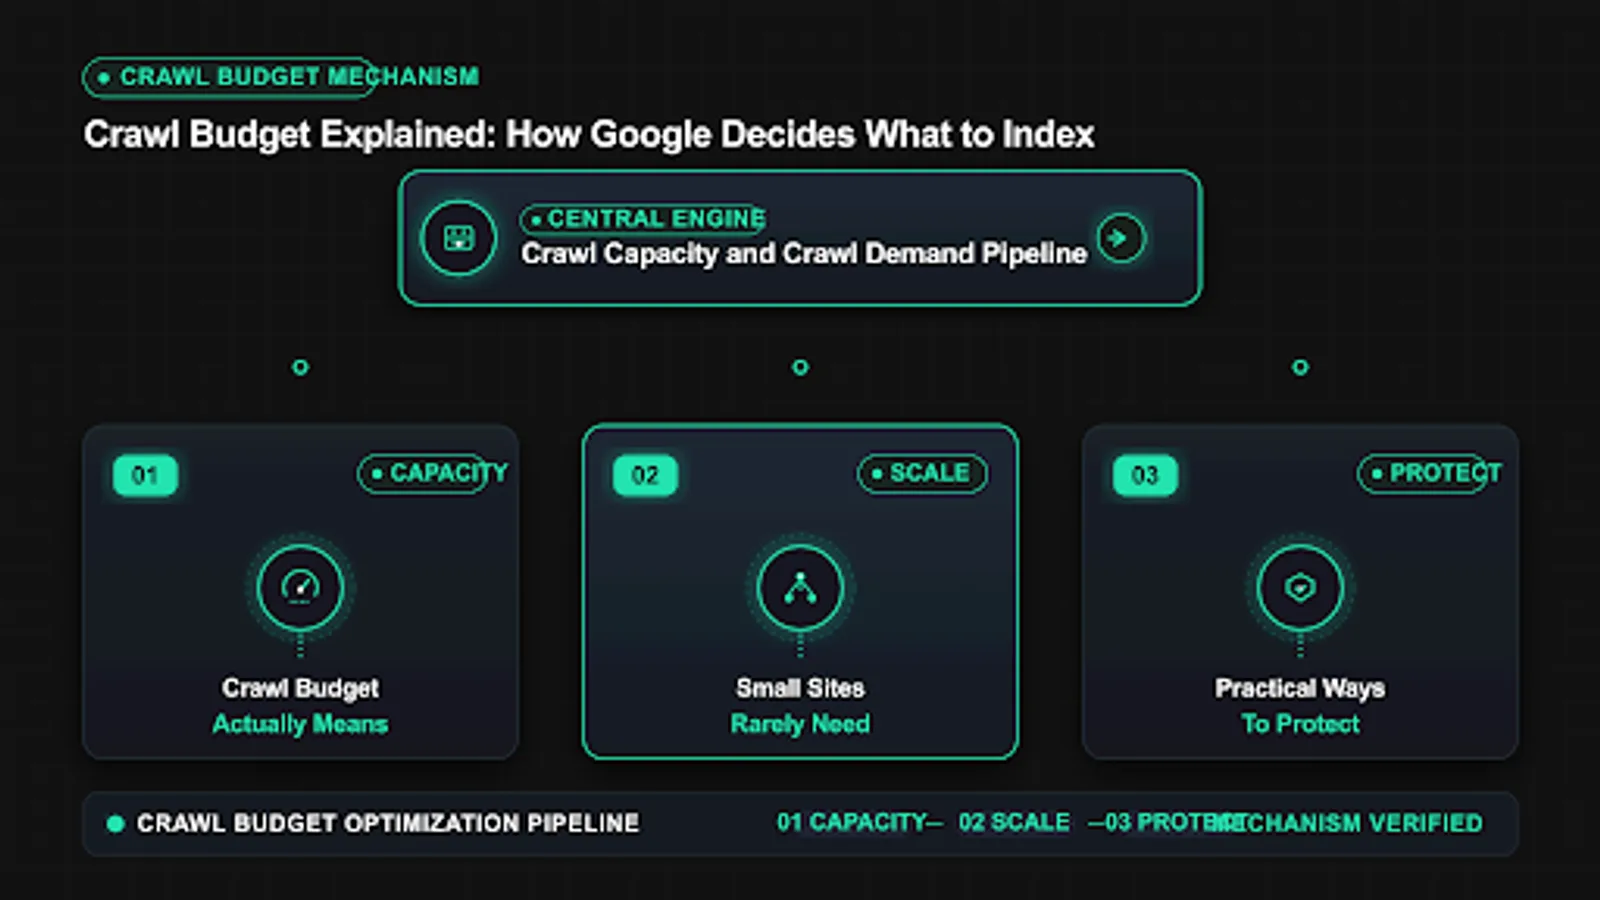
This section covers how google calculates crawl limit and crawl demand in the context of crawl budget. Google balances how much your server can handle with how much your pages deserve. Crawl limit reflects host health and response speed, while crawl demand reflects popularity, update frequency and link signals. When both are strong, more URLs get visited. When either drops, visits shrink. We keep the advice practical for owners without a large team. Each check below uses Search Console, logs and a small crawl you can run today. The goal is steady progress you can see in coverage, not a one time spike. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates.
Crawl capacity is often misunderstood. For small sites it rarely limits indexing, but for catalogs with 50000 to 500000 URLs it shapes what gets visited each day. Facets, session parameters, internal search results and duplicate variants can trap crawlers in low value loops. Use robots rules to block filtered views, use canonical tags to consolidate variants, and link best sellers from the home page and category hubs. Fewer dead ends means faster visits to new and updated pages.
- Step 1: Open crawl stats for 90 days and note requests, host load and response mix.
- Step 2: Sample 50 URLs from each spike and label template plus cause.
- Step 3: Fix server, robots or link cause once per template rather than per URL.
- Step 4: Update sitemaps and internal links to point only to keepers.
- Step 5: Recheck stats and coverage after one full crawl cycle.
A 429 means slow down, not try harder. Read the Retry After header when present, then wait with exponential backoff and jitter before retrying. A common pattern waits 2 seconds, then 4, then 8, then 16, with a small random addition to avoid synchronized retries. Cap retries at 4 or 5 and move the URL to a delayed queue after that. Hammering the endpoint during a limit only extends the block and burns log space.
Robots directives and meta tags can silently block indexing. A stray noindex in a template, an X Robots Tag header from a staging config, or a disallow in robots that covers new paths will keep pages out even after successful submission. Audit headers with a fetch tool, render pages as Googlebot, and check the coverage report for Excluded by noindex or Blocked by robots. Fix the template once rather than patching URLs one by one.
Speed and stability raise effective crawl capacity. Compress images, cache HTML at the edge where safe, trim heavy scripts and keep time to first byte steady under load. Monitor 5xx rate, redirect chains and DNS time alongside crawl stats. When the host answers quickly and consistently, Google can do more useful work per minute without raising risk for shoppers and readers.
In practice, make a short runbook for how google calculates crawl limit and crawl demand and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
For background on a related report, see how to read the crawl stats report which explains how fetch data maps to coverage decisions.
 <!-- IMAGE-PROMPT diagram-01: 1600px max, DependsIt brand mint #22E3B0 on charcoal #121212, node-network line art, Clash Display style headings feel with General Sans clean labels, subject: crawl budget diagram with crawl and queue nodes, flat vector, accessible, no em dash in rendered text -->
Why small sites rarely need to worry about crawl budget
This section covers why small sites rarely need to worry about crawl budget in the context of crawl budget. Sites under a few thousand URLs almost always get full coverage without special tuning. Google can fetch that volume quickly when responses are fast and links are clean. Small site issues usually trace to noindex, blocks or thin content rather than true budget caps. Knowing this saves weeks of wrong fixes. We keep the advice practical for owners without a large team. Each check below uses Search Console, logs and a small crawl you can run today. The goal is steady progress you can see in coverage, not a one time spike. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates.
The Google Indexing API only documents JobPosting and BroadcastEvent pages, which covers job listings and livestream video. Many site owners still test it for product or article URLs, but that use is off label and results vary. Google may process the hint, ignore it, or throttle it. State this plainly to stakeholders. Use the API for eligible content first, and rely on sitemaps, internal links and IndexNow for broad coverage on other page types.
| Check | Pass condition | Fix if failing |
|---|---|---|
| Robots | Priority paths allowed | Narrow wildcard scope |
| Sitemap | Only canonical 200 listed | Remove variants and errors |
| Links | Hub links present | Add contextual links |
| Speed | Stable fast responses | Cache and trim weight |
Internal linking does more for indexing than most teams expect. New URLs that sit four clicks from the home page may wait days for a visit, while URLs linked from a popular category or a recent posts block get visited quickly. Add new products to relevant category pages, link related items, and keep pagination crawlable with plain anchors. Avoid loading key links only through scripts that require clicks. Simple, stable links help both Google and IndexNow driven crawlers find changes fast.
Log analysis shows what crawlers actually did, not what dashboards assume. Group hits by user agent, path template, status code and hour to see waste and priority coverage. Look for Googlebot loops on calendars, filters and search pages, plus spikes after deploys. Share weekly summaries with developers and editors so fixes target the largest waste first. Evidence from logs keeps debates short and actions clear.
Sitemaps remain the backbone of discovery. A clean product or article sitemap lists only canonical, indexable URLs that return 200 and load quickly. Split large catalogs into chunks of 10000 to 40000 URLs, compress with gzip, and reference each chunk from a sitemap index. Update the lastmod field only when content truly changes. Submit the index in Search Console and keep it reachable. A tidy sitemap reduces wasted fetches and leaves room for priority pages.
In practice, make a short runbook for why small sites rarely need to worry about crawl budget and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
For official details, see crawl documentation which defines how crawling, politeness and host load interact.
How large sites waste crawl budget without knowing it
This section covers how large sites waste crawl budget without knowing it in the context of crawl budget. Large catalogs, marketplaces and publishers leak budget through facets, parameters, calendars, internal search and duplicate variants. Each low value fetch steals time from new products or fresh articles. Logs often show thousands of hits on filtered views while priority pages wait days for a revisit. We keep the advice practical for owners without a large team. Each check below uses Search Console, logs and a small crawl you can run today. The goal is steady progress you can see in coverage, not a one time spike. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates.
Quotas shape every automation decision. Many projects start with about 200 publish requests per day for URL notifications, plus per minute limits that trigger 429 when bursts arrive. Track usage in Cloud Console under APIs and Services, set alerts at 60 percent and 85 percent, and log each publish with timestamp, URL, response code and notification type. When you know your burn rate by hour, you can pace jobs, defer low priority URLs and avoid midnight surprises.
- Step 1: Open crawl stats for 90 days and note requests, host load and response mix.
- Step 2: Sample 50 URLs from each spike and label template plus cause.
- Step 3: Fix server, robots or link cause once per template rather than per URL.
- Step 4: Update sitemaps and internal links to point only to keepers.
- Step 5: Recheck stats and coverage after one full crawl cycle.
Robots directives and meta tags can silently block indexing. A stray noindex in a template, an X Robots Tag header from a staging config, or a disallow in robots that covers new paths will keep pages out even after successful submission. Audit headers with a fetch tool, render pages as Googlebot, and check the coverage report for Excluded by noindex or Blocked by robots. Fix the template once rather than patching URLs one by one.
Google discovers most pages through crawl, not through a single submission. A submission is a hint that asks for a fresh look, but ranking and storage still depend on quality, uniqueness and site trust. That is why steady technical hygiene matters more than any one push. Keep response times low, avoid redirect chains, and return clear status codes. When the crawler can fetch quickly and without loops, each hint carries more weight and uses less of your daily allowance.
Search Console verification is the gate for any Google workflow. The property must be verified with the correct scheme and subdomain, and team access must match the property type. Domain properties and URL prefix properties behave differently, so confirm which one you use before debugging coverage. If you see permission issues, check sharing settings first, then property match, then URL exactness. Most access confusion traces to a missed property detail, not to code.
In practice, make a short runbook for how large sites waste crawl budget without knowing it and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
To compare link and structure fixes, read how internal linking speeds up indexing before you edit templates or navigation.
Practical ways to protect and improve crawl budget
This section covers practical ways to protect and improve crawl budget in the context of crawl budget. Protection starts with faster responses, cleaner URL space and stronger signals for priority pages. Fix server errors, compress images, cache well and cut redirect chains. Block low value patterns in robots, consolidate duplicates with canonicals and link important pages from hubs that Google visits often. We keep the advice practical for owners without a large team. Each check below uses Search Console, logs and a small crawl you can run today. The goal is steady progress you can see in coverage, not a one time spike. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates.
A 403 usually points to permissions or scope. Confirm the service account email has Owner access in Search Console, confirm the OAuth scope includes the indexing scope, and confirm the JSON key file matches the active key in Cloud Console. Check clock skew on the server, since JWT auth fails when time drifts by more than a few minutes. Rotate keys on a schedule, store them in a secret manager, and never paste private keys into chat tools or shared docs.
| Signal | Meaning | Next step |
|---|---|---|
| 200 OK | Fetch succeeded | Check index selection next |
| 301 moved | Redirect seen | Update links and sitemap |
| 404 missing | No page found | Remove from sitemap, fix links |
| 500 error | Server failed | Fix origin, then recheck |
Log analysis shows what crawlers actually did, not what dashboards assume. Group hits by user agent, path template, status code and hour to see waste and priority coverage. Look for Googlebot loops on calendars, filters and search pages, plus spikes after deploys. Share weekly summaries with developers and editors so fixes target the largest waste first. Evidence from logs keeps debates short and actions clear. Teams that monitor the googlebot crawl limit alongside response mix can save crawl budget for priority templates instead of spending visits on filters and search internals.
Crawl capacity is often misunderstood. For small sites it rarely limits indexing, but for catalogs with 50000 to 500000 URLs it shapes what gets visited each day. Facets, session parameters, internal search results and duplicate variants can trap crawlers in low value loops. Use robots rules to block filtered views, use canonical tags to consolidate variants, and link best sellers from the home page and category hubs. Fewer dead ends means faster visits to new and updated pages.
Google does not support IndexNow, so plan for two ecosystems. IndexNow notifies Bing, Yandex, Naver, Seznam and other partners that share the protocol, while Google relies on sitemaps, Search Console inspection and the Indexing API for eligible types. A practical setup sends product updates to both paths at publish time. One worker prepares the URL list, then one branch pings IndexNow endpoints and another branch queues Google notifications within quota. Coverage improves without double counting.
In practice, make a short runbook for practical ways to protect and improve crawl budget and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
User-agent: *
Disallow: /search/
Disallow: /cart/
Disallow: /*?color=
Disallow: /*?sort=

Sitemap: /sitemap_index.xml
How sitemaps internal links and speed affect crawl budget
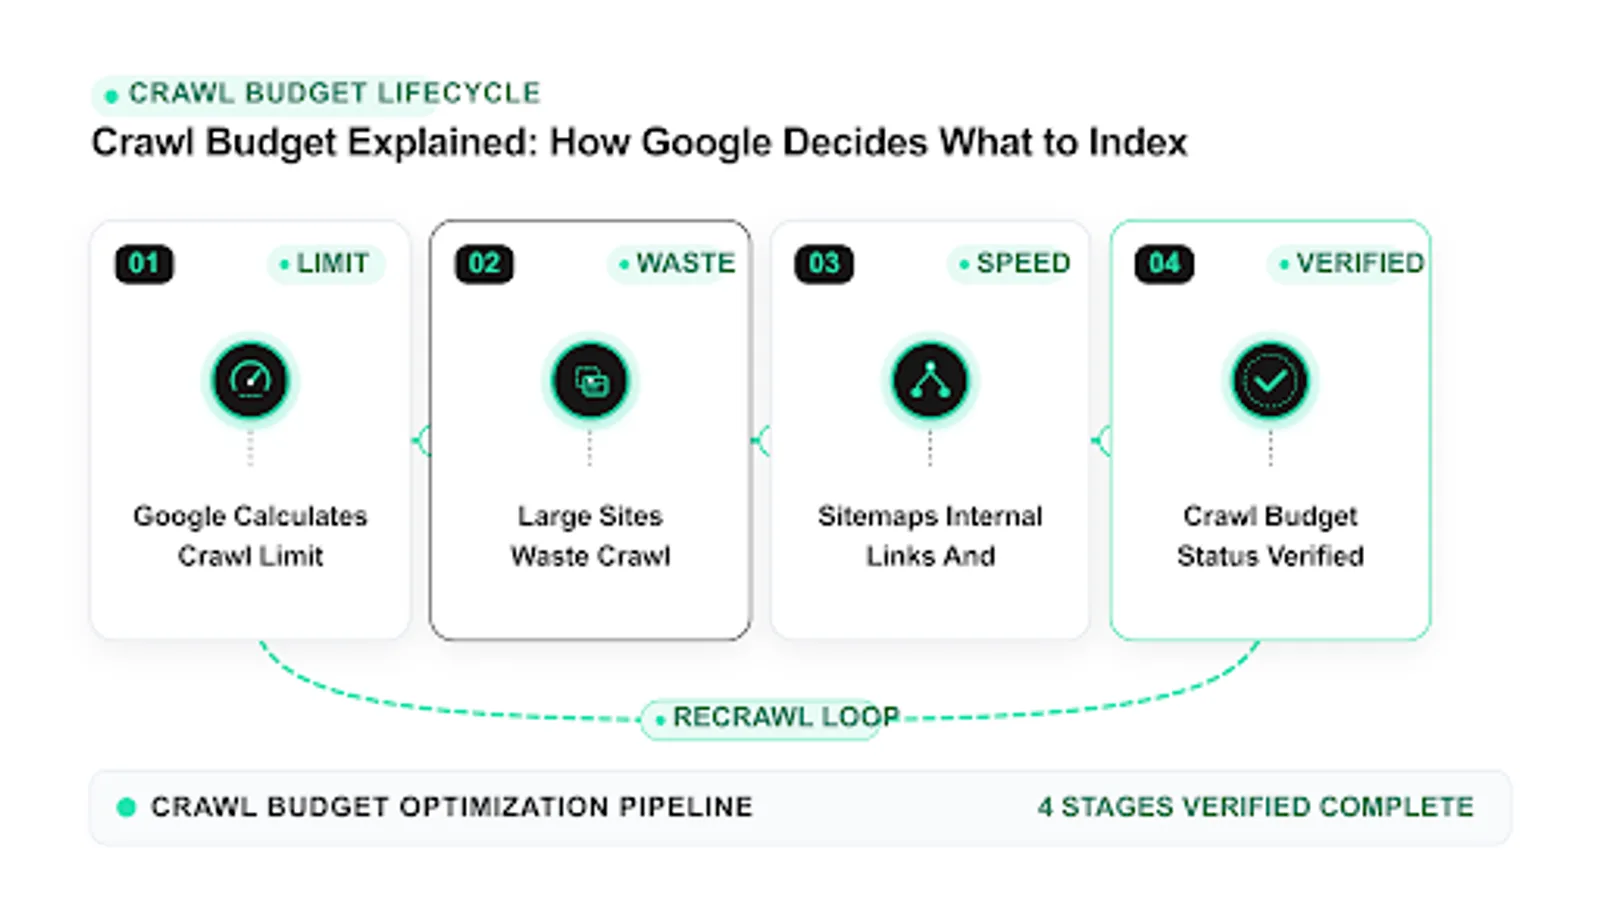
This section covers how sitemaps internal links and speed affect crawl budget in the context of crawl budget. Sitemaps guide, links invite and speed permits. A clean sitemap lists only canonical indexable URLs with true lastmod. Internal links from homepage and category hubs raise demand for targets. Fast stable responses raise the limit. Together they let Google do more useful work per visit without extra load. We keep the advice practical for owners without a large team. Each check below uses Search Console, logs and a small crawl you can run today. The goal is steady progress you can see in coverage, not a one time spike. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates.
Canonical tags decide which URL keeps the indexing credit. If variants with color, size or tracking parameters lack a canonical, Google may pick a different URL or delay indexing while it compares duplicates. Point each variant to the preferred canonical, keep the canonical self referencing on the main URL, and make sure sitemaps list only canonicals. For translated or regional pages, add hreflang and keep each locale self consistent. Clean signals shorten the decision time.
- Step 1: Open crawl stats for 90 days and note requests, host load and response mix.
- Step 2: Sample 50 URLs from each spike and label template plus cause.
- Step 3: Fix server, robots or link cause once per template rather than per URL.
- Step 4: Update sitemaps and internal links to point only to keepers.
- Step 5: Recheck stats and coverage after one full crawl cycle.
Google discovers most pages through crawl, not through a single submission. A submission is a hint that asks for a fresh look, but ranking and storage still depend on quality, uniqueness and site trust. That is why steady technical hygiene matters more than any one push. Keep response times low, avoid redirect chains, and return clear status codes. When the crawler can fetch quickly and without loops, each hint carries more weight and uses less of your daily allowance.
The Google Indexing API only documents JobPosting and BroadcastEvent pages, which covers job listings and livestream video. Many site owners still test it for product or article URLs, but that use is off label and results vary. Google may process the hint, ignore it, or throttle it. State this plainly to stakeholders. Use the API for eligible content first, and rely on sitemaps, internal links and IndexNow for broad coverage on other page types.
A 429 means slow down, not try harder. Read the Retry After header when present, then wait with exponential backoff and jitter before retrying. A common pattern waits 2 seconds, then 4, then 8, then 16, with a small random addition to avoid synchronized retries. Cap retries at 4 or 5 and move the URL to a delayed queue after that. Hammering the endpoint during a limit only extends the block and burns log space.
In practice, make a short runbook for how sitemaps internal links and speed affect crawl budget and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
 <!-- IMAGE-PROMPT workflow-02: 1600px max, DependsIt brand mint #22E3B0 on charcoal #121212 or white, node-network line art, Clash Display style headings feel with General Sans clean labels, subject: crawl budget workflow with review and audit steps, flat vector, accessible, no em dash in rendered text -->
How to measure crawl budget improvements over time
This section covers how to measure crawl budget improvements over time in the context of crawl budget. Measurement ties actions to outcomes using crawl stats, logs and coverage. Track fetches per day, response mix, time spent downloading and the share of visits to priority templates. Watch Valid indexed growth and the fall of Discovered and Crawled without indexing. Keep a change log so wins repeat. We keep the advice practical for owners without a large team. Each check below uses Search Console, logs and a small crawl you can run today. The goal is steady progress you can see in coverage, not a one time spike. Keep notes on what you change and when, so indexing movement links clearly to specific fixes and dates.
Thin or duplicated content slows indexing because Google prioritizes pages likely to satisfy searchers. Short product descriptions copied from suppliers, empty category pages and near duplicate articles often sit in Discovered or Crawled without indexing. Add specific details such as dimensions, materials, compatibility, usage steps and original photos. Consolidate near duplicates into one strong page with redirects. Better content earns more frequent revisits and steadier indexing.
| Item | What to record | Where to check |
|---|---|---|
| URL group | Template plus parameter pattern | Crawl export by path |
| Fetch | Status plus response time | Logs and crawl stats |
| Signal | Sitemap plus internal inlinks | Sitemap index and crawler |
| Action | Allow, canonical, noindex or fix | Change log with date |
Crawl capacity is often misunderstood. For small sites it rarely limits indexing, but for catalogs with 50000 to 500000 URLs it shapes what gets visited each day. Facets, session parameters, internal search results and duplicate variants can trap crawlers in low value loops. Use robots rules to block filtered views, use canonical tags to consolidate variants, and link best sellers from the home page and category hubs. Fewer dead ends means faster visits to new and updated pages.
Quotas shape every automation decision. Many projects start with about 200 publish requests per day for URL notifications, plus per minute limits that trigger 429 when bursts arrive. Track usage in Cloud Console under APIs and Services, set alerts at 60 percent and 85 percent, and log each publish with timestamp, URL, response code and notification type. When you know your burn rate by hour, you can pace jobs, defer low priority URLs and avoid midnight surprises.
Internal linking does more for indexing than most teams expect. New URLs that sit four clicks from the home page may wait days for a visit, while URLs linked from a popular category or a recent posts block get visited quickly. Add new products to relevant category pages, link related items, and keep pagination crawlable with plain anchors. Avoid loading key links only through scripts that require clicks. Simple, stable links help both Google and IndexNow driven crawlers find changes fast.
For a large site crawl budget review, group wasted hits by template and track crawl budget factors such as error share, redirect chains, and thin duplicates in a short crawl budget guide you reuse each month. In practice, make a short runbook for how to measure crawl budget improvements over time and review it after each deploy. List who owns Search Console, where logs live, which sitemap covers the URLs and what alert fires first. Test with a small sample before wider rollout. Record status codes and timestamps so patterns appear without guesswork. If errors rise, pause, fix the root cause, then resume at half pace. Steady documented pacing beats rushing to catch up in one burst. Share the runbook with developers and editors so ownership stays clear through staff changes and seasonal peaks.
FAQ
What is crawl budget in simple terms?
Crawl budget is the amount of attention Googlebot can give your site in a period. It reflects server capacity plus page demand. Improve both by serving fast responses and by earning links and updates for pages that matter. Keep a short log of what you checked and when, so the next review starts from evidence rather than memory. Small consistent records make the next incident faster to resolve and easier to explain.
Does every site need crawl budget optimization?
No. Small sites under a few thousand URLs rarely hit budget caps. Focus on eligibility, quality and links first. On crawl budget wordpress setups, the same rule applies: fix tag and attachment bloat before tuning anything else. Large sites with facets, feeds or millions of variants benefit most from budget work. Keep a short log of what you checked and when, so the next review starts from evidence rather than memory. Small consistent records make the next incident faster to resolve and easier to explain.
What wastes crawl budget fastest?
Faceted filters, session parameters, internal search results, calendar archives and duplicate variants waste the most. Each creates many low value URLs that consume fetches while priority pages wait. Keep a short log of what you checked and when, so the next review starts from evidence rather than memory. Small consistent records make the next incident faster to resolve and easier to explain.
How do sitemaps help crawl budget?
Clean sitemaps point Google to canonical indexable URLs and reduce guessing. List only 200 pages with accurate lastmod. Remove redirects, noindex pages and variants so each fetch has a better chance to help indexing. Keep a short log of what you checked and when, so the next review starts from evidence rather than memory. Small consistent records make the next incident faster to resolve and easier to explain.
How long until budget fixes show results?
Expect one to three crawl cycles, often two to six weeks for large sites. Watch crawl stats for fewer wasted hits and coverage for growth in Valid pages. Keep changes stable during the window. Keep a short log of what you checked and when, so the next review starts from evidence rather than memory. Small consistent records make the next incident faster to resolve and easier to explain.
Can IndexNow replace crawl budget work?
No. Google does not support IndexNow, so IndexNow helps Bing and Yandex family engines while Google still relies on efficient crawling. Use both paths with tidy sitemaps for full coverage. Keep a short log of what you checked and when, so the next review starts from evidence rather than memory. Small consistent records make the next incident faster to resolve and easier to explain.